

Qwen 4 Max is worth a few days of hands-on use in your coding tool, and nothing more yet. The preview (qwen4-max-preview) has a 1M-token context and 393,216 max output, but Alibaba published no benchmarks and no per-token price. It only runs on the Token Plan subscription, which bans app backends, and it retires on November 25, 2026. Try it while credits cost 20% of the standard rate. Build on Qwen 3.8 Max instead. For support work, a helpdesk agent like eesel runs on stable models, and with the eesel CLI a coding agent can load your help articles and test answers before anything goes live.
What is Qwen 4 Max?
Qwen 4 Max is the first model of Alibaba's Qwen 4 generation, and right now it exists only as a preview. Alibaba's model docs call qwen4-max-preview "the next-generation flagship multimodal model in the Qwen family," built for coding, office work, frontend design and agent tasks.
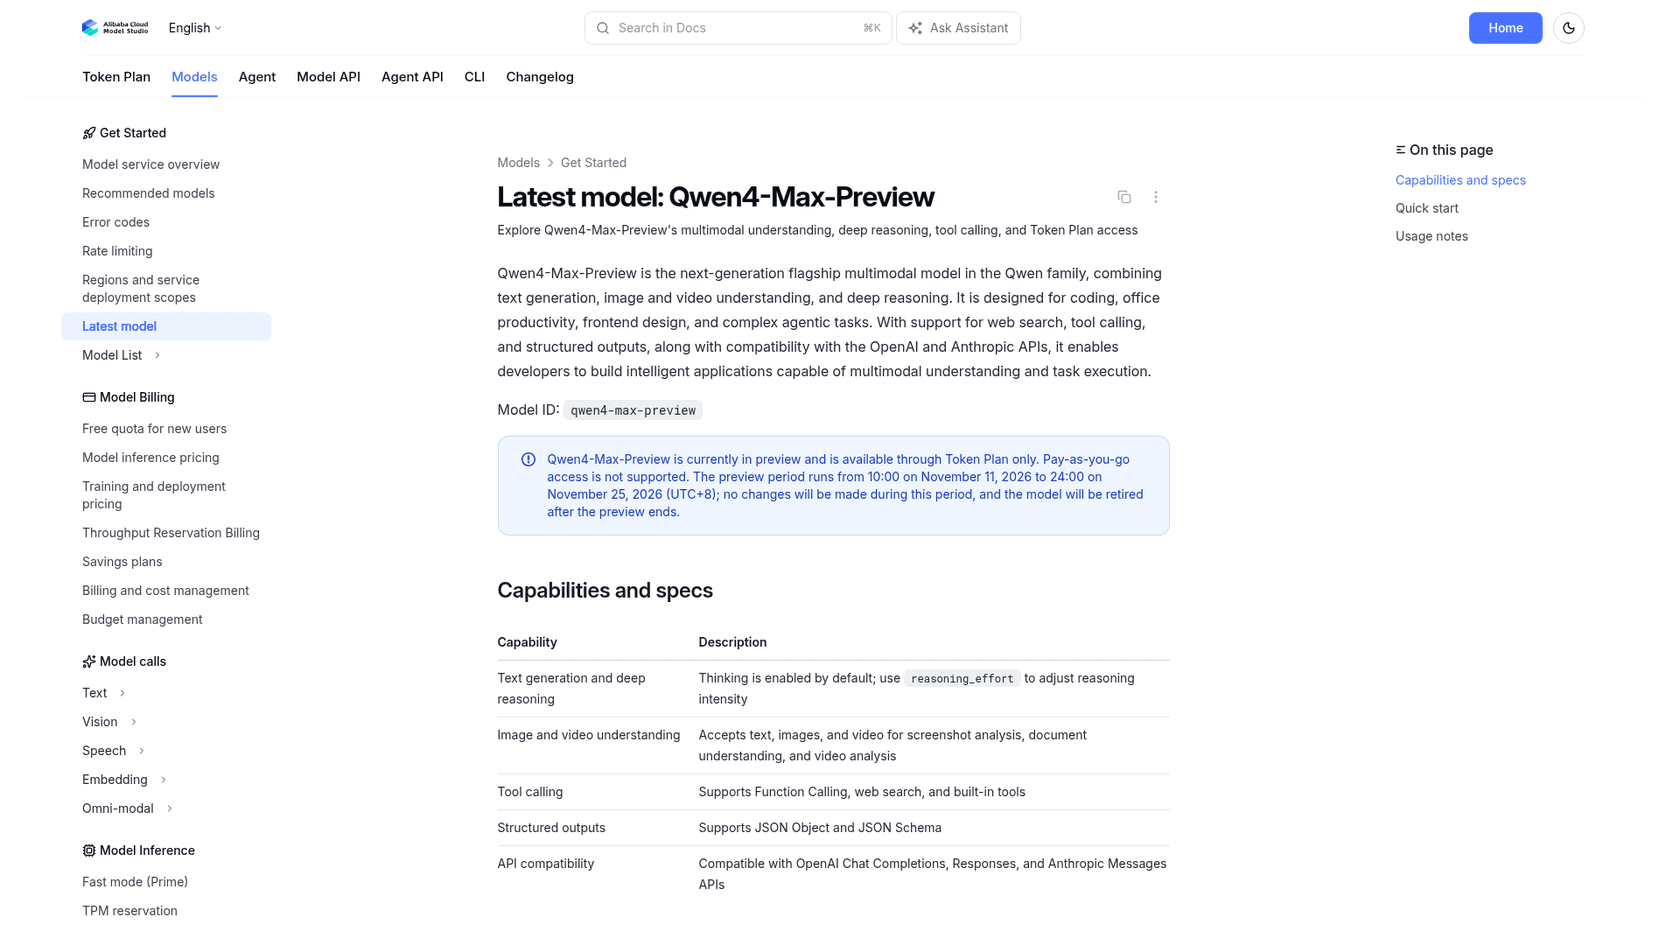
It went live on November 11, 2026 at 10:00 Beijing time. Here is what the docs confirm:
| Spec | Qwen4-Max-Preview |
|---|---|
| Model ID | qwen4-max-preview (alias qwen4.0-max-preview) |
| Input | Text, images and video |
| Context length | 1M tokens |
| Max output | 393,216 tokens, shared by thinking and answer |
| Thinking | On by default, low, medium or xhigh (default) |
| Tools | Function calling, web search, built-in tools |
| Structured output | JSON Object and JSON Schema |
| API formats | OpenAI Chat Completions, Responses, Anthropic Messages |
| Access | Token Plan only, no pay-as-you-go |
| Preview window | Nov 11 to Nov 25, 2026 (UTC+8), then retired |
Part of my job is checking what a launch actually promises before anyone builds on it. So before how the model feels, here's what's missing. Next to the Qwen 3.8 Max launch, this one is much thinner.
What did Alibaba leave out?
Alibaba published capabilities and limits, but not the numbers you'd normally use to judge a model. The docs page has no benchmark table. There's no parameter count, no model card, no open weights and no per-token price. When I checked on November 12, Qwen 4 Max had no page on Artificial Analysis either, while Qwen 3.8 Max is on that board.
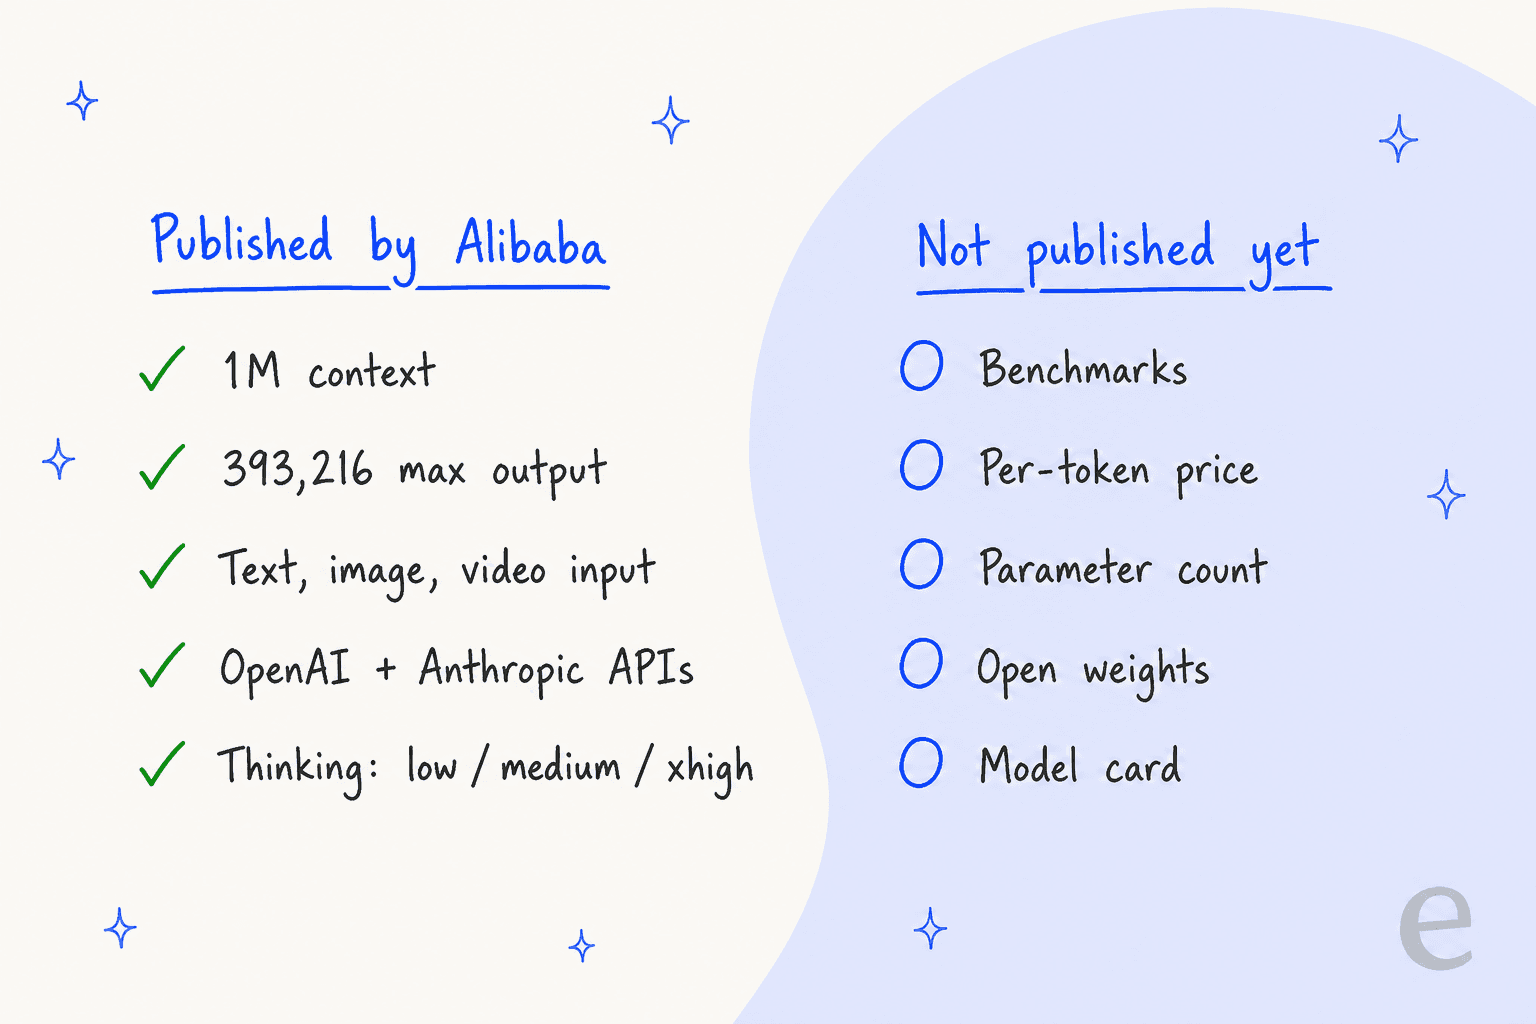
So any "Qwen 4 Max scores X" chart you see this week comes from a third party testing the preview, not from Alibaba. That's not damning, previews often ship like this. But it means a review today is a review of the access terms, not the intelligence. The Hacker News launch thread said as much:
"No benchmarks yet. The smaller Qwen models are extremely popular for people running things locally, yet I don't know absolutely anyone running Qwen Max."

That second sentence matters too. The Qwen models people love are the small open ones like Qwen 3.8 Flash Next and the 27B. The Max tier is hosted-only, and this preview doesn't change that.
How do you get access, and what does it cost?
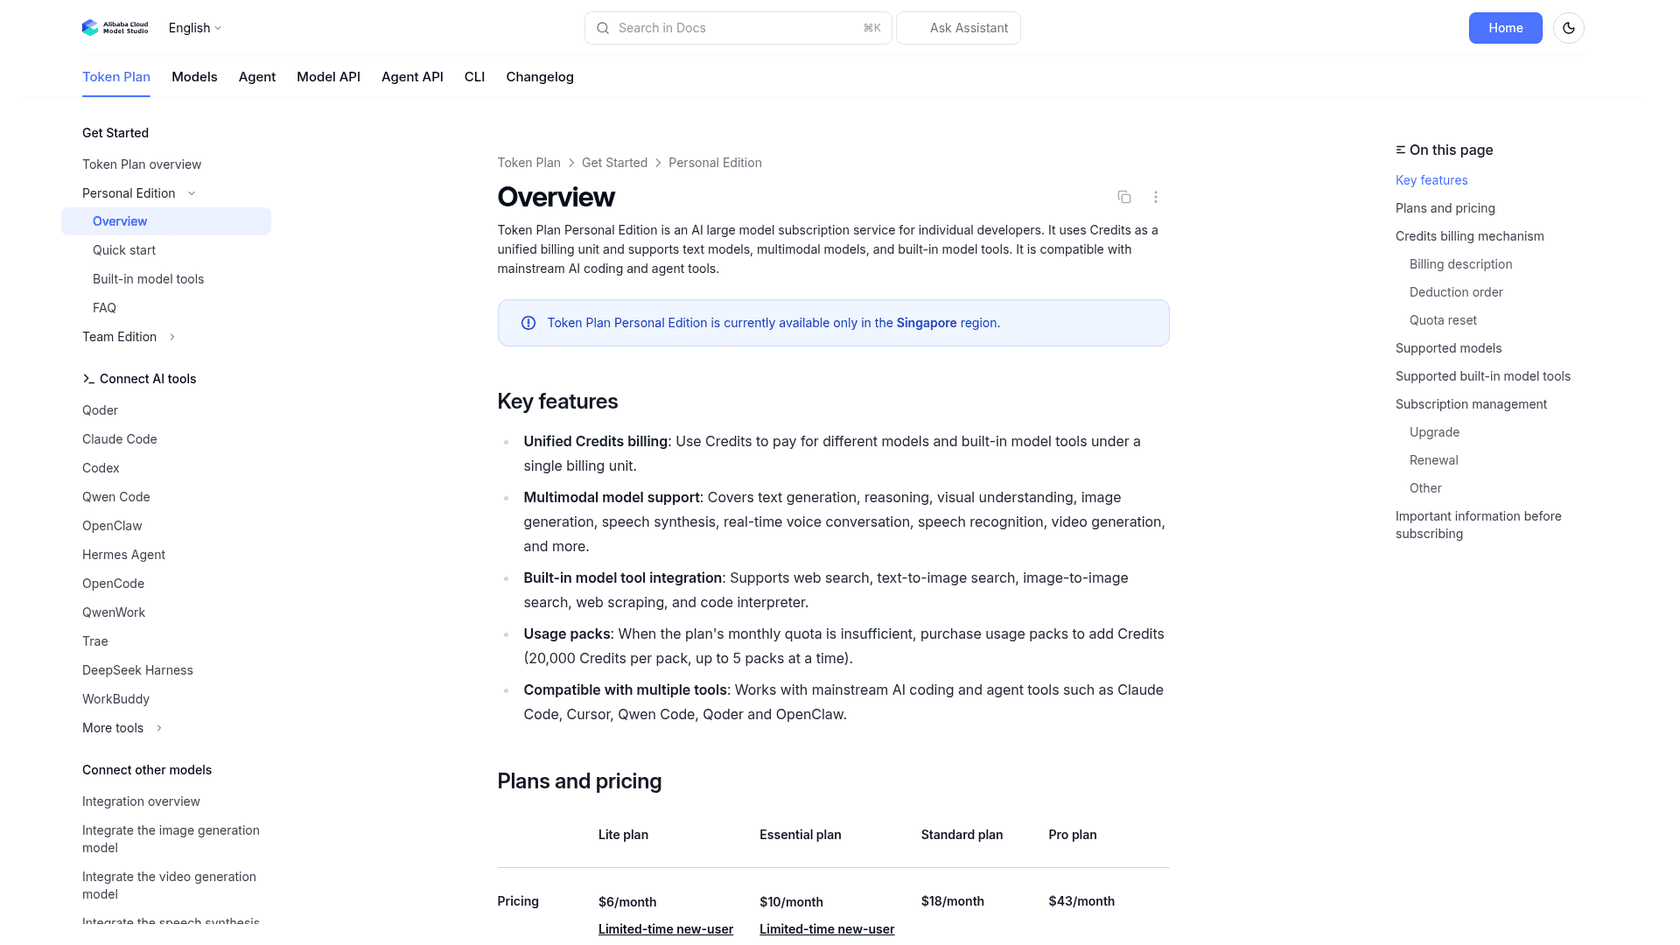
You get Qwen 4 Max through Alibaba's Token Plan, a monthly subscription paid in credits. There's no pay-as-you-go option for the preview. The Personal Edition prices come from Alibaba's Token Plan docs:
| Plan | List price | New-user price | Monthly credits | Concurrent agents |
|---|---|---|---|---|
| Lite | $6/month | $3/month | 20,000 | 1-2 |
| Essential | $10/month | $5/month | 45,000 | 2-3 |
| Standard | $18/month | - | 80,000 | 3-4 |
| Pro | $43/month | - | 200,000 | 6-8 |
The new-user price runs until November 30, 2026 for accounts that have never bought a Personal subscription. Extra bundles cost $15 for 20,000 credits, and you can hold up to five. The Personal Edition is Singapore-region only, and inference runs in Alibaba's Global deployment, so your prompts cross borders.
Here's the catch for anyone trying to compare costs. Alibaba says credits per request are "dynamically determined by model type, token usage, thinking mode, and tool calls," and it doesn't publish a credits-per-token rate for Qwen 4 Max. You find out what a call costs from the usage page in the console after you make it. So you can't price a job ahead of time the way you can with Qwen 3.8 Max, which lists $2 input and $6 output per 1M tokens on its QwenCloud model page.
The preview discount, and why "nights" means your workday
During the preview, Qwen 4 Max uses credits at 20% of the standard rate. Between 22:00 and 08:00 Beijing time, you get another 60% off, so 8% of the standard rate.
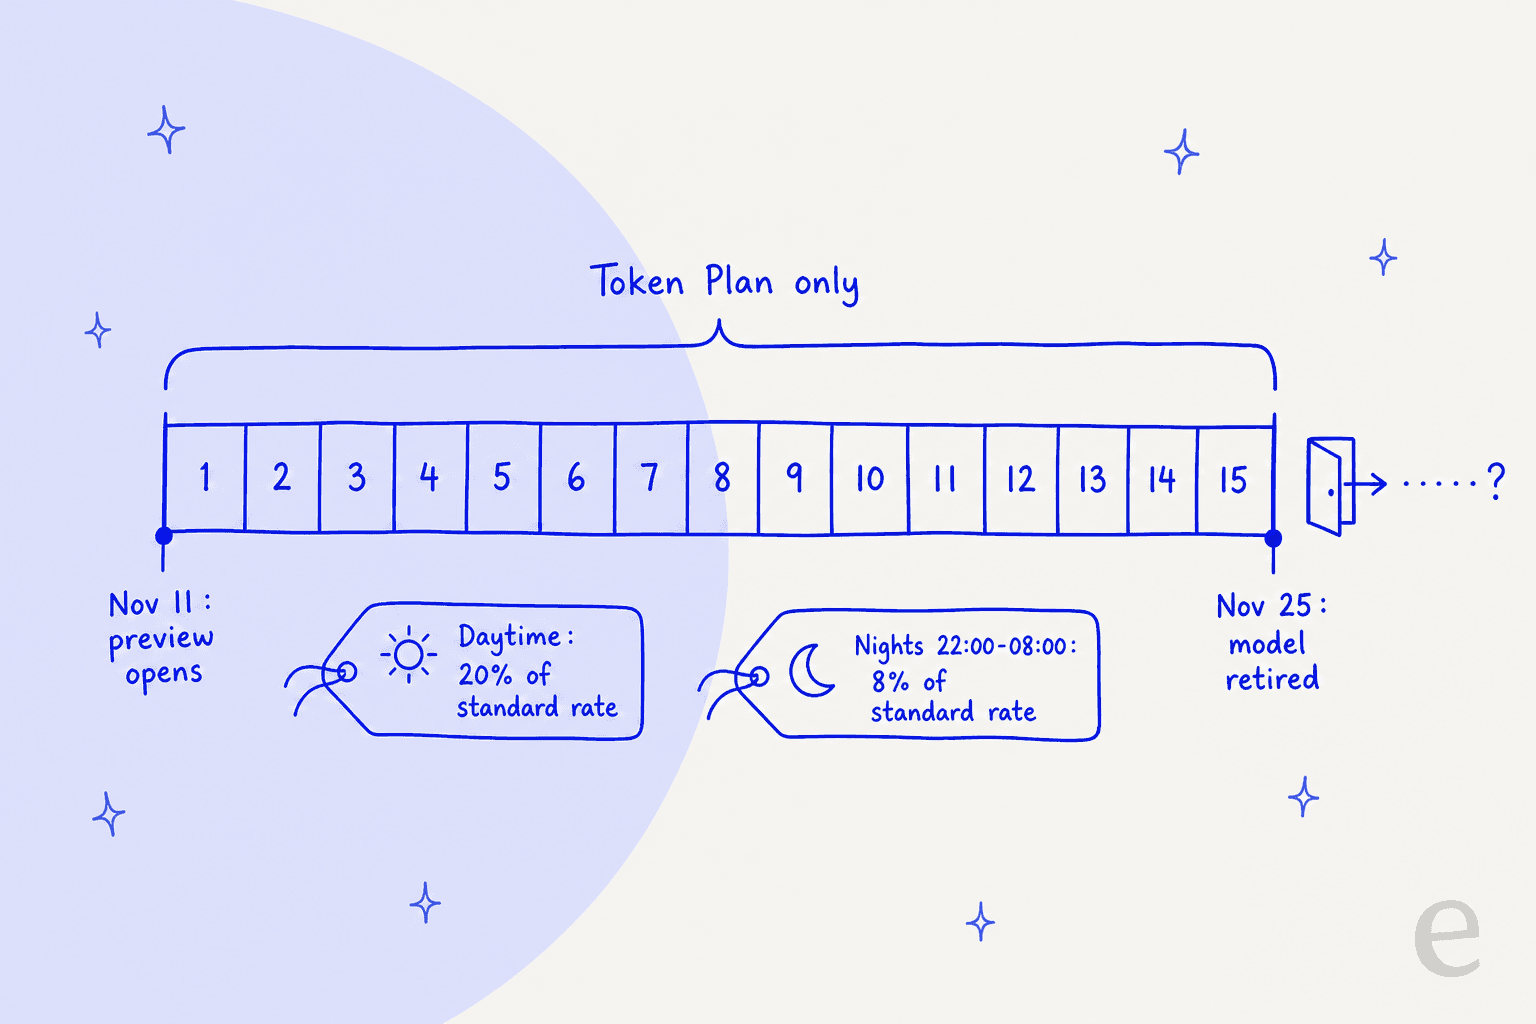
The detail most people miss: 22:00 to 08:00 in Beijing is 14:00 to 00:00 UTC. That's 9am to 7pm on the US East Coast. If you're in the Americas, the cheapest rate covers your whole working day. One early tester on Hacker News made the same point:
"By November 25th, Beijing time daytime (8am-22pm) -80%, and at night (Western daytime) even -92%!"
Can you build on Qwen 4 Max?
No, and this is the part of the review that matters most if you run a product or a support team. Two things rule it out.
First, the model is temporary. Alibaba's docs say "no changes will be made during this period, and the model will be retired after the preview ends." Anything you build on qwen4-max-preview stops working after November 25.
Second, Token Plan bans the use you'd need. The subscription terms say the plan is "intended for interactive use only within coding tools and agent tools," and that it "must not be used for automation scripts, custom application backends, or any non-interactive batch call scenarios." Calls outside that scope can get the subscription suspended or the API key banned.
So a support chatbot, a ticket classifier or any AI customer service API wired to this key would break the rules on day one. What the plan does allow is using the model inside Claude Code, Cursor, Qwen Code, OpenAI Codex, Cline, OpenCode or OpenClaw, all listed as supported tools.
Should you touch Qwen 4 Max this week?
Open the one that sounds like you.
I code in Claude Code, Cursor or Qwen Code every day
Yes. A $3 to $6 Lite plan gets you two weeks with a 1M context at 20% of the standard credit rate. Run it on a real task you already know the answer to, and compare it with your usual model.
I want to put it behind my app or a support bot
No. Token Plan bans app backends, and the model retires on November 25. Use a pay-as-you-go model like Qwen 3.8 Max now, and look at Qwen 4 Max again when a full release ships with a price.
I'm choosing a model for my company's roadmap
Wait. Without benchmarks or a rate card there is nothing to put in a cost model. Note the 393,216-token output limit and the new max_tokens behaviour, and revisit when Alibaba publishes numbers.
I run self-hosted Qwen models
Skip it. There are no open weights for the preview. The thing to watch is the smaller Qwen 4 models, since those are the ones that usually reach Hugging Face.
What changed for developers?
Two technical changes are worth knowing before you point a tool at it.
The bigger one is how max_tokens works. Starting with qwen4-max-preview, Alibaba's compatibility notice says max_tokens now equals max_completion_tokens, so it caps thinking and the final answer together. Thinking is on by default at xhigh. If your config sized max_tokens for the answer alone, long reasoning can eat the budget and cut your answer off. Older Qwen models keep the old behaviour, so this bites when you switch.
The second is multi-turn thinking. Chat Completions turns on preserve_thinking by default, and the docs ask you to send earlier thinking back in the reasoning_content field, not glued into content. Tools built for Anthropic or OpenAI formats may not do that out of the box, which is worth a check if long agent sessions go sideways.
The output ceiling itself is a real step up: 393,216 tokens, three times the 131,072 on Qwen 3.8 Max. For long code generation or large refactors in one pass, that's the spec I'd test first.
How does it feel to use?
Early reports are mixed and mostly about speed, which fits a model with thinking on xhigh by default. The Hacker News tester above said that "with xhigh thinking the speed is okay, feels slightly slower than Terra," meaning OpenAI's GPT-6.1 Terra. On X, the launch took a sceptical turn within hours:
"Qwen-4-max is live it seems. From what I've heard so far (rumors), Qwen 4 is disappointing."
Note the word "rumors." A reply under that post pushed back with actual use:
"It's preview; Qwen4-max-preview. It's not disappointing at all, at least so far in my one-shots, but more testing is going on and i'll have a clear answer."
Both are early, and neither is a benchmark. My honest read: nobody outside Alibaba knows how good Qwen 4 Max is yet, and the 14-day window plus "no changes during the preview" means the model you test is frozen. If you try it, try it on your own work, with a task you've already solved with Claude Fable 5.2 or GPT-6.1 Sol, so you have something real to compare with.
How does it compare with other models?
Here's how the preview sits next to the models people will actually weigh it against. Prices are from each vendor's own page, and I've marked what isn't published.
| Model | Status | Price | Max output | Independent scores |
|---|---|---|---|---|
| Qwen 4 Max preview | Preview, retires Nov 25 | Token Plan credits only | 393,216 | None yet |
| Qwen 3.8 Max | Released | $2 / $6 per 1M | 131,072 | Yes |
| Kimi K3 | Released | Kimi K3 pricing | See vendor | Yes |
| DeepSeek V4.1 Flash | Released, also on Token Plan | DeepSeek V4.1 Flash pricing | See vendor | Yes |
| GLM 5.3 Flash | Released | GLM 5.3 Flash pricing | See vendor | Yes |
The table says what the rest of this review says. Every other row is something you can price and check. Qwen 4 Max is the one you can only try.
What does this mean for a support team?
For a support team, Qwen 4 Max is a model to watch, not one to wire into your helpdesk. The question that comes up every launch week is whether to swap the support bot to the new model. With this one the answer is easy, because the rules and the retirement date decide it for you.
The bigger point holds for every launch, though. A raw model, however strong, isn't a support agent. The agent is everything around it: your help center, past tickets, macros, the rules for when to hand off to a person, and testing before anything reaches a customer. That's the layer eesel's AI helpdesk teammate is built to be. It joins your existing queue in Zendesk or Freshdesk, learns from your past tickets, and gets simulated against historical conversations before it answers anyone.
Two of our customers show what that looks like in practice:
- smava, a German loan comparison site, runs eesel on Zendesk across two brands. In one month it handled 27,000 tickets, categorised 14,600 and prepared 15,300 draft replies in German, working from 820 synced macros and help center articles.
- SamCart runs one agent on Freshdesk tickets and another on its website chat, answering from 280 help center articles.
Neither of those setups depends on whether this week's model wins a leaderboard. If you want to see what a model can do with your own support content, my guides on connecting Claude to your helpdesk and stopping AI hallucinations in support are a better use of the afternoon than a preview that retires in two weeks.
My verdict on Qwen 4 Max
Qwen 4 Max preview is a trial, not a product. The confirmed specs are strong, especially the 393,216-token output ceiling, and the preview discount makes a two-week test cheap. But with no benchmarks, no per-token price, a ban on backend use and a hard stop on November 25, there's nothing here to build on yet.
Try it if you live in a coding agent and want to test a long-context Qwen at 20% (or 8%) of the credit rate. Skip it if you need a model for an app, a support bot or a cost model. Use Qwen 3.8 Max now, and come back when Alibaba ships the full release.
Try eesel for support that doesn't wait on model launches
If your real goal is answering customers faster, eesel is an AI helpdesk teammate that plugs into the helpdesk you already use, learns from your past tickets and help center, and gets tested on historical conversations before it touches a live one. smava uses it to draft German replies across 27,000 Zendesk tickets a month. You can see the pricing or try eesel free.
Frequently Asked Questions
Is Qwen 4 Max out?
qwen4-max-preview (alias qwen4.0-max-preview), and it opened on November 11, 2026 at 10:00 Beijing time. Alibaba says the preview runs until November 25, 2026, then the model is retired. A full Qwen 4 Max release has not been announced yet. For the model it builds on, see my Qwen 3.8 Max review.How much does Qwen 4 Max cost?
Are there Qwen 4 Max benchmarks?
Can I use the Qwen 4 Max API in my app?
What is the difference between Qwen 4 Max and Qwen 3.8 Max?
max_tokens now caps thinking and answer together. See my Qwen 3.8 Max pricing breakdown.Does Qwen 4 Max work with Claude Code?
qwen4-max-preview. My Claude Code model selection guide explains how model switching works.