

Qwen 4 Max is Alibaba's next flagship model, and today you can only reach it as qwen4-max-preview on the Token Plan subscription, from $3 a month for new users, until November 25, 2026. It's a 1M-context, multimodal reasoning model with 393,216 max output. The setup is where people trip: Alibaba's own Claude Code config puts Qwen 4 Max in the Opus slot and the router auto in the main slot, so you may not be calling Qwen 4 Max unless you pick Opus. For AI on support tickets instead, eesel runs on stable models, and its eesel CLI lets a coding agent load help articles and test answers first.
What is Qwen 4 Max?
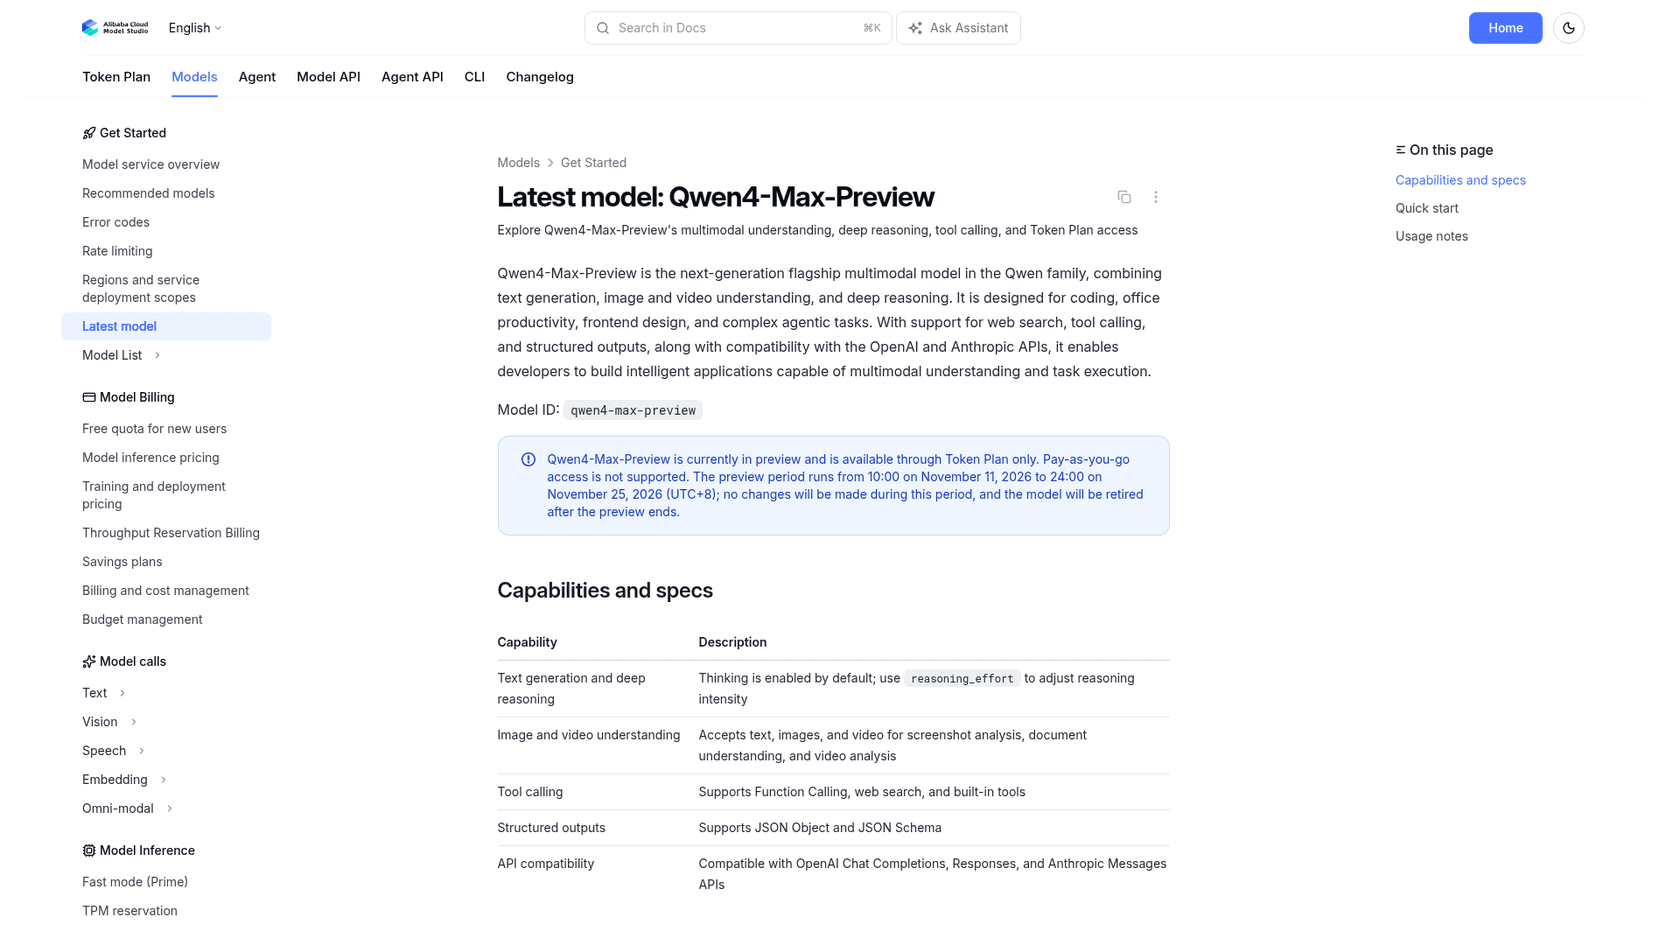
Qwen 4 Max is the first model in Alibaba's Qwen 4 generation, released on November 11, 2026 as a preview called qwen4-max-preview. Alibaba's model docs describe it as the next-generation flagship multimodal model in the Qwen family, aimed at coding, office work, frontend design and agent tasks.
I build integrations for a living at eesel, so when a new model ships my first question is boring: what do I put in the config, and what breaks when I do? This post answers that. If you want my take on whether the model is any good, that's in my colleague's Qwen 4 Max review.
Here is everything Alibaba has confirmed so far:
| Spec | Qwen 4 Max preview |
|---|---|
| Model ID | qwen4-max-preview (alias qwen4.0-max-preview, bills show the alias) |
| Input | Text, images and video |
| Context length | 1M tokens |
| Max output | 393,216 tokens, shared by thinking and the answer |
| Thinking | On by default; low, medium or xhigh (default) |
| Tools | Function calling, web search, built-in tools |
| Structured output | JSON Object and JSON Schema |
| API formats | OpenAI Chat Completions, Responses, Anthropic Messages |
| Access | Token Plan only, no pay-as-you-go |
| Availability | Nov 11, 10:00 to Nov 25, 24:00, 2026 (UTC+8), then retired |
There's no parameter count, no open weights, no model card and no benchmark table. That's normal for a two-week preview, but it means this is a model you try, not one you plan around.
Where does Qwen 4 Max sit in the Qwen lineup?
Qwen 4 Max sits at the top of Alibaba's hosted lineup, one step above Qwen 3.8 Max. The Token Plan model list puts them side by side, which is the clearest picture of what you can actually call today:
| Model ID on Token Plan | What Alibaba lists it for | Status |
|---|---|---|
qwen4-max-preview | Reasoning, visual understanding, text | Preview, retires Nov 25 |
qwen3.8-max | Reasoning, visual understanding, text | Released |
qwen3.8-flash | Reasoning, visual understanding, text | Released |
qwen3.7-max | Reasoning, text | Released |
qwen3.7-plus | Reasoning, visual understanding, text | Released |
qwen3.6-flash | Reasoning, visual understanding, text | Released |
auto | Picks a model per request | Platform router |
The same plan also carries DeepSeek V4.1 Flash, DeepSeek V4 Pro, GLM 5.3 and GLM 5.2, plus image, video and speech models. So one subscription gets you Qwen 4 Max next to a handful of models you can compare it with on the same task, which is the best use of the preview.
What's missing is the part a lot of people like most about Qwen: the smaller models they run locally. The Max tier is hosted-only, and the preview ships with no open weights. If you run Qwen on your own hardware, smaller Qwen 4 models are the ones to watch for, and Qwen 3.8 Flash Next is the current pick in the meantime.
How much does Qwen 4 Max cost?
There's no per-token price for Qwen 4 Max. You pay for a Token Plan subscription in credits, and Alibaba doesn't publish the standard credit rate for a Qwen 4 Max call, only the preview discount on it. The Personal Edition tiers come from the Token Plan docs:
| Plan | List price | New-user price | Monthly credits | Concurrent agents |
|---|---|---|---|---|
| Lite | $6/month | $3/month | 20,000 | 1-2 |
| Essential | $10/month | $5/month | 45,000 | 2-3 |
| Standard | $18/month | - | 80,000 | 3-4 |
| Pro | $43/month | - | 200,000 | 6-8 |
The new-user price runs until 23:59 on November 30, 2026 (UTC+8), for accounts that have never bought a Personal subscription. Extra bundles are $15 for 20,000 credits, up to five at a time. During the preview, Qwen 4 Max uses credits at 20% of the standard rate, and 8% between 22:00 and 08:00 Beijing time, which is the US working day.
Two things in the terms are worth reading before you pay. The Personal Edition can't be unsubscribed, so pick the shortest period. And unused credits don't roll over to the next month. For a two-week trial, the $3 Lite plan is all most people need. If you want a model with a rate card you can plan a budget against, Qwen 3.8 Max pricing is $2 input and $6 output per 1M tokens.
How do you get access to Qwen 4 Max?
You get access in three steps, per Alibaba's Token Plan quick start: subscribe, generate a key, and point your tool at the right endpoint.
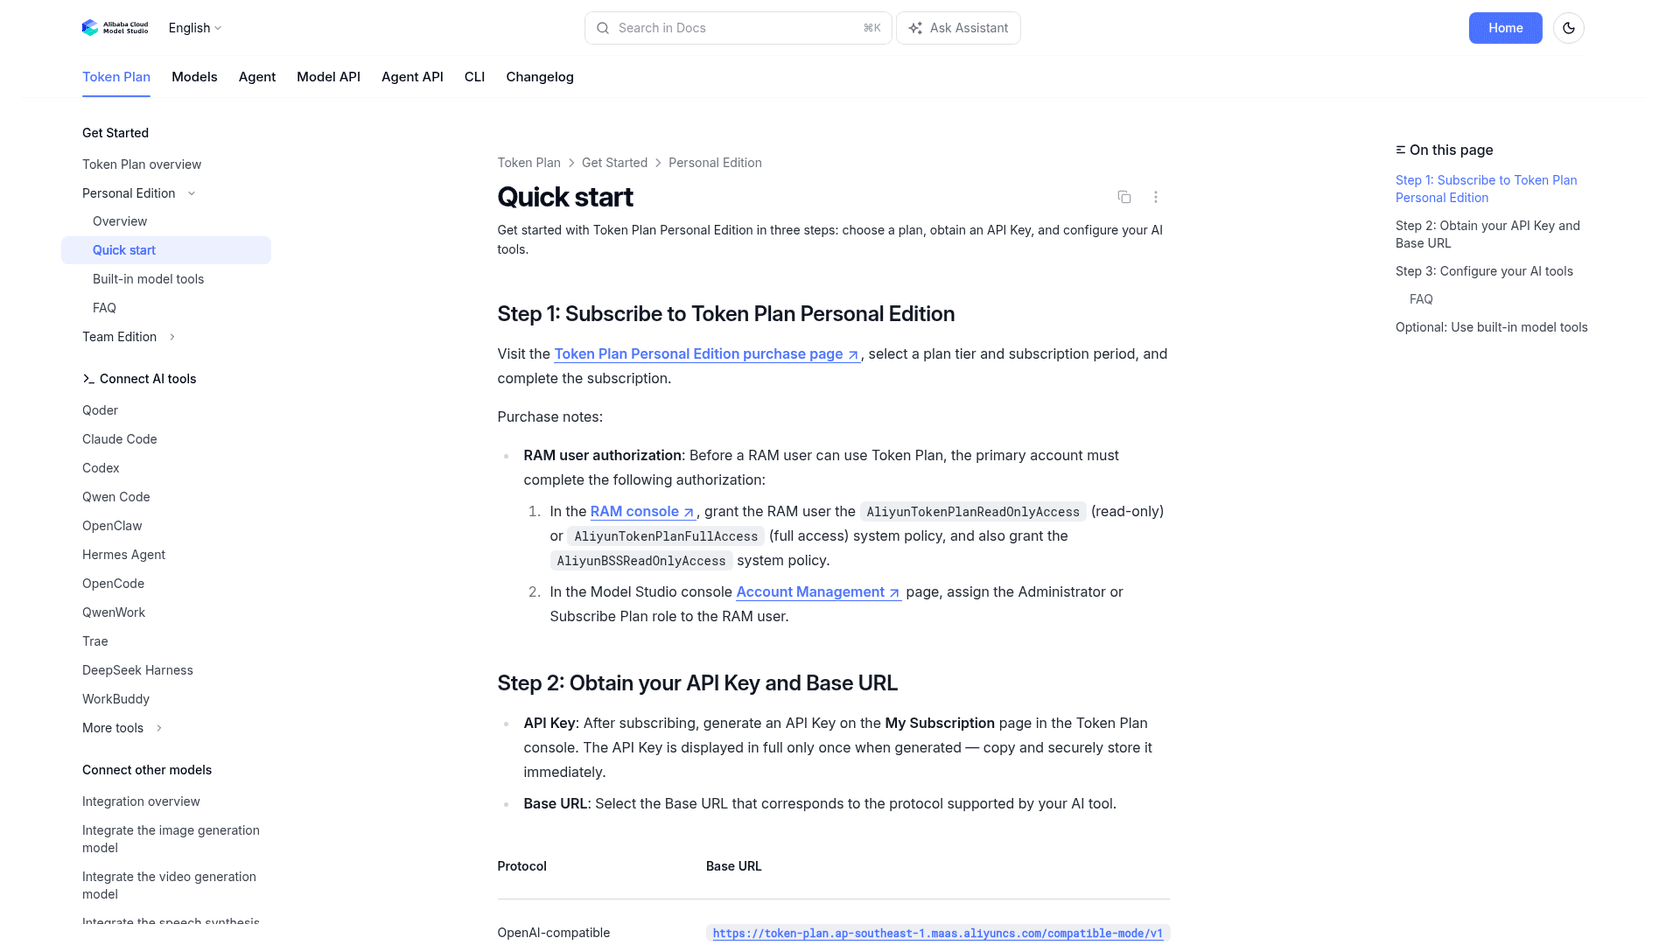
- Subscribe to Token Plan Personal (Singapore region only) and pick a tier.
- Generate an API key on the My Subscription page. It's shown in full only once, so copy it right away. Token Plan keys start with
sk-sp-. - Use the Token Plan base URL for your tool's protocol:
| Protocol | Base URL |
|---|---|
| OpenAI-compatible | https://token-plan.ap-southeast-1.maas.aliyuncs.com/compatible-mode/v1 |
| Anthropic-compatible | https://token-plan.ap-southeast-1.maas.aliyuncs.com/apps/anthropic |
Then set the model ID to qwen4-max-preview.
The key and endpoint have to match
This is the mistake that costs real money. Alibaba runs three separate billing channels, Token Plan, Coding Plan and pay-as-you-go, and each has its own keys and base URLs. The Token Plan FAQ says that using the general dashscope-intl.aliyuncs.com endpoint or a Coding Plan key routes calls through pay-as-you-go instead, and those charges can't be offset by credits or refunded.
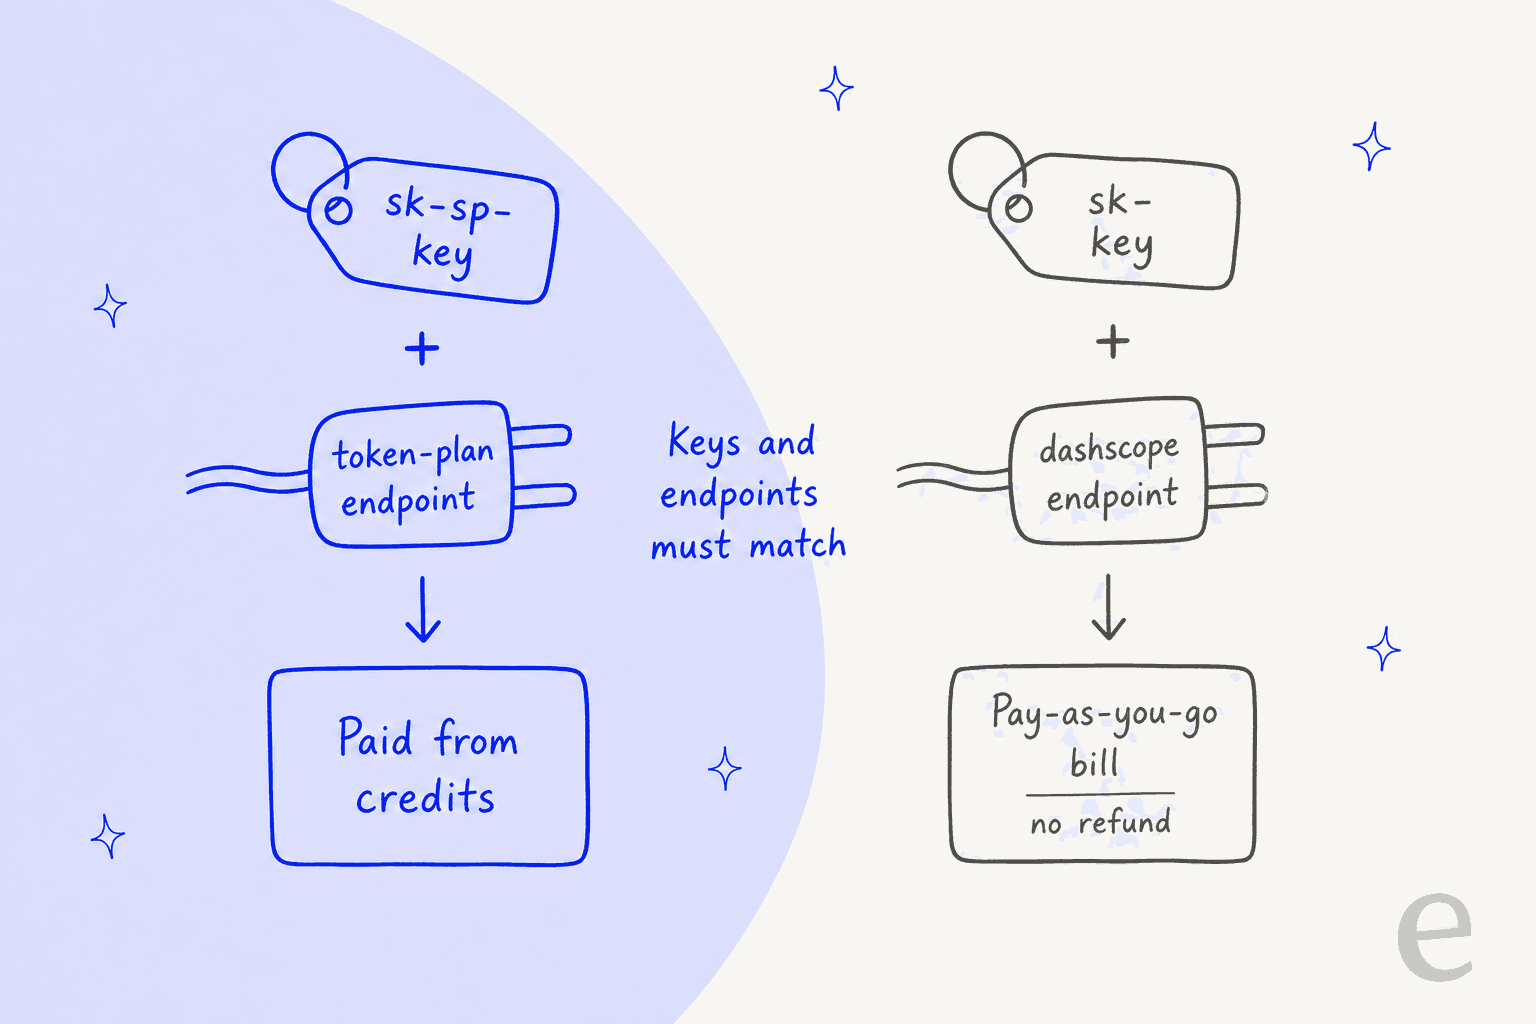
If you've used Qwen through Alibaba before, your tool config probably still has an old sk- key and the DashScope URL in it. Swap the key and the URL, as well as the model name.
How do you run Qwen 4 Max in Claude Code?
You run it by pointing Claude Code at Token Plan's Anthropic endpoint and mapping a model slot to qwen4-max-preview. Alibaba's Claude Code guide gives this config for the CLI:
export ANTHROPIC_AUTH_TOKEN="YOUR_API_KEY"
export ANTHROPIC_BASE_URL="https://token-plan.ap-southeast-1.maas.aliyuncs.com/apps/anthropic"
export ANTHROPIC_MODEL="auto"
export ANTHROPIC_DEFAULT_HAIKU_MODEL="qwen3.6-flash"
export ANTHROPIC_DEFAULT_SONNET_MODEL="qwen3.8-flash"
export ANTHROPIC_DEFAULT_OPUS_MODEL="qwen4-max-preview"
export CLAUDE_CODE_SUBAGENT_MODEL="auto"
export CLAUDE_CODE_MAX_CONTEXT_TOKENS="983616"
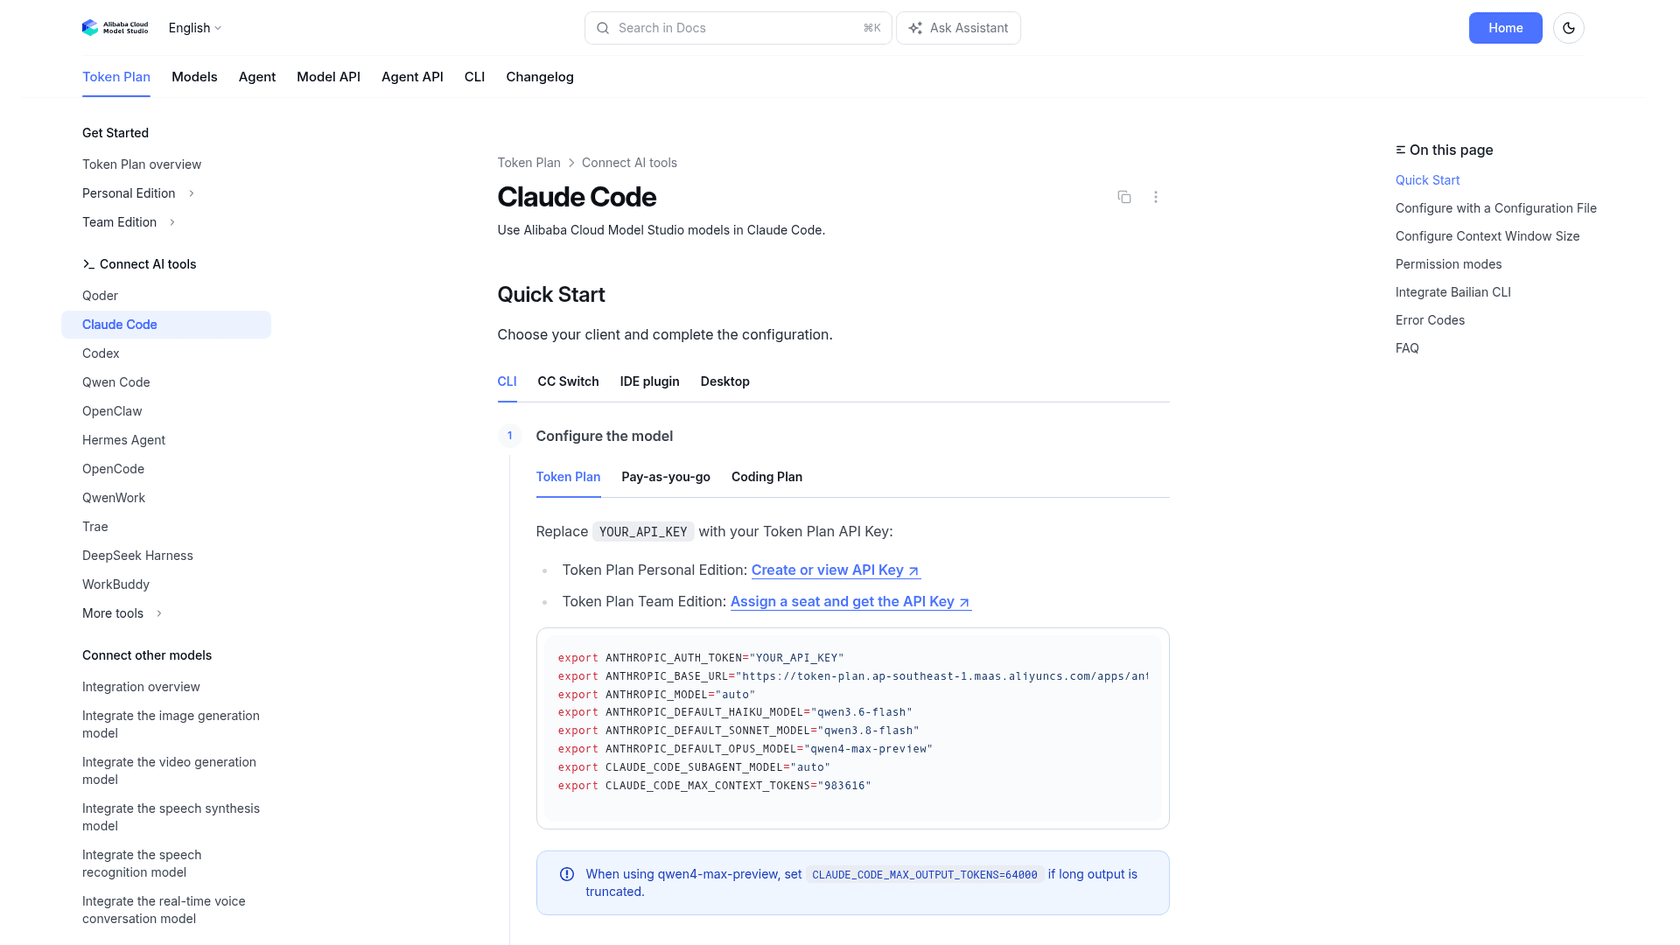
Read that block closely, because it doesn't do what most people expect. The main model is auto, Alibaba's router, and so are subagents. Qwen 4 Max only sits in the Opus slot.
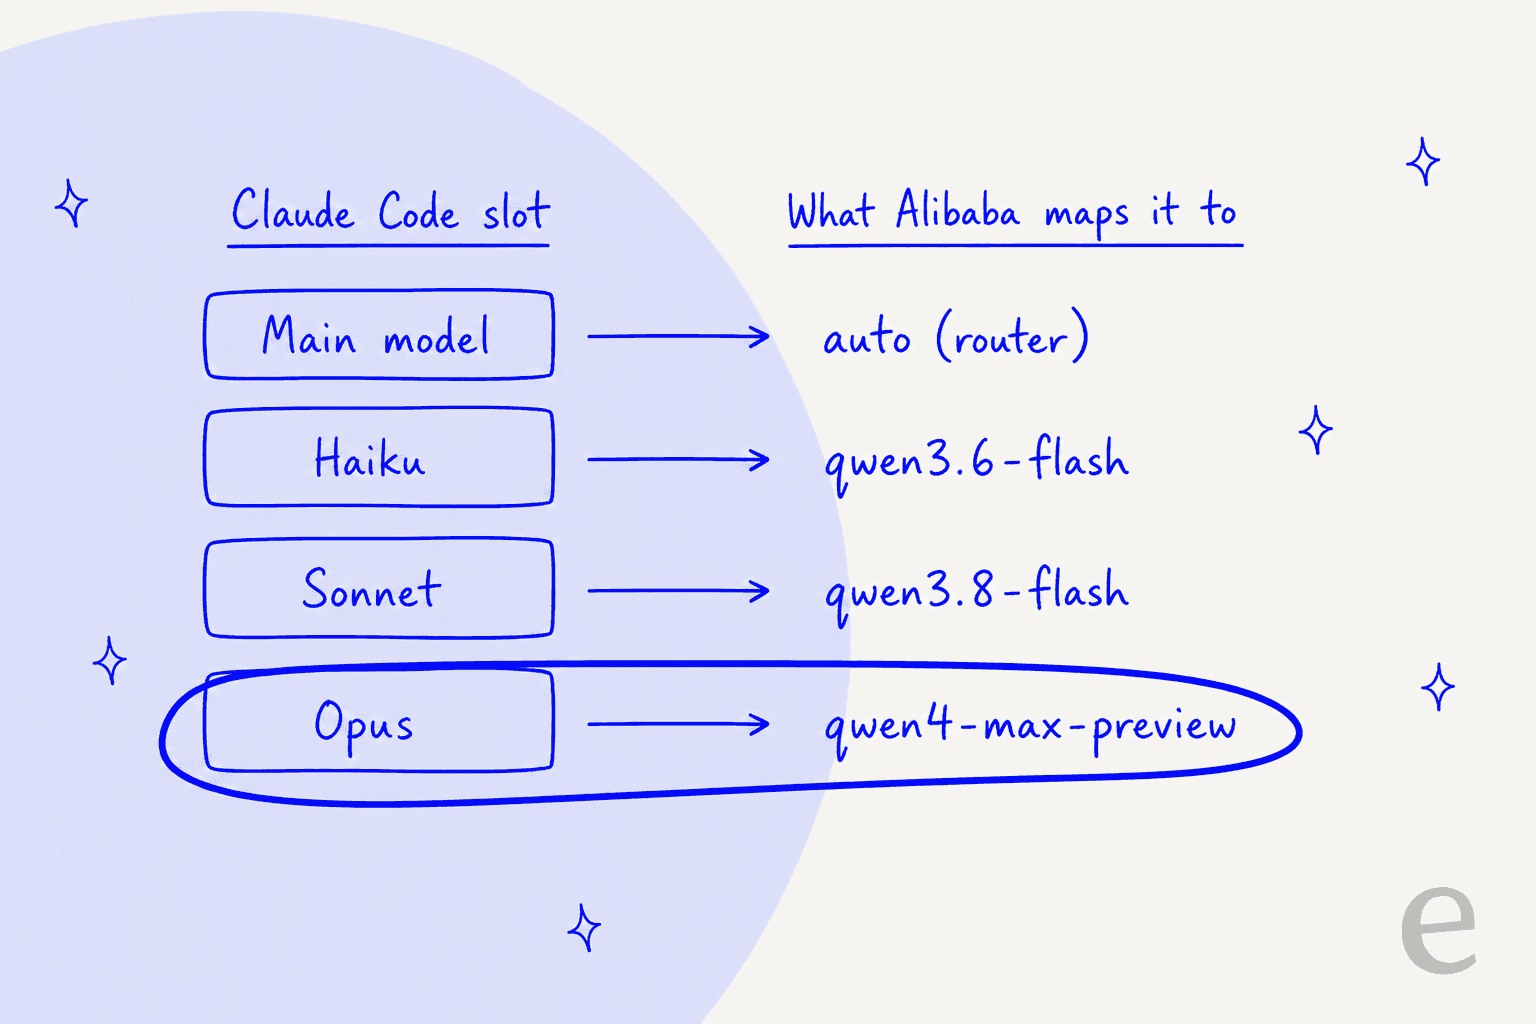
So if you paste this and start a session, your prompts go to whatever auto picks, not to Qwen 4 Max. To actually test the new model, switch with /model opus in the session, or set ANTHROPIC_MODEL="qwen4-max-preview" yourself. If you're comparing models, do the second one, so every turn in your test runs on the same model. My guide to Claude Code model selection explains how the slots work.
Three more settings matter:
- Output length. The docs note that if long output gets cut off with
qwen4-max-preview, setCLAUDE_CODE_MAX_OUTPUT_TOKENS=64000. - Context.
CLAUDE_CODE_MAX_CONTEXT_TOKENS="983616"lets Claude Code use most of the 1M window. See my Claude Code context window guide for what that changes. - Persistence. Those exports only last for the current terminal. For a lasting setup, the same keys go under
envin~/.claude/settings.json, as covered in my Claude Code configuration guide.
Run claude -p "Hello" to check it connects. For Claude Code Desktop, Alibaba's guide routes it through a local gateway called CC Switch rather than environment variables.
Qwen Code, Cursor and other tools
Qwen Code uses the OpenAI-compatible endpoint. Alibaba's sample ~/.qwen/settings.json lists qwen4-max-preview as its own provider entry named "Qwen4.0 Max Preview," so you pick it by name rather than through a slot mapping. Cursor, OpenAI Codex, OpenCode, OpenClaw, Cline, Qoder and Hermes Agent all have Token Plan guides too. In each one, check two things: the base URL is a token-plan one, and the model ID is exactly qwen4-max-preview.
What changes for developers calling it directly?
Two behaviours are new with this model, and both can break a config that worked on older Qwen models.
max_tokens now covers thinking too. Alibaba's compatibility notice says that from qwen4-max-preview on, max_tokens equals max_completion_tokens on Chat Completions, so it caps thinking and the final answer together. Thinking is on at xhigh by default. If you sized max_tokens for the answer alone, reasoning eats the budget and the answer comes back cut short. Older Qwen models keep the old behaviour, which is why this bites people when they swap model IDs.
Thinking has to be passed back. Chat Completions turns on preserve_thinking by default. The model docs ask you to send earlier thinking back in each assistant message's reasoning_content field, not inside content. Also, don't set reasoning_effort and thinking_budget together.
One more: the built-in tools (web search, image search, web scraping, code interpreter) only work through the Responses API, not Chat Completions, per the quick start. If your tool talks Chat Completions, you won't get them.
Qwen 4 Max setup check
Tick what's true for your setup. Anything left unticked is the likely reason it isn't working.
What can't you do with Qwen 4 Max?
You can't build a product on it, for two reasons that have nothing to do with how smart it is.
First, it's temporary. The docs say no changes are made during the preview and the model is retired when it ends. Anything that calls qwen4-max-preview stops working after November 25.
Second, Token Plan forbids it. The subscription terms say the plan is for interactive use inside coding and agent tools only, and must not be used for "automation scripts, custom application backends, or any non-interactive batch call scenarios." The FAQ adds that scheduled background tasks count too, and that sharing a key can get it suspended. So a support chatbot, a ticket classifier or an AI customer service API wired to this key breaks the rules from the first call.
Early users are already reading it as a test drive. One Hacker News commenter put the deal in one line:
"By November 25th, Beijing time daytime (8am-22pm) -80%, and at night (Western daytime) even -92%!"

And on quality, there's no consensus yet. A widely shared X post called it "disappointing" based on what the author admitted were rumors, and a reply from someone actually testing it disagreed:
"It's preview; Qwen4-max-preview. It's not disappointing at all, at least so far in my one-shots, but more testing is going on and i'll have a clear answer."
My advice: run it on a task you've already solved with your usual model, like Claude Fable 5.2 or GPT-6.1 Terra, and judge it on that. A frozen two-week model is a fair thing to test and a poor thing to build on.
What does Qwen 4 Max mean for support teams?
For a support team, Qwen 4 Max is a model to try at your desk, not one to put on your queue. The terms and the retirement date settle that.
The bigger lesson repeats every launch week. A model is the engine, not the agent. What makes AI useful on tickets is the layer around it: your help center, your past tickets, the rules for when to hand off to a person, and testing against real conversations before anything reaches a customer. That's the job eesel's AI helpdesk teammate is built for. It joins the queue you already run in Zendesk or Freshdesk, learns from your history, and gets simulated against past tickets first.
OroSoft is a good example of the grounding part. It makes bullion trading software and supports clients through Freshdesk. When an agent mentions eesel on a ticket, it drafts a reply from 6,100 past tickets and 20 help center and reference files, says which ticket or article it used, and leaves a note asking for a person when it can't find support for an answer. smava, a German loan comparison site, runs eesel across two Zendesk brands and handled 27,000 tickets in one month.
Neither setup changes when a new model launches, and that's the point. If you're curious how a model handles your own support content, my guides on connecting Claude to your helpdesk, AI agent handoffs and stopping hallucinations are a better start than a preview key.
Should you set up Qwen 4 Max this week?
Yes, if you live in a coding agent and want a cheap two weeks with a 1M-context Qwen. The $3 Lite plan, the 20% credit rate and the 8% night rate make it close to free to try, as long as you set the model slot correctly and match your key to the Token Plan endpoint.
No, if you need a model for an app, a bot or a budget. Use Qwen 3.8 Max on pay-as-you-go for that, and check back when Alibaba ships the full Qwen 4 Max with a price and scores. For a wider look at the family, my Qwen overview and Qwen alternatives cover the rest.
Try eesel for AI on your support queue
If what you actually want is AI that answers customers, eesel is an AI helpdesk teammate that plugs into the helpdesk you already use, learns from your past tickets and help center, and gets tested on historical conversations before it touches a live one. OroSoft uses it to draft grounded Freshdesk replies that cite the ticket they came from. You can see the pricing or try eesel free.
Frequently Asked Questions
What is Qwen 4 Max?
qwen4-max-preview, a multimodal reasoning model with a 1M-token context and 393,216 max output. It went live on November 11, 2026 and is retired after November 25. The Qwen 4 Max review covers what the preview can and can't tell you.How do I use Qwen 4 Max?
sk-sp-, point your tool at the Token Plan base URL and set the model ID to qwen4-max-preview. Supported tools include Claude Code, Cursor, Qwen Code and OpenClaw.Is Qwen 4 Max free?
Is the Qwen 4 Max API available?
How long is Qwen 4 Max available?
qwen4-max-preview ID stops working then. My LLM tracking tools roundup helps you watch for the full release.How do I set up Qwen 4 Max in Claude Code?
ANTHROPIC_BASE_URL to the Token Plan Anthropic endpoint, put your sk-sp- key in ANTHROPIC_AUTH_TOKEN, and map ANTHROPIC_DEFAULT_OPUS_MODEL to qwen4-max-preview. Alibaba's own config sets the main model to auto, so pick Opus with /model to make sure you are on Qwen 4 Max. My Claude Code environment variables guide explains each variable.What is the difference between Qwen 4 Max and Qwen 3.8 Max?
max_tokens now covers thinking and answer together. Qwen 3.8 Max is released, has independent scores and costs $2 input and $6 output per 1M tokens on pay-as-you-go. See my Qwen 3.8 Max pricing breakdown.