

Freshdesk has no auto-QA scorecard that grades every ticket against rules you write. What exists is the Post Resolution Quality Coach, which labels a resolved conversation Good, Neutral or Bad on six fixed parameters, and Freshworks' feature table lists it for Freshdesk Omni and Freshchat, not standalone Freshdesk. It needs the $29-per-agent Freddy AI Copilot add-on on Pro or Enterprise, and its help article is still marked Beta and was last edited in December 2024. If you need policy checks, such as whether the agent confirmed eligibility before promising a refund, add a marketplace QA app or have eesel review closed tickets against your own rubric. With the eesel CLI, an AI coding agent can upload approved knowledge, such as exported Freshdesk solution articles, write the rubric into eesel and test it on sample tickets before anything goes live, though connecting Freshdesk still needs an admin's approval.
Does Freshdesk have AI quality assurance?
Freshdesk has AI quality coaching, which is narrower than quality assurance. I work on the integration side of eesel, so I read Freshworks' pages the way I would read our own feature: what it scores, which plan it needs, and what the docs leave out.
Here is what I found on Freshworks' own pages:
- Post Resolution Quality Coach. After a conversation is resolved, Freshworks' help article says agents see a quality score in the inbox, and admins get a Quality Score report.
- Proactive Quality Coach. It reviews a reply after the agent clicks send and suggests fixes, per its help article.
- Sentiment analysis. Freddy AI Copilot tags conversations positive, neutral or negative in real time.
- Reports. The curated reports article lists a Satisfaction Survey report and an AI Agent Performance Report.
What I did not find is an auto-QA feature that scores every conversation against a scorecard you write, which is what Kustomer, Front and HubSpot now offer in their own ways. That is a fair gap to name, not a flaw in what Freshdesk does well.
Which Freshdesk product gets the quality coaches?
The answer depends on which product you run, and Freshworks' own table is the clearest source. In Freshworks' Freddy pricing article (last edited July 2025), Proactive and Post Resolution Quality Coach are marked "Yes" for Freshchat and Freshdesk Omni, and "NA" for Freshdesk. Sentiment analysis is marked "Yes" for all four products in the table.
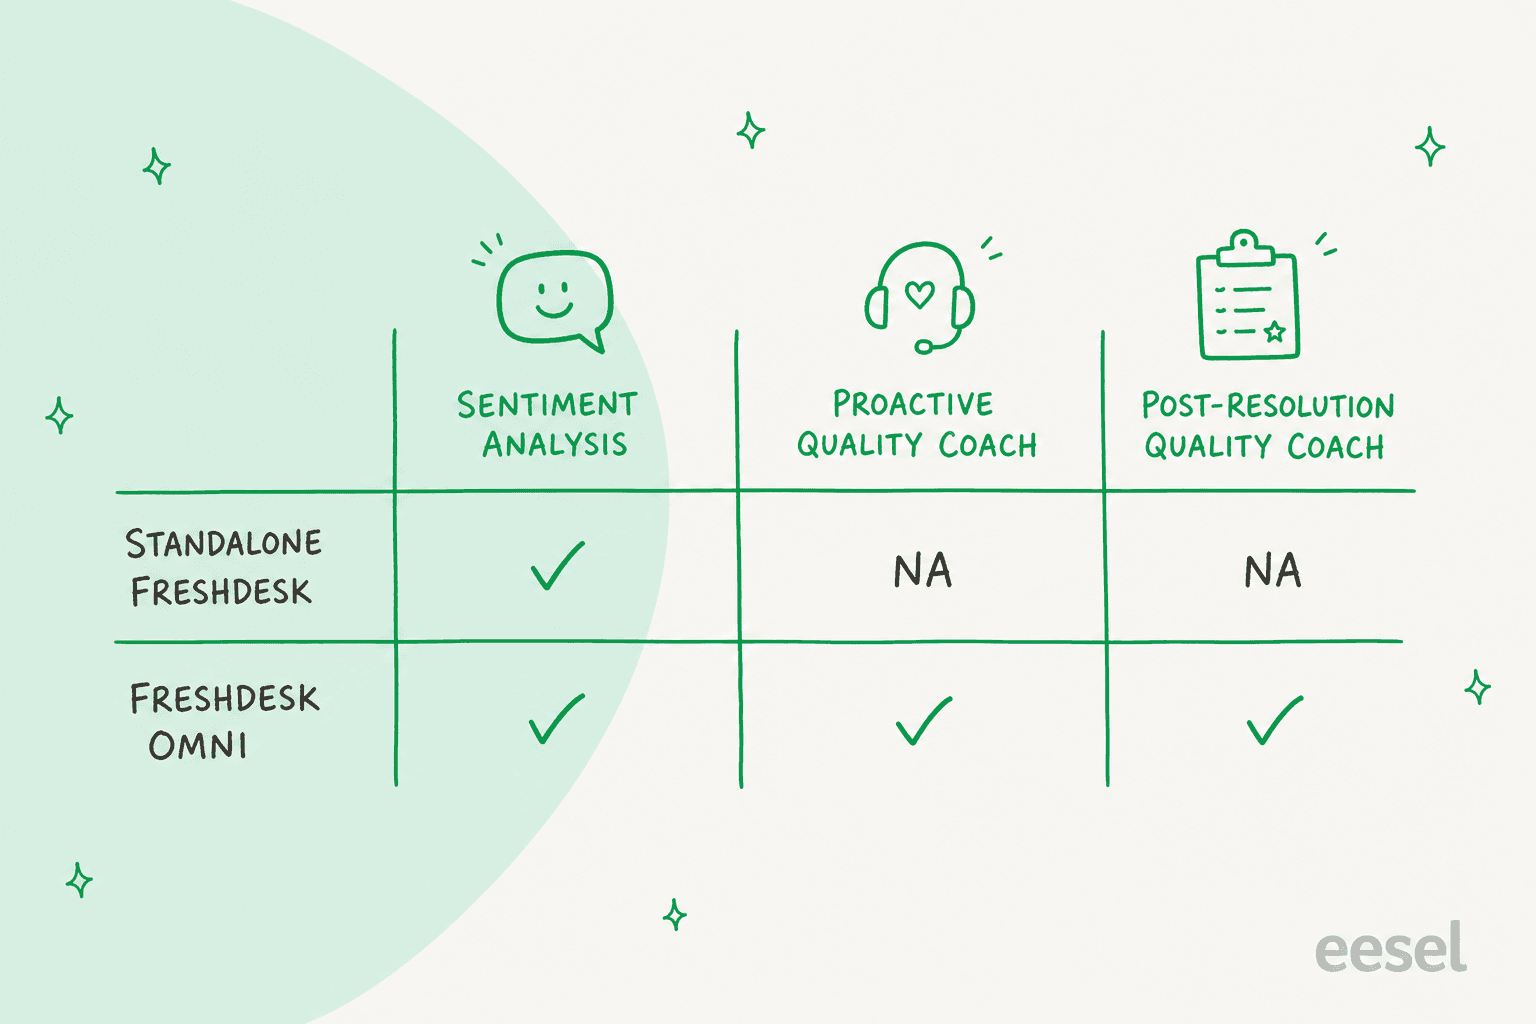
That article is dated, so confirm the current state in your own admin settings. Two details make me cautious. The coaches' help articles are written around Freshchat admin screens (Admin Settings, then Chat Settings, then the Freddy icon), and I found no Freshdesk-specific enablement page. If you run standalone Freshdesk, plan on the coaches not being available until Freshworks says otherwise. The Freshdesk vs Freshdesk Omni comparison covers the other differences.
What does the Post Resolution Quality Coach score?
It scores six fixed parameters, per Freshworks' help article:
- Opening and closing: professionalism at the start and end of the chat.
- Timeliness of response: how quickly the agent replies.
- Quality of response: detail, relevance and helpfulness.
- Customer sentiment: whether the tone stays positive or neutral by the end.
- Grammar: correct language and clear communication.
- Non-abusive or filler words: respectful, professional wording.
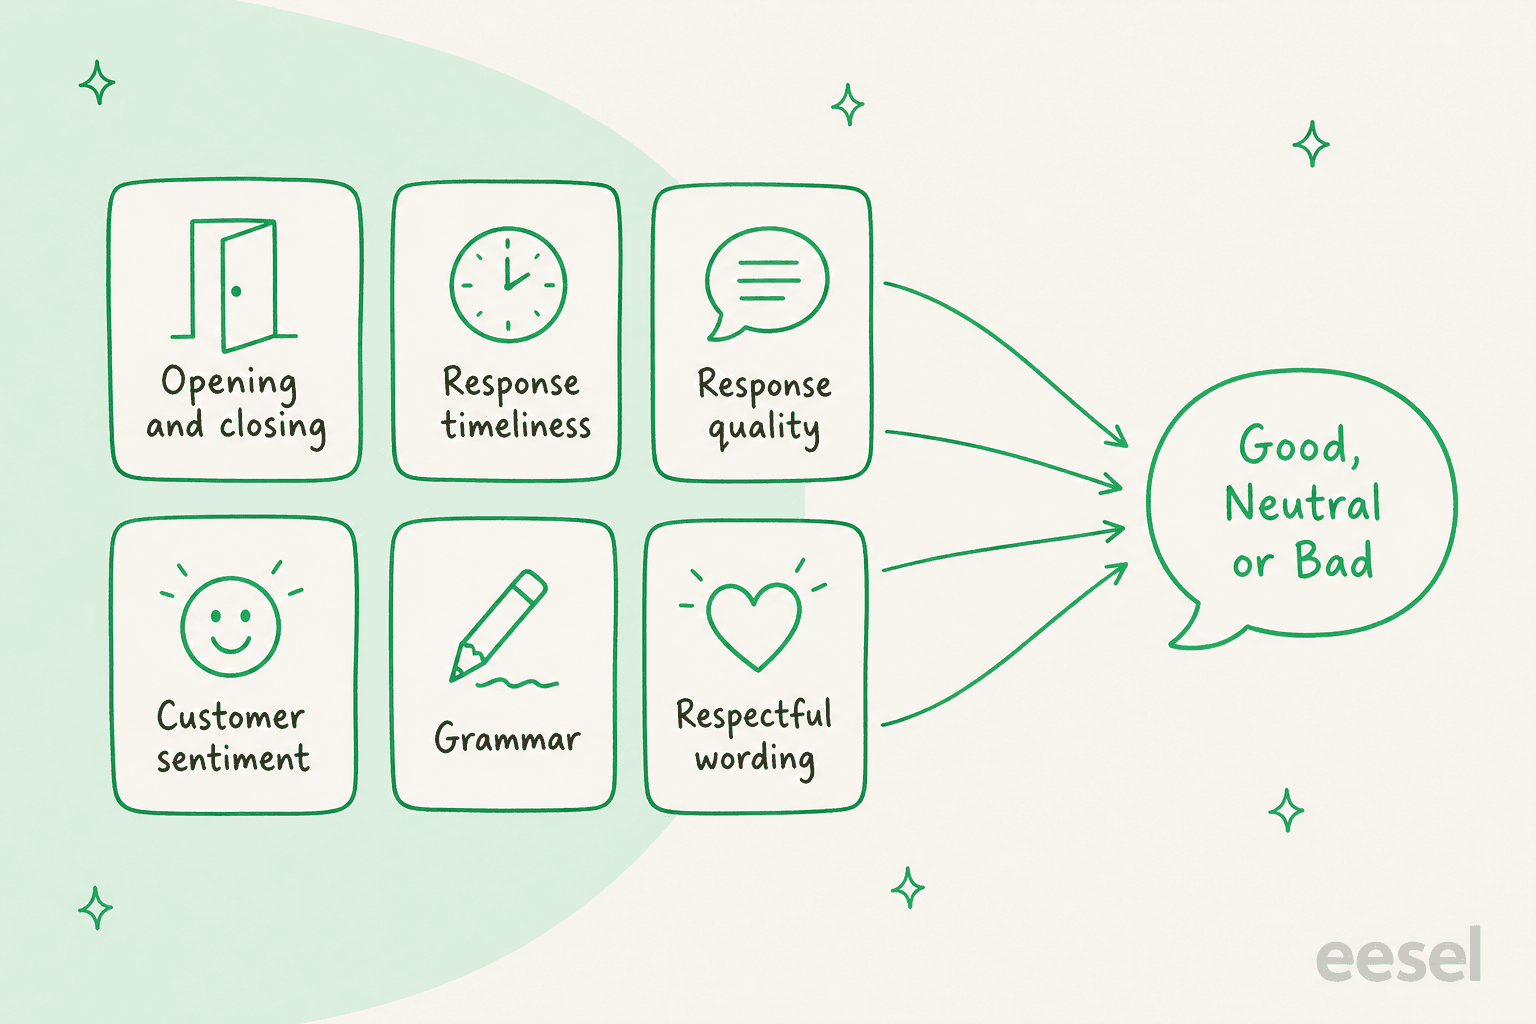
Agents open the third pane of the inbox to see strengths, areas to improve and recommendations, and each conversation is labelled Good, Bad or Neutral. Admins get a Quality Score report, viewable weekly or monthly at group or agent level, with a trend line. The article says generating scores can take a couple of minutes.
This is good for tone and hygiene, and I would use it as a coaching aid. It is not a policy check. Nothing in the article describes a way to add a criterion such as "confirmed the order was eligible before promising a change", and it doesn't say how "quality of response" is judged against your knowledge base. It also doesn't list supported languages or usage limits.
What does the Proactive Quality Coach do?
It works earlier, before the customer sees a problem. After an agent clicks send, Freshworks' help article says Freddy checks the reply on seven parameters, in priority order: abusive words, spelling, grammar, too long, filler words, tone and relevancy. It detects up to ten tones, five positive (such as Empathetic and Solution Oriented) and five negative (such as Defensive and Overly Robotic or Scripted), and it works on all channels, including email.
Admins can see suggestions shown, accepted and rejected, plus average quality score and average CSAT for agents with and without the coach. It is off by default and is enabled per role or for everyone. Like the post-resolution coach, the article is dated December 2024 and describes Pro and Enterprise Beta access with the Copilot add-on.
Which plans and add-ons does it need?
The coaches sit inside the Freddy AI Copilot add-on. Freshworks' pricing pages (checked 22 November 2026) list that add-on at $29 per agent per month on Pro and Enterprise, and not on Growth:
| Product | Growth | Pro | Enterprise | Copilot add-on | Freddy AI Insights |
|---|---|---|---|---|---|
| Freshdesk | $19 | $55 | $89 | $29 on Pro and Enterprise | Enterprise |
| Freshdesk Omni | $29 | $79 | $119 | $29 on Pro and Enterprise | Enterprise |
All prices are per agent per month, billed annually. Freshworks says annual billing saves 20%, and I did not capture monthly rates.
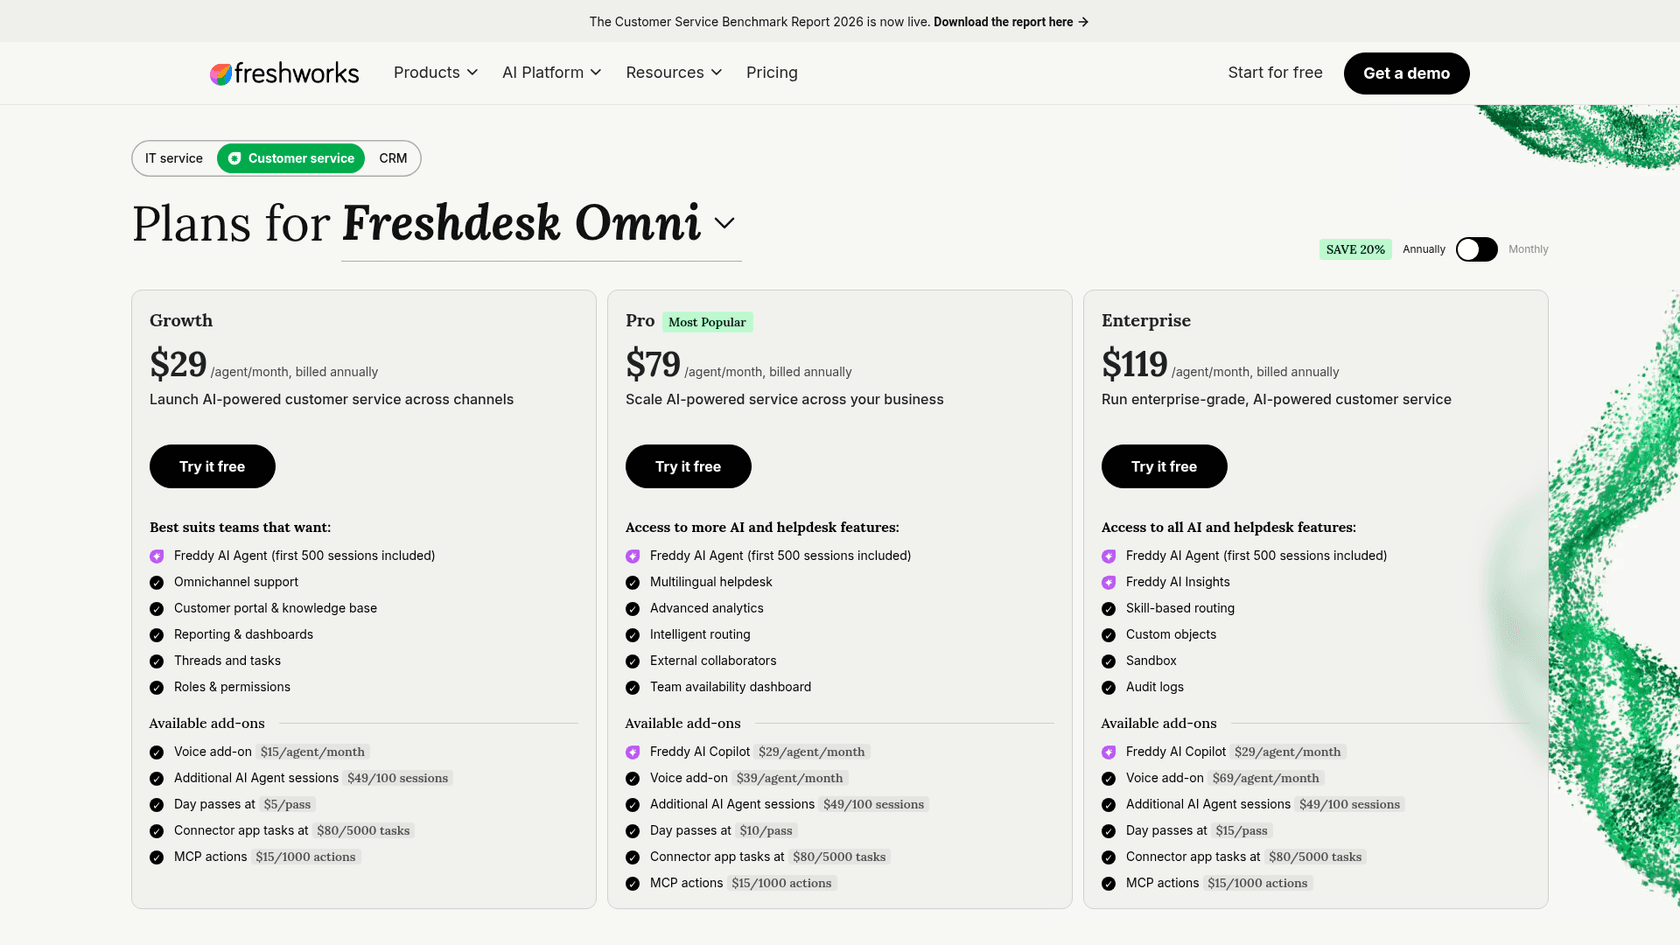
For a team of 10 agents on Omni, the Copilot add-on alone is $290 a month. On Omni Pro that is about $1,080 a month (10 x $79 + 10 x $29), and on Omni Enterprise about $1,480. Freshworks says you can buy the add-on for a subset of agents, so a team of 10 could cover only the 4 agents who most need coaching. Freshdesk pricing and Freddy Copilot pricing go deeper on the rest of the bill.
What else in Freshdesk helps with quality?
Four things sit around the coaches, and they answer different questions:
- Satisfaction Survey Results. Per the curated reports article, it has tabs for Overview, CSAT vs Activity, CSAT vs Quality, Agent and Group. The CSAT vs Quality tab compares CSAT with support quality metrics. The article doesn't say which plans include it.
- Agent Performance Report. It covers productivity, efficiency and SLA adherence by tabs such as Time, SLA% and AHT. That is speed and compliance, not conversation quality. Freshdesk custom reports cover building your own.
- Freddy AI Insights. Freshworks' FAQ says it is exclusive to Enterprise plans and surfaces metric changes at the group level, with root cause analysis for negative insights. It needs a group with at least 10 tickets in 12 weeks, is English only, and doesn't support exports.
- Conversational Insights. Generally available since 1 June 2026, per its help article, it answers plain-English questions about ticket volume, SLA compliance and agent resolution time. The page gives a guideline of 100 queries per account per month that it says is not currently enforced, and it doesn't describe scoring agents.
My Freshdesk AI analytics guide walks through the reporting side, and Freshdesk AI sentiment analysis covers the sentiment tag.
How do you check Freshdesk's own AI agent?
Freshdesk gives you a test, not a score. The AI Agent evaluation article (last edited April 2026) says the Test tab in AI Agent Studio runs simulated customer queries, up to 100 per run, and can generate 50 sample queries from your knowledge sources. Each answer shows its status, source and a thumbs up or down rating. It is listed for Freshdesk Omni's Growth, Pro and Enterprise plans.
After launch, the AI Agent Performance Report (which requires the Freddy AI add-on) shows engagement, resolutions and transfers to humans, and an AI Agent vs Human Agent Comparison Report covers resolution times and SLA compliance for both. Neither says whether an answer was correct. My Freshdesk AI agent best practices and session consumption posts cover reviewing answers and the meter.
What does Freshdesk's scoring leave out?
Here is what I couldn't find on Freshworks' pages:
- Custom criteria. The six parameters are fixed in the article, with no weights or edits described.
- Standalone Freshdesk coverage. The July 2025 table marks both coaches "NA" for Freshdesk.
- Current status. Both coach articles still say Beta and were last edited in December 2024, even though the Copilot article says Copilot reached general availability.
- Languages and limits. Neither coach article lists them.
- Reading your policies. Nothing describes scoring a reply against your refund or eligibility rules.
- Scoring the AI agent. The reports count resolutions and handoffs, and the Test tab relies on a manual rating.
- Accuracy. I found no published accuracy figure for either coach.
None of that is a reason to skip the coaches. It is a list of questions for your Freshworks rep.
Which marketplace QA apps work with Freshdesk?
The Freshworks Marketplace lists dedicated QA tools. MaestroQA and EvaluAgent are both shown as supported for Freshdesk and Freshdesk Omni, and neither listing shows a price. The MaestroQA listing adds that data handling, including for AI features, follows the third-party licensor's terms and is not governed by Freshworks Freddy AI. That means a second vendor holds your tickets, and your security review will ask about it.
Pick one when you want human reviewers, calibration sessions and coaching workflows. My support QA tools roundup and the best AI QA assistant list compare options, and support QA calibration covers how reviewers agree on scores.
How would I run QA on Freshdesk?
I would combine the native coaching with a rubric that checks your policies. This is what I would do in the first month:
- Turn on the coaches for a few agents first if you are on Omni, and check the Quality Score report against tickets you know.
- Write three to five criteria tied to something visible in a ticket, such as "checked the plan before promising a refund". QA feedback examples help with wording.
- Review the 20 lowest and 20 random scores each week, and correct the criteria behind any disagreement.
- Keep the CSAT survey running. Quality scores judge your handling, and customers judge the outcome. The CSAT vs Quality tab shows when they diverge.
- Track outcomes next to scores, such as first contact resolution and escalation, before coaching anyone on a number.
AI support quality assurance covers judging an AI agent before and after launch, and support QA with AI covers the human side. For fair scorecards once AI takes the easy tickets, see AI for support agent performance.
Where does eesel fit next to Freshdesk?
eesel is an AI helpdesk teammate that works in the queue you already use, and the Freshdesk integration lets it draft private notes or take ticket actions you enable. For QA, the useful job is a scheduled review: eesel reads each closed ticket, scores it on a rubric you write in plain words, and leaves its reasons in a private note for a lead.
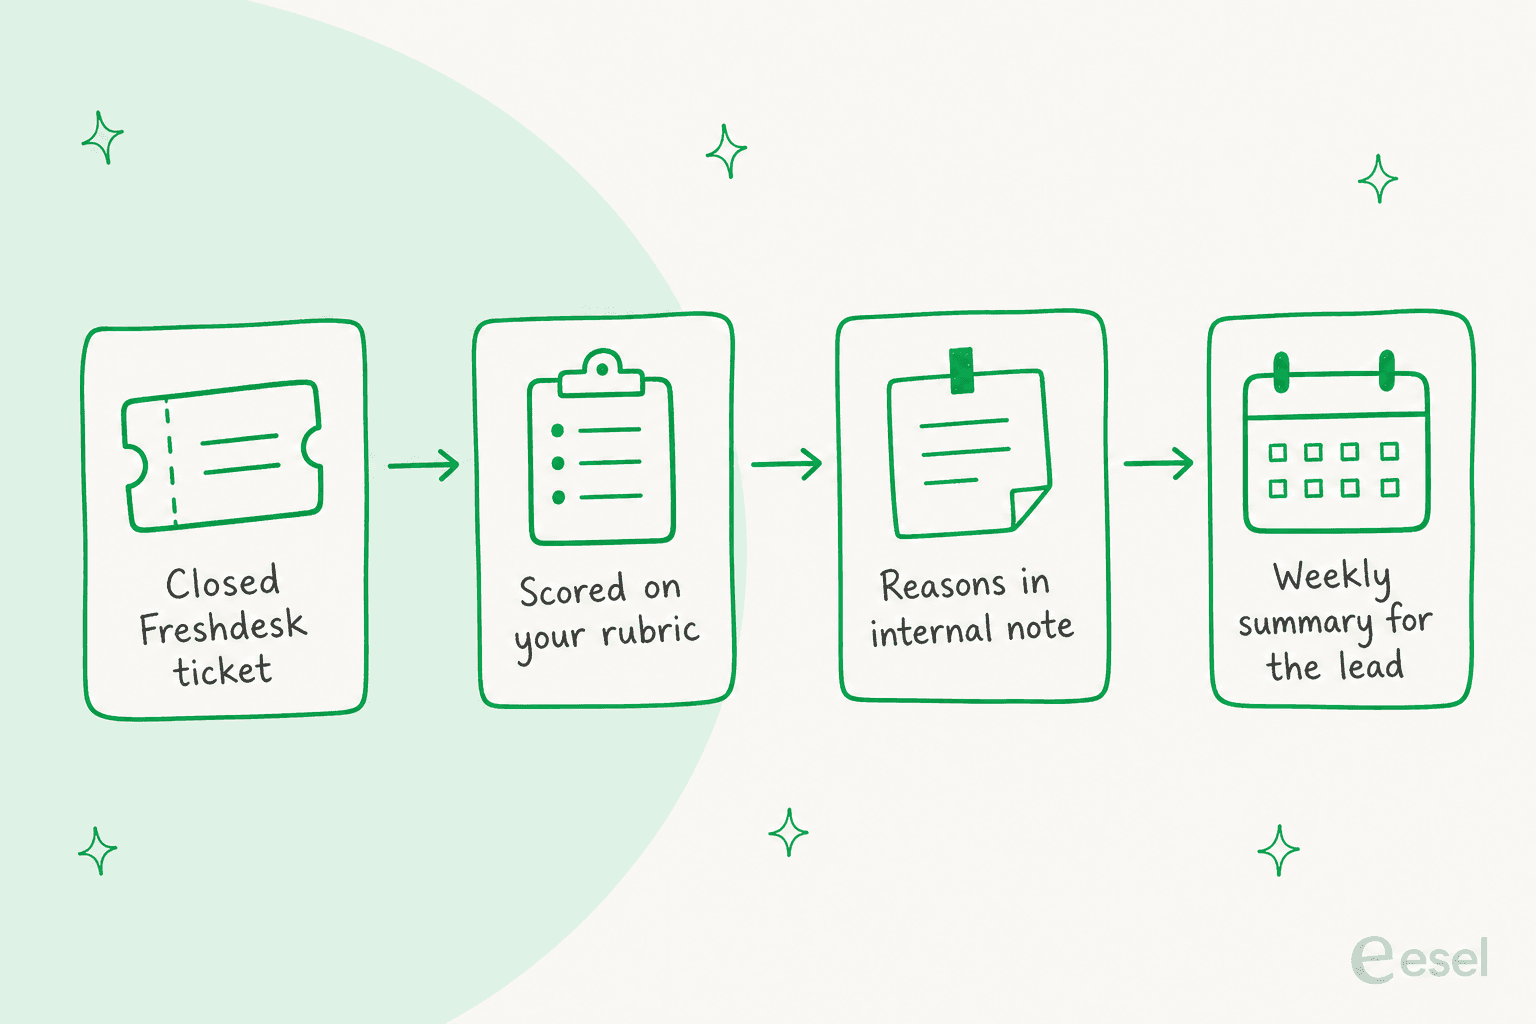
You choose what it may do alone: every action can run, ask first or stay off, so a review run can leave notes and tags while replies stay off. A workflow like this fits any rubric you can write down, such as policy accuracy or the right tags. That fills the gap in Freshdesk's native scoring, and it doesn't replace the coaches' tone checks.
SamCart shows the other side of QA, which is getting replies right before a lead reviews them. It runs one eesel agent on Freshdesk tickets and another on its website chat, both answering from about 280 help center articles. The ticket agent replies only while no person is assigned, and it stops once a teammate picks the ticket up or a seller asks for a person. A narrow job with a clear handoff leaves less for any QA to catch afterward.
Is Freshdesk's AI QA enough?
For a team on Freshdesk Omni with Copilot, the coaches are worth switching on for tone, grammar and timeliness, and the Quality Score report gives leads a starting point. They are not enough if your quality bar is "did the agent follow our policy", because the six parameters are fixed and the help articles are old.
My take: confirm with Freshworks that the coaches are live for your product, buy Copilot only for the agents who need coaching, and add either a marketplace QA app or an eesel review job for policy checks. If you are comparing helpdesks partly on QA, see my Freshdesk review and the Freshdesk AI guide. For how rivals handle QA, I covered Gorgias, Zendesk and Help Scout.
Try eesel for QA next to Freshdesk
If your Freshdesk plan has no QA scoring, or its six parameters aren't the ones you grade on, an AI helpdesk teammate like eesel can review closed tickets against your rubric every morning, tag the misses and post a summary for the lead. Set the review up in actions and approvals so it leaves notes and nothing reaches a customer. Try eesel on yesterday's closed Freshdesk tickets and compare its notes with your own reviews.
