

Freshchat does ship AI quality assurance: Freddy's Post Resolution Quality Coach scores each resolved conversation on six fixed parameters, labels it Good, Neutral or Bad, and feeds a Quality Score Report, as an add-on to Freddy AI Copilot ($29 per agent a month) on Pro and Enterprise. What it scores is how the agent wrote and how the customer felt, not whether the answer matched your policy, the chat went to the right group, or any rule you'd add yourself. Freshworks documents no custom criteria. For those checks, read a weekly sample by hand or have an AI teammate like eesel read the chats you point it at against your written rules and leave its reasons in a private note. With the eesel CLI, an AI coding agent such as Claude Code can connect Freshdesk, check automations and draft live-chat instructions; a Freshchat admin still enters the API token and webhook.
Does Freshchat have AI quality assurance?
Yes (my Freddy AI review covers the wider toolkit). Freshworks documents two Freddy features with "Quality Coach" in the name, plus the CSAT reporting every team already has. Here is what each one tells a QA lead.
| Freshchat feature | Plan | What it tells a QA lead | What it doesn't |
|---|---|---|---|
| Post Resolution Quality Coach | Pro and Enterprise, as a Freddy AI Copilot add-on | A score and Good, Neutral or Bad label for each resolved conversation, per agent and group | Whether the answer followed your policy |
| Proactive Quality Coach | Pro and Enterprise, in beta, part of Copilot | Suggested fixes to a reply before it sends | Anything after the reply is sent |
| Chat Conversations Overview, CSAT and Overall tabs | Reporting | Ratings, satisfactory and unsatisfactory counts, trends, reopened chats (AI CSAT explains how to read them) | Which reply went wrong, or why |
What does Post Resolution Quality Coach score?
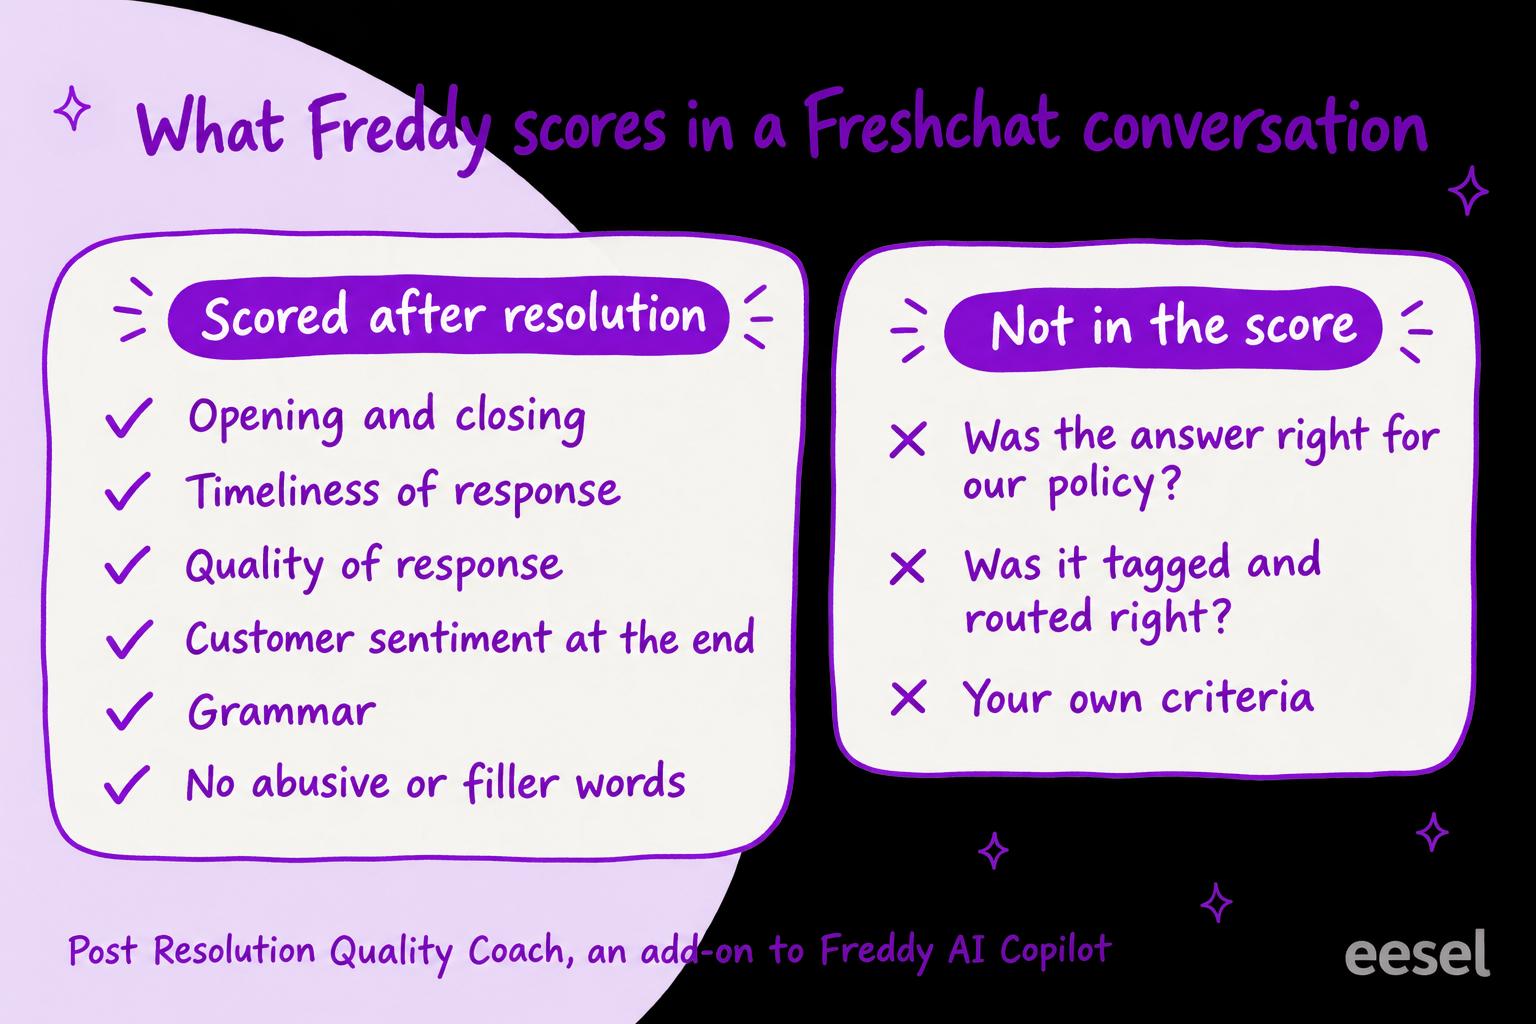
Freshworks' Quality Coach article says the score "is calculated based on six different parameters":
- Starting and ending of conversation: "The effectiveness and professionalism demonstrated in initiating and concluding the conversation."
- Timeliness of response: how quickly the agent replied.
- Quality of response: "The level of detail, relevance, and helpfulness of the agent's response to the customer's query or concern."
- Customer sentiment: whether the tone stays positive or neutral at the end.
- Grammar of response: grammar, language use and clarity.
- Non abusive/filler words: whether the agent's language stays respectful and professional.
After the conversation is resolved, the agent opens the third pane of the agent inbox and sees insights on how it went, tips to improve, and a Good, Bad or Neutral label. They can rate the score with a thumbs up or down, which Freshworks says lets admins "assess the effectiveness of the feature for agents". The article describes no reviewer step: an agent can give a score a thumbs down, but nobody overrides it.
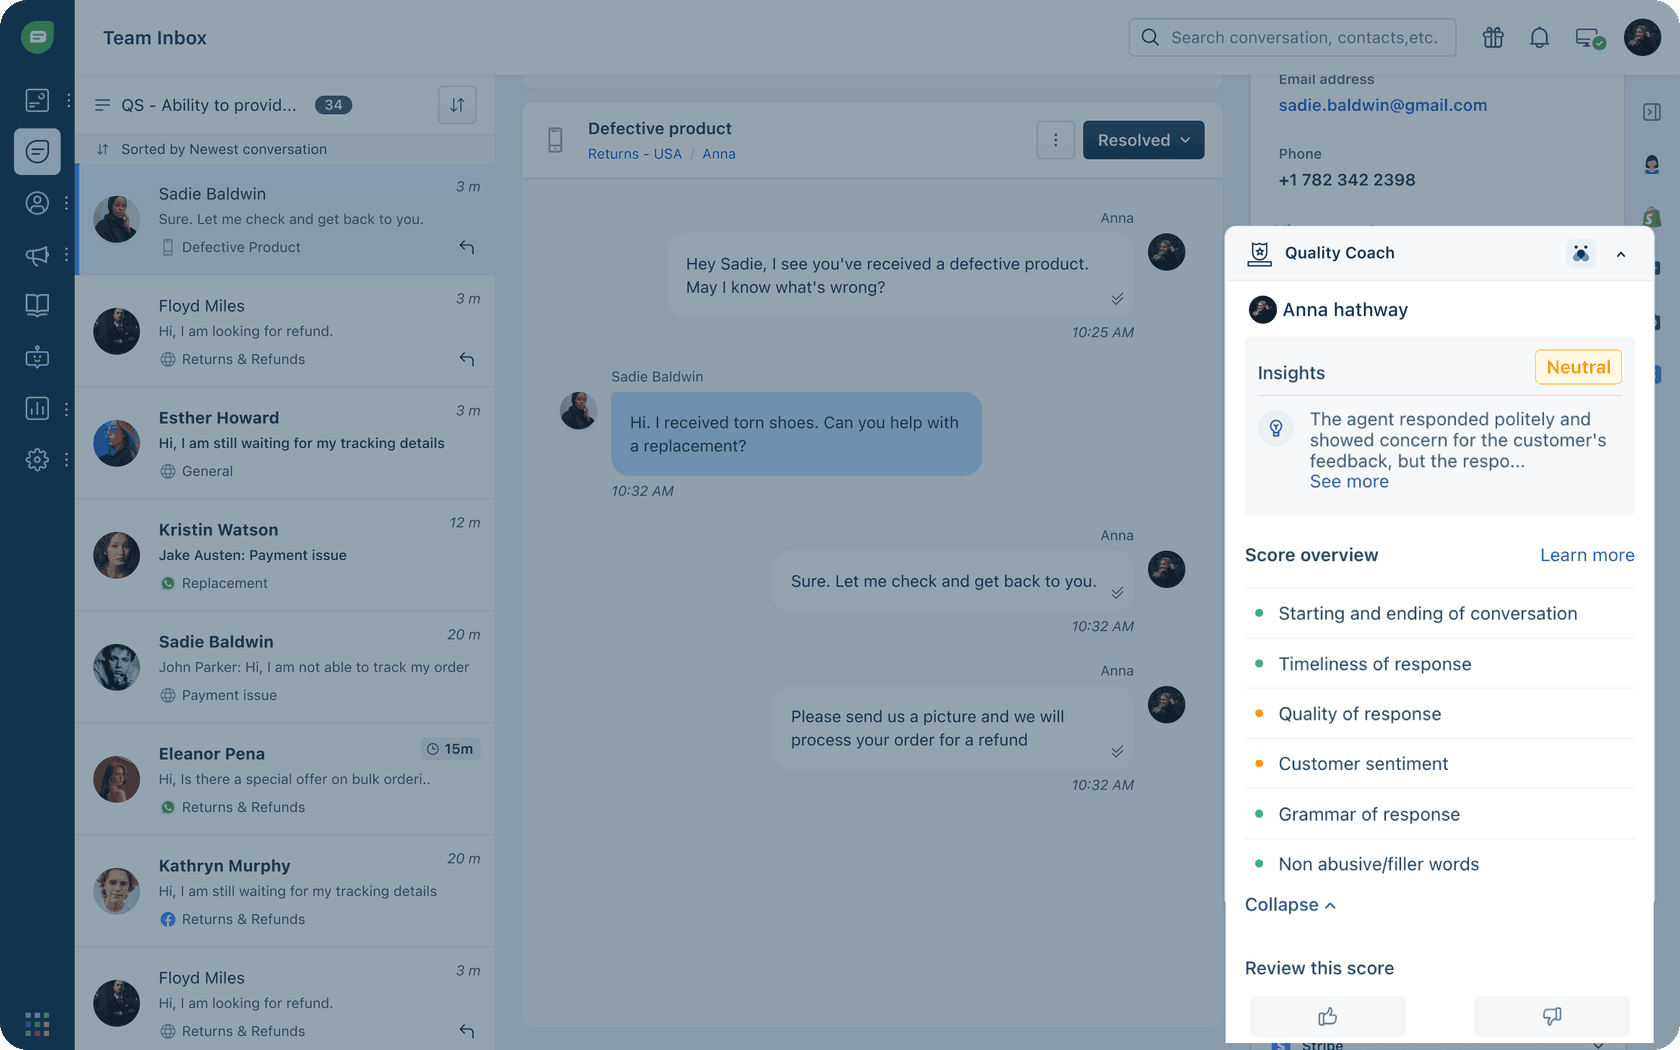
Freshworks' own screenshot is worth reading closely. The customer asks for a replacement for torn shoes, the agent replies "Please send us a picture and we will process your order for a refund", and the coach marks the conversation Neutral with Quality of response and Customer sentiment in amber. Freddy marked Quality of response amber here. What it can't know is whether your returns policy says torn shoes get a replacement, a refund, or a photo first. That judgment needs your rules, and the six parameters don't take any.
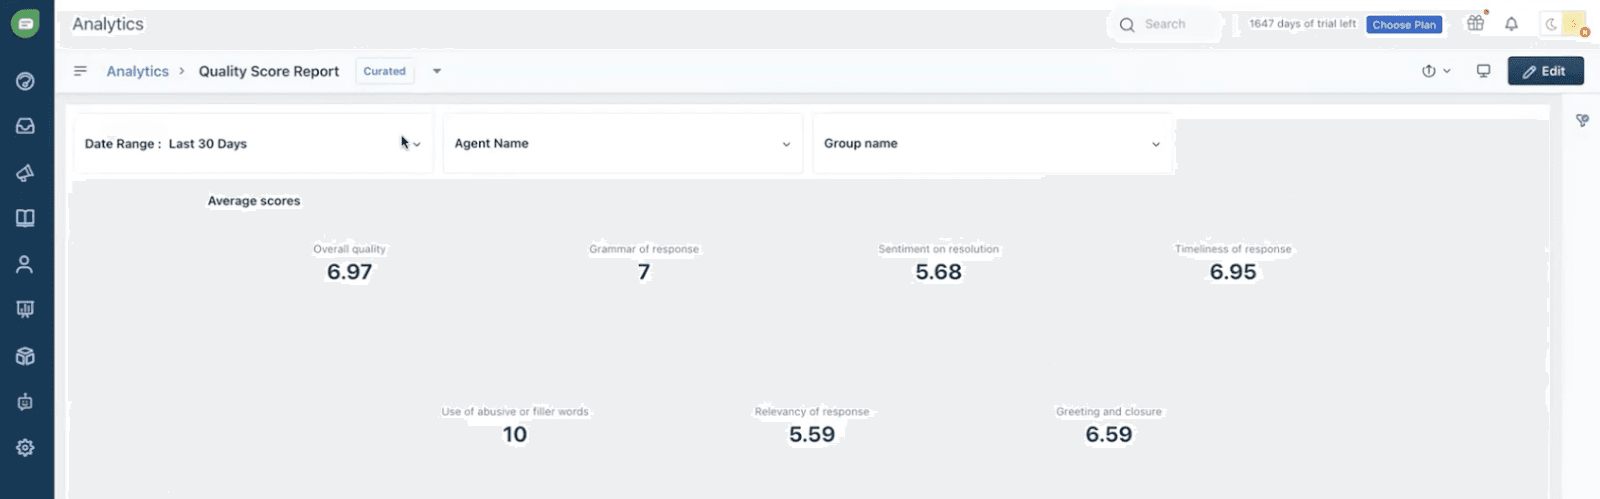
Admins get the Quality Score Report under Reports, in the Chat Analytics category. It shows scores weekly or monthly, at group and agent level, with a trend over time and a breakdown by agent. Freshworks notes Freddy "could take couple of minutes to generate the Quality Score".
Two things to know before you buy for this. Freshworks last updated the article on 27 June 2024, and it says the feature "is currently available as an add-on for Freddy Copilot", so confirm current packaging with your account manager. And Copilot is a flexi add-on bought per agent, so check which agents' conversations get scored before you budget for a subset; the article doesn't say.
What does Proactive Quality Coach do?
Proactive Quality Coach works before the reply goes out. When an agent clicks Send, Freddy checks the message on seven parameters in this order: "Abusive Words > Spelling Check > Grammar > Too long > Filler words > Tone > Relevancy". It can tell five good tones (such as empathetic and solution oriented) from five bad ones (such as defensive and sarcastic), highlights each problem in its own colour, and lets the agent accept or ignore each suggestion.
It's off by default, it can be switched on per role, and Freshworks lists it as "available in Beta for all customers on Pro and Enterprise plan, as part of the Freddy AI Copilot addon". Admins see how many suggestions were shown, accepted and rejected in the Freddy reports.
Pair the two and you have a coach on both sides of the Send button. Both work on how the reply is written. Neither checks it against what your team has decided. For a full read of past chats, see my guide to reviewing AI support conversations.
What can't Freshchat's Quality Coach check?
Four checks are missing from what Freshworks documents:
- Your policy. None of the six parameters reads your help center or your rules, so a polite, well-written wrong answer can score well on most of them.
- Fields, topics and routing. The parameters are all about the messages. Nothing checks that a billing chat went to the billing group or got the right conversation field.
- Your own criteria. The article lists six fixed parameters and no way to add a seventh, such as "always offer the warranty check first".
- The bot's side. The article talks about agents' conversations. It doesn't say whether chats the Freddy AI Agent handles alone get a score, so don't assume they do.
That's the gap most QA programs exist to close. Speed, tone and grammar are visible to customers, but a wrong refund promise is the one that costs money.
How much does Freshchat QA cost?
Freshchat's pricing page lists these plans on 22 November 2026, per agent a month billed annually. Freddy AI Copilot pricing comes from Freshworks' Freddy AI features and pricing article.
| Plan | Per agent a month, billed annually | What it adds for QA |
|---|---|---|
| Free | $0, up to 10 agents | Not listed for Quality Coach |
| Growth | $19 | Not listed for Quality Coach |
| Pro | $49 | Can buy Freddy AI Copilot at $29 per agent a month, which carries both Quality Coach features |
| Enterprise | $79 | Same Copilot add-on |
Copilot is $35 per agent on monthly billing. For a 10-agent team moving from Growth to Pro with Copilot for everyone, billed annually: Pro is 10 x $49 = $490, Copilot is 10 x $29 = $290, so $780 a month against $190 on Growth. Copilot also brings draft replies, summaries and the rest, covered in my Freddy AI pricing post, so QA is rarely the only reason to buy it.
How do you cover what Freshchat leaves out?
There are two ways to cover the rest.
Score a sample by hand
The cheapest route needs nothing new. Each week a lead takes ten or twenty resolved chats, starting with the unsatisfactory CSAT ratings, the reopened conversations and any Bad labels from Quality Coach, reads each, and scores it against a short rubric: right answer for the policy, right group and fields, process followed. Agree what each score means first so two reviewers score the same chat the same way: support QA calibration helps, and this guide to support QA with AI shows where AI speeds it up.
The limit is the obvious one: a person reads a sample, and the results live in a spreadsheet, not on the chat.
Have an AI teammate review against your rules
The second route is an AI agent that reads the chats and leaves its verdict in Freshchat. This is what I'd do with eesel. eesel joins Freshchat as a channel on its Freshdesk integration. When someone on your team asks, in the dashboard chat, a Slack mention or a scheduled run, it can read any chat's messages, its group, assignee, status and custom fields, and Freshchat's CSAT and response time numbers. It reads your help center, canned responses and past Freshdesk tickets, so a policy you've published is something it has read.
Give it the chats to check (paste the links of this week's low-rated chats, for example) and it:
- Reads each conversation with its properties.
- Checks it against the rules you wrote in plain words ("damaged items get a replacement first, not a refund", "billing questions go to the billing group", "never promise a delivery date").
- Leaves its verdict and reasons as a private note, which the team sees and the customer never does.
- Lists the chats a lead should read, with the reason for each.
You write the rules, so routing, process and policy checks are just more lines, changed whenever your policies change. Know the limit first: eesel has no command to list every resolved chat in Freshchat, so it reviews the chats you give it rather than sweeping the inbox by itself. If your team also works email in Freshdesk, the same agent can check those tickets too.
Daily checks like this already run for eesel's customers. Cactus Club Cafe runs a second eesel agent on its Zendesk helpdesk that audits the daily finance extract every morning: it checks each store and either solves the ticket as balanced or leaves it open with the imbalance named. Between 8 August and 8 September 2026 it ran about 60 times. A QA review is the same shape: a check against written rules, with the result left where the team works.
Is Freshchat's Quality Coach enough for QA?
For coaching, it's a good start. A score on every resolved conversation, shown to the agent who handled it, with tips, is a real head start, and the Quality Score Report gives a lead a trend per agent without anyone reading a transcript. Proactive Quality Coach fixes tone and grammar before the customer sees them.
My take: if you're already on Pro and buying Copilot for drafts and summaries, turn both Quality Coach features on and use the Bad labels and unsatisfactory CSAT ratings as your weekly reading list. Don't treat a Good label as "correct": it means well written and well received. If your QA question is "was it right for our policy?", Freshchat leaves that to you: a hand-scored sample if your volume is small, an AI reviewer if it isn't. Other helpdesks' answers to the same question are in my posts on Gorgias AI quality assurance, Front AI quality assurance and Help Scout AI quality assurance, and my roundup of AI tools for support QA compares dedicated options. For the rest of Freddy in chat, see Freshchat AI sentiment analysis and Freshchat AI draft replies, and conversation summaries for handoffs. Weighing a move instead? See Freshchat alternatives.
Try eesel as your Freshchat policy reviewer
If the check you're missing is "was this reply right for our policy?", eesel is the reviewer I'd add next to Quality Coach. It connects through your Freshdesk account, reads your help center and past tickets, and checks the Freshchat conversations you point it at against the rules you write, leaving its reasons in a private note. Start with ten of last week's low-rated chats in the dashboard chat, read what it flags, and keep the rules that catch real misses.

Try eesel free, or book a demo to see it review your own Freshchat conversations.