Claude Opus 5.5 pricing at a glance
Claude Opus 5.5 launched on September 22, 2026, described by Anthropic as performing "at the level of Claude Fable 5.1 on most work" while costing meaningfully less to run than Opus 5. The rate card broke the pattern the Opus line had held since Opus 4.5.
| What you pay for | Claude Opus 5.5 rate |
|---|---|
| Input tokens | $4 per million |
| Output tokens (including thinking) | $20 per million |
| 5-minute cache write | $5 per million |
| 1-hour cache write | $8 per million |
| Cache read | $0.20 per million |
| Batch API input / output | $2 / $10 per million |
| Fast mode input / output | $8 / $40 per million |
US-only inference (inference_geo) | 1.1x every token category |
Every figure above comes from Anthropic's pricing docs. A few specs shape the bill more than the rate does:
- The model ID is
claude-opus-5-5on the Claude API,anthropic.claude-opus-5-5on Bedrock, and the same dateless ID on Vertex and Foundry. - Context is 1M tokens in, 128k tokens out, rising to 300k output on the Batch API with a beta header.
- The reliable knowledge cutoff is June 2026, up from May 2026 on Opus 5.
- The default effort setting is now
medium, down fromhighon Opus 5. That single default change lowers the typical bill before you tune anything.
If you are pricing this against the previous generation, our Opus 5 pricing guide carries the old $5 and $25, and the Opus 4.6 breakdown carries the same, which makes the version-to-version comparison unusually clean.
The 20% cut that is really a 40% cut
Here is the part that matters most for a budget. The sticker dropped 20%, but Anthropic's headline claim is that Opus 5.5 costs about 40% less to run on typical workloads. The gap between those two numbers is the whole story of this release.
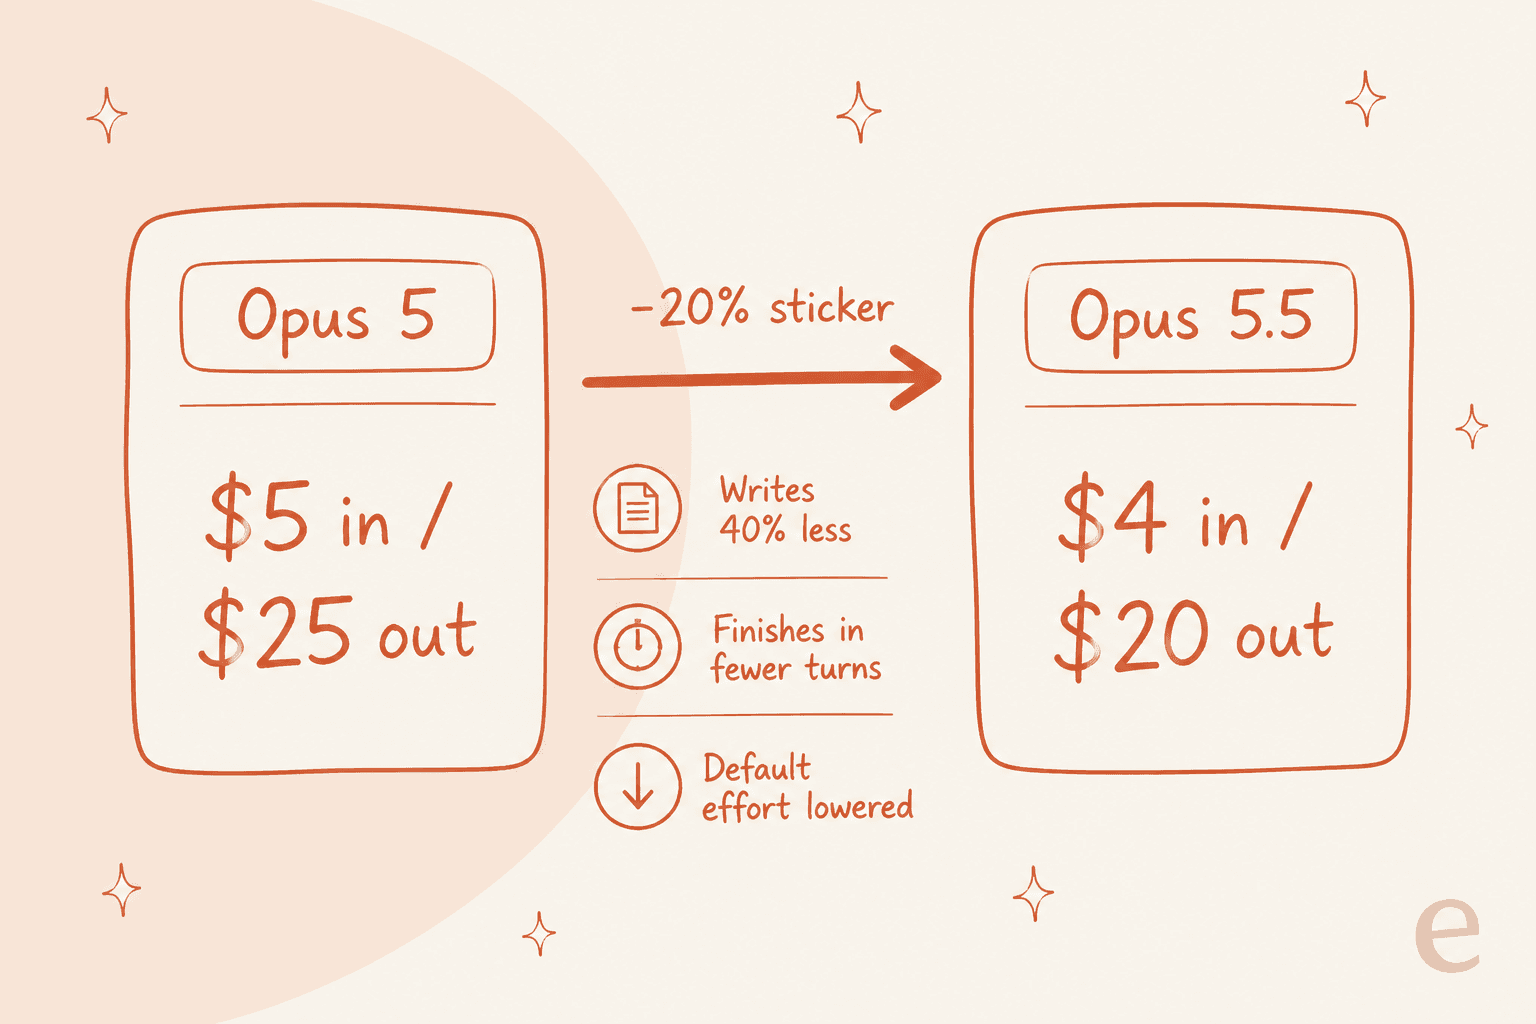
The extra 20% comes from the model spending fewer tokens on the same task. Three levers do it:
- It writes less. Box, an early-access customer, reported answers that are "40% less verbose without losing accuracy" in Anthropic's announcement. Every word saved is an output token you do not pay $20 for.
- It finishes in fewer turns. In an agentic loop, each turn re-sends the growing transcript as input. Per the same Anthropic post, GitHub had Opus 5.5 solving terminal tasks in "less than half the steps" of Opus 5, which compounds directly into a smaller bill.
- The default effort dropped. Opus 5 shipped defaulting to
high; Opus 5.5 defaults tomedium, so the out-of-the-box spend profile is lower unless you deliberately dial it up.
The one cut that has nothing to do with your prompt is caching. Cache reads fell 60%, from $0.50 to $0.20 per million, because Opus 5.5 uses a 0.05x cache-read multiplier where every other Opus used 0.1x. For any workload with a stable system prompt, that is a straight discount you get with zero code changes.
What you are actually billed for
Opus 5.5 keeps the adaptive thinking behaviour Opus 5 introduced: thinking is always on, steered by the effort setting, and every thinking token is billed as output at $20 per million.
Two knock-on effects worth budgeting for:
max_tokenscovers thinking and the answer together. A ceiling tuned tightly around the visible response can truncate mid-answer at high effort. Anthropic's migration guide is the place to reset those limits when moving from an older model.- Tool results re-enter as input. In agentic loops, every tool result you hand back is paid for again on the next turn. If your loop pulls context through MCP tools or Claude Skills, each of those results lands on the input side of the same invoice, which is exactly why the cheaper cache read matters so much here.
The good news for anyone migrating from Opus 5 is that the two behaviours that inflated bills, verbosity and scope creep, are the two Anthropic says it worked on. Whether that holds in your workload is a question your own eval answers, not the rate card.
One model, four prices
The same weights and the same model ID bill at four different rates depending purely on how you call them.
Prompt caching is the biggest lever for anything with a stable prefix. Writes cost 1.25x base input on the 5-minute cache and 2x on the 1-hour cache. The read is the standout: at a 0.05x multiplier a cache hit costs just $0.20 per million, half the effective rate of any other model in the lineup.
Batch takes 50% off both directions to $2 and $10, and it stacks with caching. If your workload tolerates a queue, this is free money.
Fast mode goes the other way. Per the fast mode docs it delivers up to 2.5x higher output tokens per second for double the price, at $8 and $40. Worth naming precisely: fast-mode Opus 5.5 now costs less per token than standard Claude Fable 5, where fast-mode Opus 5 exactly matched it. It is a research preview on the first-party API only, and does not work with Batch.
US-only inference adds a flat 1.1x on every token category, which works out to $4.40 and $22.
Effort is still the real price knob
Opus 5.5 keeps the effort dial, and the guidance is to start at the new medium default and reach up only when a task needs it. That is a change from Opus 5, which defaulted to high, and it is the clearest signal that Anthropic wants the typical run to be cheaper by default.
Anthropic's launch benchmarks all use the model at effort, and they are worth reading as a value chart rather than a leaderboard:
| Benchmark | Claude Opus 5.5 | Claude Opus 5 |
|---|---|---|
| Terminal-Bench 4.0 | 66.4% | 52.3% |
| FrontierCode v1.1 | 54.4% | 48.0% |
| CursorBench 4.0 | 57.8% | 46.6% |
| GDPval-AA v2.1 | 1846 Elo | 1708 Elo |
| OSWorld 2.0 (partial) | 81.8% | 74.0% |
Every figure is from Anthropic's announcement. Read them against the 20% lower price and the shape is consistent: higher scores at a lower rate. That is a more useful claim than any single number, and it is the argument the whole release rests on.
Work out your own monthly bill
Sticker rates only become real once you put your own volume against them. Plug in a month of usage and see what the levers do.
At the default 200M input and 40M output with no levers, that is $800 of input and $800 of output, or $1,600 a month. Turn on 1-hour caching for a stable system prompt and route half your input through it, and the input side alone drops by roughly 45%.
How Opus 5.5 prices against the rest of the lineup
| Model | Input / MTok | Output / MTok | Context | Where it fits |
|---|---|---|---|---|
| Claude Fable 5.1 | $10 | $50 | 1M | The capability ceiling |
| Claude Opus 5.5 | $4 | $20 | 1M | Agentic coding, knowledge work |
| Claude Opus 5 | $5 | $25 | 1M | Previous generation |
| Claude Sonnet 5 | $2 | $10 | 1M | Volume work |
| Claude Haiku 4.5 | $1 | $5 | 200K | Classification, routing |
Anthropic's own steer is to start with Opus 5.5 for most work and step up to Fable 5.1 only when your evals at higher effort still fall short. That is a notable promotion: Opus is now the recommended default, not the premium option you reach for last.
Against the rest of the market, our comparisons of Gemini pricing and GPT-5.6 pricing put the Opus line in the expensive-but-efficient bracket, and the 20% cut narrows that gap. The three-way API comparison is the fastest way to sanity-check a switch.
What real workloads actually cost
Rates are abstract. The customer numbers Anthropic published with the launch are not.
- GitHub reported Opus 5.5 solving more terminal tasks than Opus 5 in less than half the steps. Half the steps in an agentic loop is close to half the token bill.
- Optiver matched Opus 5 quality "in about half the turns, time and output tokens," according to Anthropic. That is the 40% run-cost claim showing up in a named customer's own metering.
- Box measured answers that were "40% less verbose without losing accuracy," per the launch post. Verbosity is billed at $20 a million, so less of it is a direct saving.
These are vendor-supplied and self-selected, so weigh them as directional rather than independent. But they all point the same way, and they are the mechanism behind the headline: the price fell on paper, and the token count fell in practice.
For a repeatable baseline, Anthropic's worked example on the older Opus 5 rate put a one-hour session at 50,000 input and 15,000 output tokens for about $0.70 including runtime. Rerun that on Opus 5.5's $4 and $20 and the token portion alone drops by a fifth before any of the efficiency gains land.
Claude Pro, Max, Team and Enterprise
Not everyone reaches for the API. Per the Claude pricing page, Opus 5.5 is the default model on Claude Max and the strongest model available on Claude Pro.
| Plan | Monthly | Annual | Opus 5.5 access |
|---|---|---|---|
| Free | $0 | $0 | No, Sonnet and Haiku only |
| Pro | $20 | $17/mo | Yes |
| Max 5x | $100 | Monthly only | Yes, default model |
| Max 20x | $200 | Monthly only | Yes, default model |
Two details that trip up buyers:
- Limits are session-based, not message-based. They reset on a rolling window with weekly caps on top, and web, desktop, mobile and Claude Code all draw from one pool. There is no message count to plan against.
- Paid plans spill into API rates. Hit a limit and you can enable usage credits to keep working at standard rates, which is where the $4 and $20 above start applying to a subscription seat.
For teams weighing the subscription route against raw API spend, our Claude Code pricing guide covers the seat math and the enterprise walkthrough covers rollout. Model configuration is where you pin Opus 5.5 rather than letting it pick. Team and Enterprise seats are quoted through Anthropic sales rather than a public per-seat number.
Bedrock, Vertex, Foundry and the CCU wrinkle
Opus 5.5 is available on all platforms from day one, but the billing is not identical.
- Amazon Bedrock and Google Vertex are partner-operated. The cloud provider invoices you, and Anthropic points at Bedrock pricing and Vertex AI pricing as the source of truth rather than publishing rates itself.
- Regional endpoints carry a 10% premium over global ones on both clouds.
- Claude Platform on AWS and Microsoft Foundry bill in Claude Consumption Units, rated in USD at standard rates then converted at $0.01 per CCU with hourly metering. Your invoice shows one CCU line item, not a token breakdown.
- Fast mode is first-party only. It does not exist on Bedrock, Vertex or Foundry.
If your finance team is reconciling an AWS bill against a per-token model, the CCU conversion is where the two stop lining up.
What developers are saying
The launch-week reaction turned immediately on the one question a pricing page cares about: does the "less verbose, cheaper to run" claim hold, given that verbosity is exactly what you pay $20 a million for. Some found it real.
"after a few hours use, my impression is that Opus 5.5 writes like gemini. drastic improvement over all opus 5.1's claudeisms."

"The current tests confirms Opus 5.5 is not verbose. In fact, it outputs using ASD-STEM100 as I recommend. It's a blessing."
Others were not convinced the verbosity, and the spend behind it, had actually changed.
"So far it seems the same. I used Opus 5.5 for an hour this evening and it was just as painfully verbose as Opus 5. It also used the term 'load bearing' 4 separate times."
And the sharpest cost read compared it to the competition rather than to its predecessor:
"while the Codex subscription appears to get you much fewer tokens as measured by cost, I find the amount of actual useful work that can be done by both subs to be about equal. Codex seems much less prone to burning millions of tokens just reading the codebase and doing nothing useful."
My read: the rate cut is unambiguous and on paper, but the 40% run-cost claim is a workload-dependent average, not a guarantee. If your prompts already control length, you were not paying the verbosity tax that Opus 5.5 removes, so your saving is closer to the flat 20%. Meter your own tokens before and after rather than trusting the headline.
Is Claude Opus 5.5 worth $4 and $20?
For long-horizon agentic work, this is the easiest yes the Opus line has offered in a while. You are paying 20% less than Opus 5 for a model Anthropic positions at Fable 5.1's quality level, with cache reads at a fifth of the old rate on top. When a run finishes in half the steps, the cheaper-per-token model was never the cheaper model.
Two honest caveats before you standardise on it:
- The 40% figure is an average, not a floor. It leans on the verbosity and turn-count improvements, so a workload that already ran tight will see closer to the flat 20% cut. Real savings live in your own metering.
- Cheaper models still win a lot of work. For classification, routing and bulk drafting, Claude Sonnet 5 at half the price is the better buy, and Haiku is better still. If you are shopping around, our Opus 4.6 alternatives roundup covers the field, with Mistral pricing at the cheaper end.
Where the model lands in a real toolchain is a separate question from the rate card. Our roundups of AI coding assistants, Claude developer tools and Cursor are where that gets decided in practice. For the record, my own default is medium effort with 1-hour caching on the system prompt and Batch for anything that can wait, which lands most jobs well under half the naive standard-rate bill.
Where the token bill stops being your problem
Everything above assumes you want to own the plumbing: the retry logic, the effort tuning, the cache invalidation, the fallback when a safety classifier declines a request. That is a real engineering project, and I have watched several technical customers leave eesel to build exactly that on the Claude API directly.
The pattern is that the model is infrastructure and you still have to hire the employee. Opus 5.5 is a superb engine; it is not a support agent, a triage system, or a blog writer until someone builds those around it. eesel is that layer already assembled. It sells ready-to-work AI teammates, an AI helpdesk agent that joins your support queue and an AI blog writer, each arriving with the skills, integrations and company context for its job, with a frontier model like Opus 5.5 running underneath and the token spend already inside the price.

For anyone who does want the programmable surface, eesel exposes the same teammate through a CLI, MCP server and webhooks, so a person can drive it from a terminal, scripts can automate it, and coding agents like Claude Code or Cursor can operate it directly, without you rebuilding the retry-and-grounding stack that the raw API leaves to you. Some teams still choose to build. Others end up where this one did:
"We could try to write our own LLM application but we didn't want to invest our time into that. We wanted something that we would not have to maintain."
Karel, GENERAL BYTES
If you want a frontier model answering support tickets, the token rate is maybe a fifth of the work. You can simulate eesel against your own historical tickets before it replies to anyone, and connect it in a few minutes. Try eesel free.
If content rather than support is your use case, the same logic drives our AI blog writer, and the guides to the best LLM for blogging and making AI sound human are the place to start.
Frequently Asked Questions
How much does Claude Opus 5.5 cost per million tokens?
Is Claude Opus 5.5 cheaper than Claude Opus 5?
What is the cheapest way to run Claude Opus 5.5?
Does Claude Opus 5.5 pricing change on the 1M context window?
How much does Claude Opus 5.5 cost on the Pro and Max plans?
Is Claude Opus 5.5 or Claude Sonnet 5 better value?
What is Claude Opus 5.5 fast mode pricing?
How much does Claude Opus 5.5 cost on Bedrock, Vertex or Azure?


Article by
Kurnia Kharisma Agung Samiadjie
Kurnia is a software engineer and writer at eesel AI with two years of SEO experience, writing about AI tools, helpdesk software, and customer support. He pairs a developer's understanding of how these products are built with search-driven research into what actually ranks and resonates with the people searching for them.