GPT-6 Sol API pricing: the standard tier
Here is the number most people came for. On the API pricing page, GPT-6 Sol standard pricing is $2.00 per million input tokens and $10.00 per million output tokens. Cached input drops to $0.20, and cache writes are $2.50 per million.
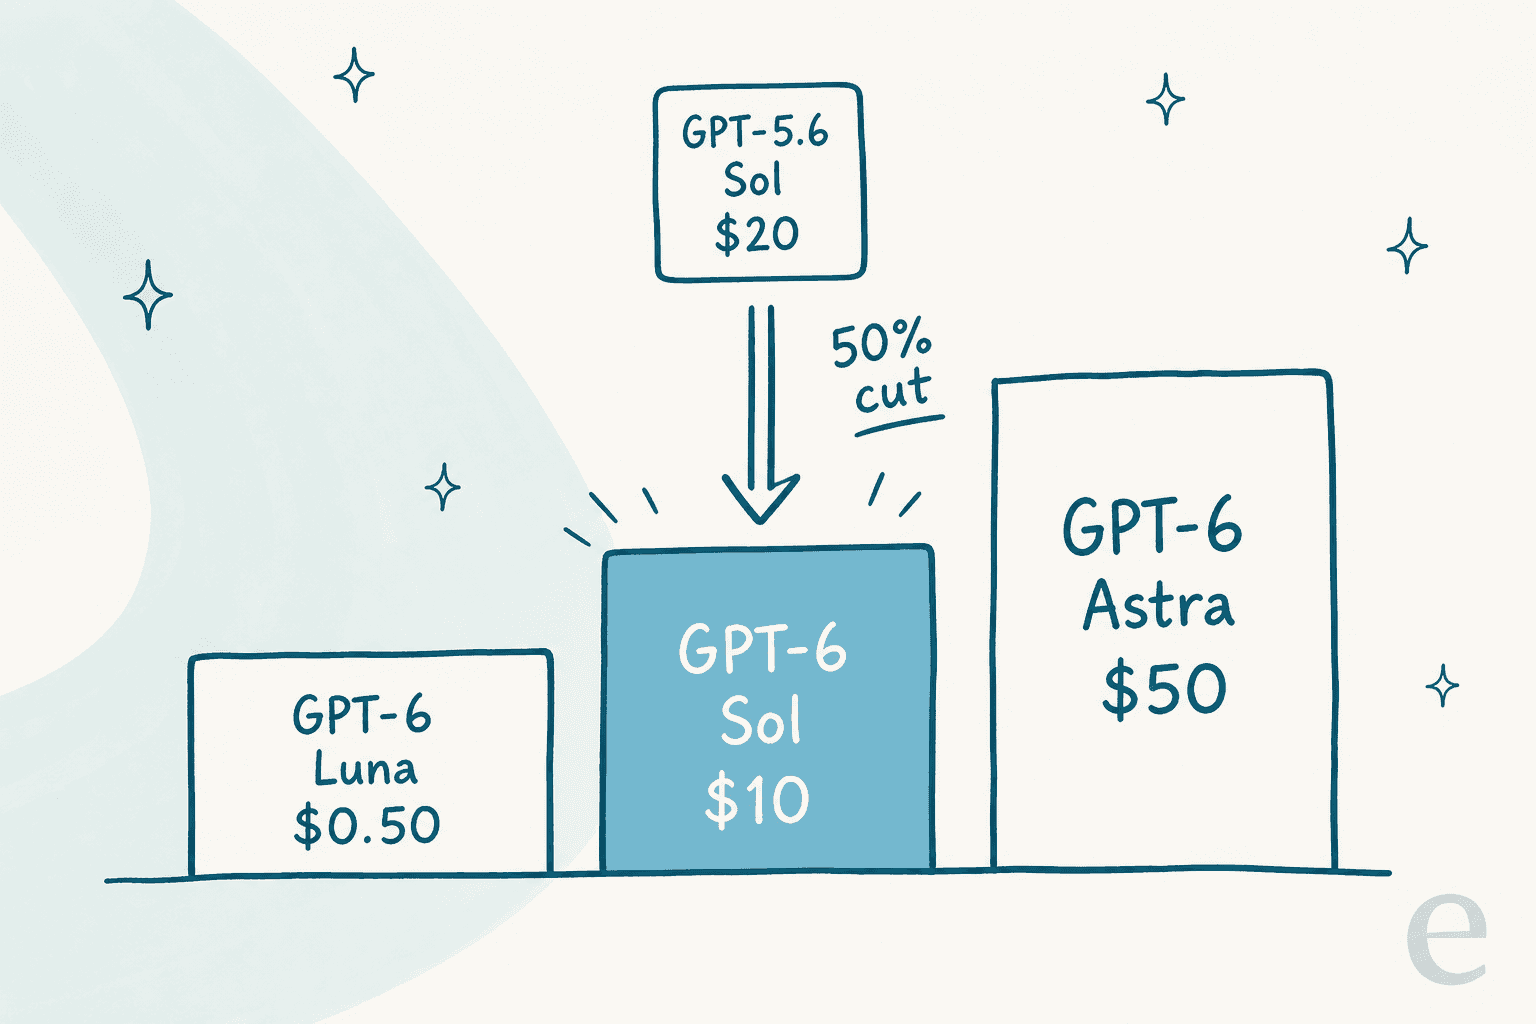
That places Sol squarely in the middle of the OpenAI model lineup: well above the featherweight Luna, and far below the Astra flagship. Here is where the GPT-6 family sits on the standard, short-context tier, with the outgoing GPT-5.6 Sol for reference:
| Model | Input (per 1M) | Cached input | Output (per 1M) | Position |
|---|---|---|---|---|
| gpt-6-astra | $10.00 | $1.00 | $50.00 | Flagship |
| gpt-6-sol | $2.00 | $0.20 | $10.00 | Mid tier (new) |
| gpt-6-luna | $0.10 | $0.01 | $0.50 | Cheapest |
| gpt-5.6-sol | $4.00 | $0.40 | $20.00 | Prior mid tier |
Source: OpenAI API pricing. The story the table tells is simple: GPT-6 Sol is the old GPT-5.6 Sol at half price. OpenRouter confirmed the same rates on launch day, Sol at "$2/M input and $10/M output." OpenAI's own framing on the launch post is "Build with Sol. Scale with Luna," which tells you where each model is meant to sit.
The 50% cut: what changed, and what did not
A price cut this size usually comes with a capability story. This one mostly does not, and that is worth being honest about.
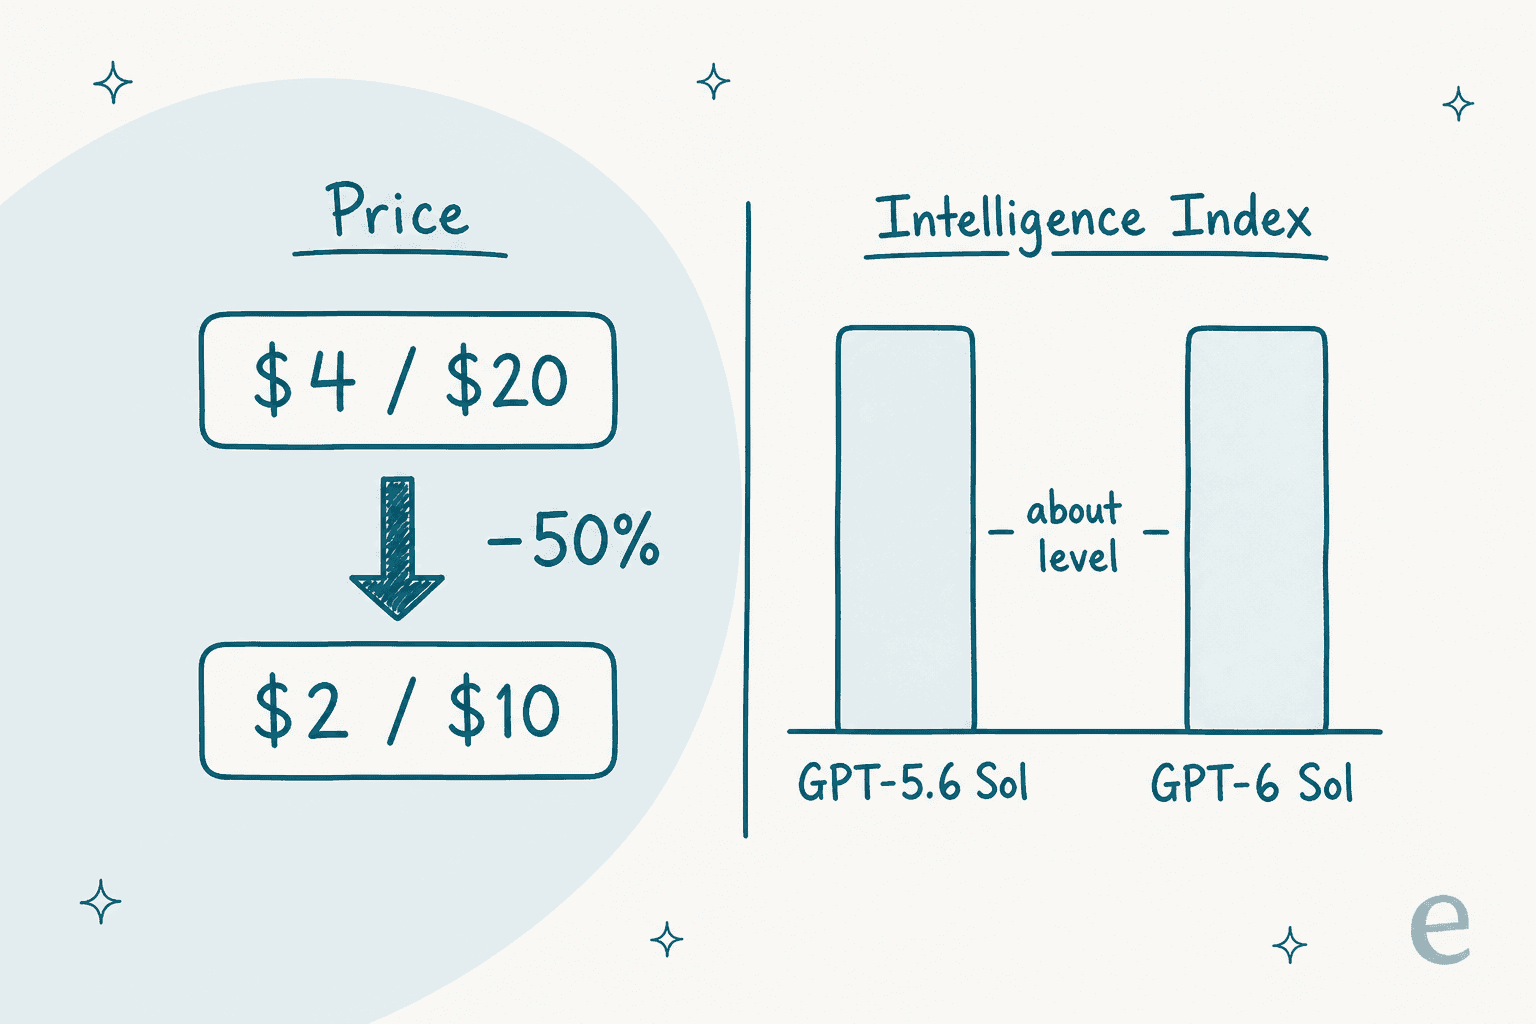
On the raw intelligence measure, Artificial Analysis reported that GPT-6 Sol and Luna "push the cost efficiency frontier by halving cost," while the Intelligence Index and Coding Agent Index "remain level with GPT-5.6, with progress in some evaluations and regressions in others." So the map is: the price moved a lot, the intelligence barely moved.
Where Sol did improve is reliability and coding throughput, and OpenAI leaned on both:
- Factuality. OpenAI reports GPT-6 Sol makes about half as many factual mistakes as GPT-5.6 Sol, approaching Astra-level reliability at a fraction of the cost. Artificial Analysis logged the max-effort hallucination rate dropping from 92% to 60%.
- Coding. OpenAI reports 68.8% on DeepSWE v1.1, within about a point of Claude Fable 5's best score at roughly 80% lower cost per task.
- Agentic evals. Artificial Analysis noted small gains on AutomationBench (62% vs 60%) and Terminal-Bench 4.0 (44% vs 40%), and a jump on the AA-Omniscience Index from 22 to 27.
The community read it the same way. On the launch discussion, one developer put the trade plainly:
"I'd have loved improved performance for 2x the price than ~equal performance for 0.5x the price."

That is the honest frame for GPT-6 Sol pricing. If you already ran GPT-5.6 Sol, this is a bill cut you get for free. If you were hoping the "6" meant a step change in raw smarts, the benchmark scores say to temper that.
Service tiers: the 4x swing most people miss
The standard rate is a starting point, not the whole story. GPT-6 Sol runs on the same service tiers as the rest of the family, and the gap between the cheapest and most expensive is 4x for the exact same model. This is the single biggest lever you have on cost.
| Tier | Input (per 1M) | Cached input | Output (per 1M) | Trade-off |
|---|---|---|---|---|
| Batch | $1.00 | $0.10 | $5.00 | 50% off, async, up to 24h |
| Flex | $1.00 | $0.10 | $5.00 | 50% off, slower, may queue |
| Standard | $2.00 | $0.20 | $10.00 | Default latency |
| Fast mode | $4.00 | $0.40 | $20.00 | 2x, lowest latency |
Source: OpenAI API pricing. A few things to know before you pick one:
- Batch and Flex are the same price, but different jobs. Batch is for asynchronous work you submit and collect later; Flex is for interactive requests you are willing to let run slower or queue. Both halve your bill.
- Fast mode doubles the rate for the lowest latency, and it accepts either
service_tier: "priority"orservice_tier: "fast". - Fast mode has a regional catch. For EU data residency it can fall back to standard, so do not assume it everywhere.
If a workload tolerates latency, defaulting it to Batch or Flex cuts your Sol spend in half again, on top of the 50% you already saved moving off GPT-5.6. That stacks: a batchable job on GPT-6 Sol runs at $1/$5, a quarter of last month's GPT-5.6 Sol standard bill.
The gotchas: long context and the spec
Two details hide in the model page fine print, and both can quietly reshape a budget.
First, long context is billed at a higher rate for the whole request. Sol's context window is a large 1,050,000 tokens, but any prompt over 272K input tokens flips the entire request to the long-context rate: $4 per million input and $15 per million output on the standard tier. That is 2x input and 1.5x output, applied to every token in the request, not just the ones past the threshold.
| Standard tier | Short context (≤272K) | Long context (>272K) |
|---|---|---|
| Input (per 1M) | $2.00 | $4.00 |
| Cached input | $0.20 | $0.40 |
| Output (per 1M) | $10.00 | $15.00 |
Second, the spec is worth knowing before you commit. GPT-6 Sol takes up to 922,000 input tokens and returns up to 128,000, with a knowledge cutoff of 20 April 2026. It accepts text and image in, text out, and exposes reasoning effort from none all the way to max, with medium as the default. It also ships the full Responses API tool set: web search, code interpreter, hosted shell, computer use, and MCP. And a floor to remember: Sol is not on the free tier, so Tier 1 is the entry point for developers.
Estimate your GPT-6 Sol API bill
Sticker prices are abstract until you put your own numbers in. Plug in the millions of input and output tokens you expect per month, pick a service tier, and this works out the monthly cost. It accounts for the long-context surcharge automatically.
The pattern most teams find is that output tokens dominate the bill, since output is 5x the input rate. If your workload generates long responses, that is where the money goes, and where switching a batch-friendly job to Batch pays off fastest.
GPT-6 Sol pricing in ChatGPT and Codex
If you are not calling the API, GPT-6 Sol reaches you through ChatGPT Work and Codex, and the plan you are on draws a clear line about who gets it.
| Plan | Price | GPT-6 Sol access |
|---|---|---|
| Free | $0 | No (Luna only) |
| Go | $8/mo | No (Luna only) |
| Plus | $20/mo | Yes |
| Pro | From $100/mo | Expanded |
| Business / Enterprise / Edu | Per seat | Yes |
Source: OpenAI launch announcement. A few things stand out:
- Sol starts at Plus. The $20/month Plus plan is the entry point for ChatGPT users who want Sol. Neither Free nor the $8 Go plan includes it; they get GPT-6 Luna in the desktop app.
- Codex gets Sol too. OpenAI shipped both models into Codex at the same tiers, so coding-agent users on Plus and up can select Sol directly.
- Enterprise is per seat. On Business and Enterprise, Sol is available per seat alongside Edu access, which follows the same pattern as the rest of the OpenAI lineup.
Not everyone was convinced the subscription savings match the API cut. One developer noted that message-limit changes suggested the 50% API cut translated to something closer to a one-third cut inside the ChatGPT plans, so check your own allowance rather than assuming the sticker discount flows straight through.
How GPT-6 Sol pricing compares
Zooming out, where does Sol sit against the rest of the frontier? The short version is that OpenAI used Sol to compete hard on price in the middle of the market.
- Versus its own lineup: at $2/$10, Sol is one fifth the price of GPT-6 Astra ($10/$50) and 20x the price of Luna ($0.10/$0.50). For most everyday tasks, Sol is the sweet spot; for long-horizon agentic or security work, Astra's premium can still be worth it.
- Versus Anthropic: Sol undercuts Fable 5.1 at $10/$50 by a wide margin, while OpenAI claims coding scores within a point at the top.
- Versus Google: it sits above the lightest Gemini options like Gemini 3 Flash, but competes directly with the mid tiers on a price-for-intelligence basis.
The bigger picture on the launch thread was that closed models keep getting cheaper without getting much smarter, which several developers framed as a race to the bottom on price. That is good news if you are buying tokens. It is a reminder, though, that a cheaper model does not change the harder part of shipping AI into a real workflow, which is everything around the model.
What GPT-6 Sol pricing means if you run a support team
Here is where I want to be useful rather than just tally rates, because I spend my time on how these models actually get used, and the honest answer is a little counterintuitive.
If you run customer support or internal ops, a cheaper frontier model changes less than the headline suggests. A raw model like Sol is infrastructure. It is a capable engine, but out of the box it does not know your refund policy, it cannot see your last 50,000 tickets, it has no access to your order system, and it has no safe way to be tested against your real queue before it starts replying to customers. It is billed per token for thinking, not per problem solved. A 50% token cut is real, but it is a discount on the cheapest part of the project.
The unit that actually matters for a support team is cost per resolution, not cost per token. A token bill is unpredictable: it moves with prompt length, retries, and how chatty the model is on any given day. I have watched confident-sounding bots quietly give wrong answers on live queues, which is exactly why every rollout should be simulated against your own historical tickets before it goes near a customer. That is the gap between a model and a system built around it: your knowledge, your integrations, safe actions, and a way to test it on your history first.
This is also why I would not re-platform your support automation the week a new model ships. The best AI helpdesk agents and customer service tools are model-flexible by design, so when a cheaper or smarter model lands, you inherit the upgrade without rebuilding anything, and without renegotiating your budget around a new token rate.
Try eesel
If your interest in Sol's price is really "what will an AI cost me to actually resolve tickets," that is the job an AI teammate is built for, and it is where eesel sits. GPT-6 Sol is the engine; eesel is the employee you hire to drive it. The AI helpdesk agent trains on your past tickets and help center, plugs into the helpdesk you already run instead of replacing it, and lets you simulate it against thousands of your real historical tickets so you see how it will perform, and what it will cost, before it ever touches a live conversation.
The billing tells the story a token rate cannot. Instead of paying per token to think, you pay 40¢ per ticket it actually handles, with no per-seat fees and no platform minimum, so the cost tracks outcomes rather than model chatter. You can start free with $50 of usage and no credit card.

And because this is a developer-facing pricing question, it is worth knowing the whole eesel workspace is drivable from the terminal, not just a dashboard. The eesel CLI (npx @eesel/cli) lets a person, a script, or a coding agent like Claude Code, Codex, or Cursor operate the same teammate: connect a helpdesk, read and edit the standing instructions, run eesel activity to inspect past runs, and gate changes behind eesel approvals. Every command prints JSON, and --dry-run shows the exact server call a write would make before it sends. So the same per-resolution billing you would model in this calculator is something you can wire into your own tooling, not just click through in a UI.
GPT-6 Sol pricing is a real deal on tokens, and for coding and everyday work the 50% cut is worth taking. But for most support teams, the token rate was never the number that mattered. Getting a tested, connected, accountable teammate into your existing workflow, billed by the outcome, is the part worth spending your budget on.
Frequently Asked Questions
How much does GPT-6 Sol cost on the API?
Is GPT-6 Sol cheaper than GPT-5.6 Sol?
What is the GPT-6 Sol long-context surcharge?
How much is GPT-6 Sol in ChatGPT and Codex?
What do Batch and Fast mode change about GPT-6 Sol pricing?
GPT-6 Sol vs GPT-6 Astra pricing: which should I use?


Article by
Kurnia Kharisma Agung Samiadjie
Kurnia is a software engineer and writer at eesel AI with two years of SEO experience, writing about AI tools, helpdesk software, and customer support. He pairs a developer's understanding of how these products are built with search-driven research into what actually ranks and resonates with the people searching for them.