

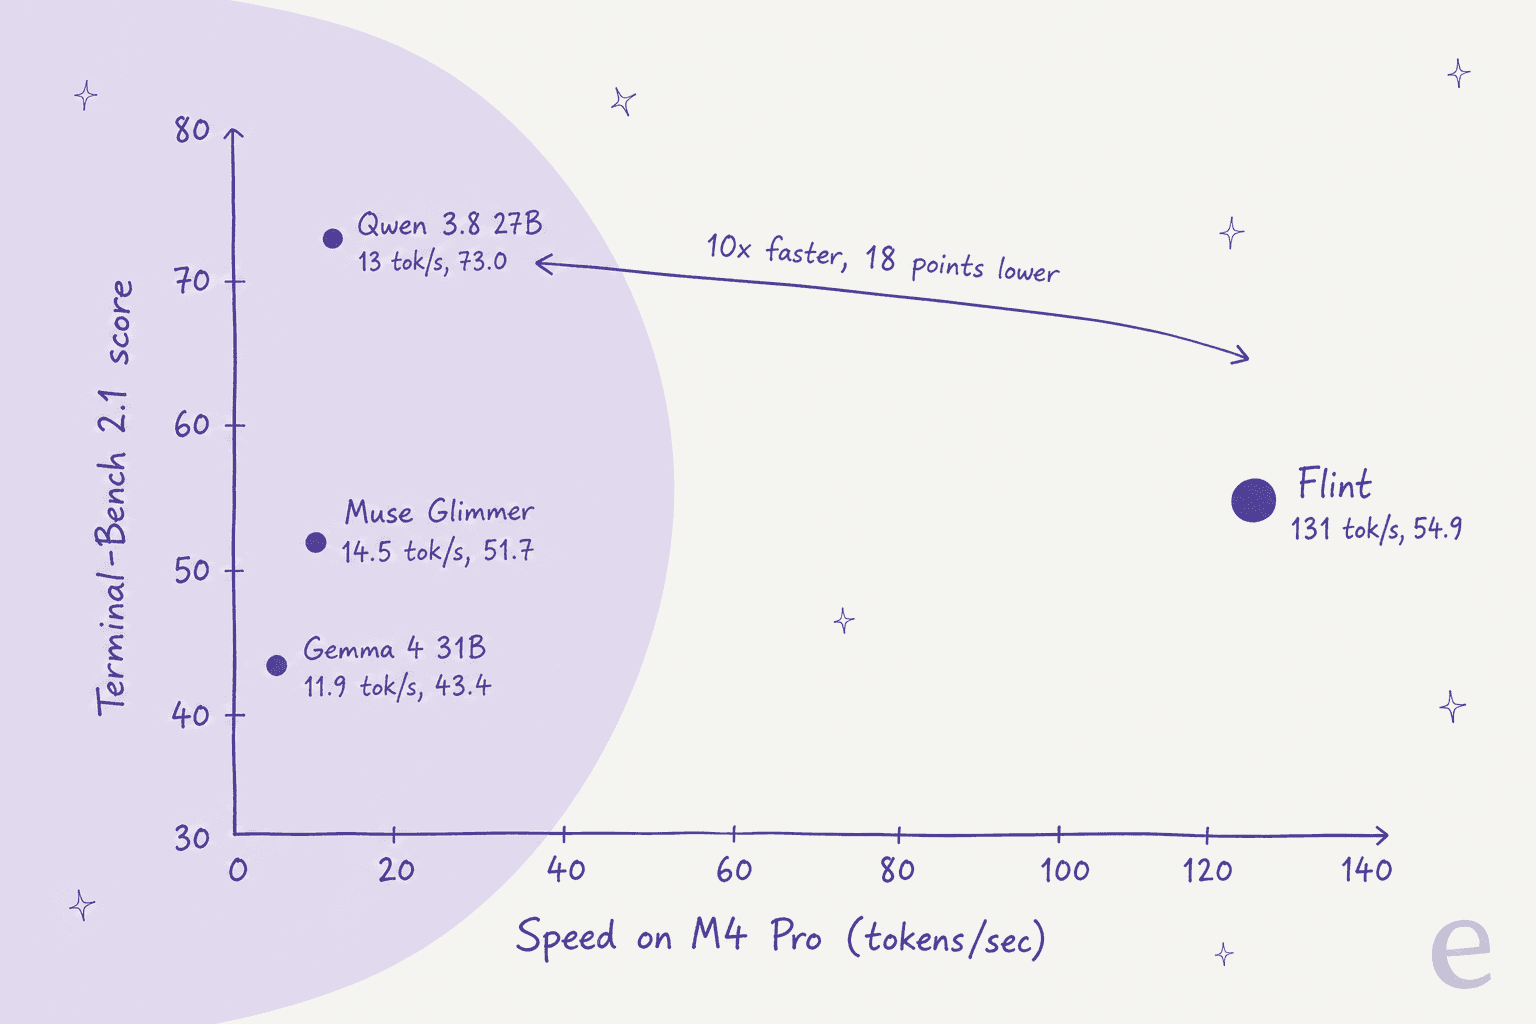
Recursive Flint is the fastest coding model you can run on a laptop today, and it's free, but it isn't the best one. On an M4 Pro MacBook it writes 131 tokens a second, roughly 10x the dense Qwen 3.8 27B, while Qwen 3.8 still beats it on four of six coding benchmarks in Recursive's own chart, including Terminal-Bench 2.1 by 18 points.
My score is 3.5/5. Pick Flint if you want an offline, Apache 2.0 coding agent that keeps up with you, and you're willing to break work into small, explicit steps. Skip it if you need the strongest local model per answer, or a tool loop that never trips: on OpenRouter's free endpoint, 17.74% of tool calls currently error.
If what you actually need is an agent that works a support queue rather than a codebase, a raw model is the wrong layer. eesel's AI helpdesk teammate is the employee on top of models like this one, and your coding agent can drive it from the terminal with the eesel CLI.
What is Recursive Flint?
Recursive Flint is a 40B-parameter mixture-of-experts coding model that activates about 2.5B parameters per token, released on October 21, 2026 by Recursive. It's text in, text out, with always-on reasoning and tool calls, and it's built for one job: running a coding agent that reads a repo, edits files and runs tests. Think of it as the engine under an agentic coding CLI, not a chat app.
Recursive is the lab run by Richard Socher, who is also CEO of You.com. Its stated goal is "recursively self-improving superintelligence," and Flint is the first public test of the system meant to get there: the Eureka Machine, an automated research loop that proposes ideas, implements them, tests them and picks what to try next. Recursive says a small team of people and agents built Flint from scratch in under four months, with the Eureka Machine working on the data, training recipes, quantization and kernels.
I build the integrations and APIs behind eesel's agents, which means most of my week is spent wiring models into tool loops and watching where they break. That's the lens for this review. I read the model card, Recursive's docs, the rec engine repo and OpenRouter's live stats, and I judged Flint on the thing a coding model actually has to do: finish a multi-step task without you babysitting it.
Here are the specs that matter, straight from the model card:
| Spec | Recursive Flint |
|---|---|
| Total parameters | 39.8B |
| Active per token | ~2.5B (about 2.2B without the output head) |
| Experts | 256 per MoE layer, 6 routed per token, plus 1 shared |
| Layers | 49 (2 dense, 47 MoE; 35 sliding-window, 14 full attention) |
| Context | 262,144 tokens documented; up to 512k supported, 256k recommended |
| Max output (hosted) | 65,536 tokens |
| Knowledge cutoff | June 2026 |
| License | Apache 2.0 |
| Input / output | Text / text |
How does a 40B model run this fast on a laptop?
It runs fast because almost all of it sits idle. Every token passes through a router that picks 6 of the 256 experts in each layer, plus one shared expert that always fires, so the chip only reads about 2.5B parameters' worth of weights per token. A dense 27B model reads all 27B, every token.
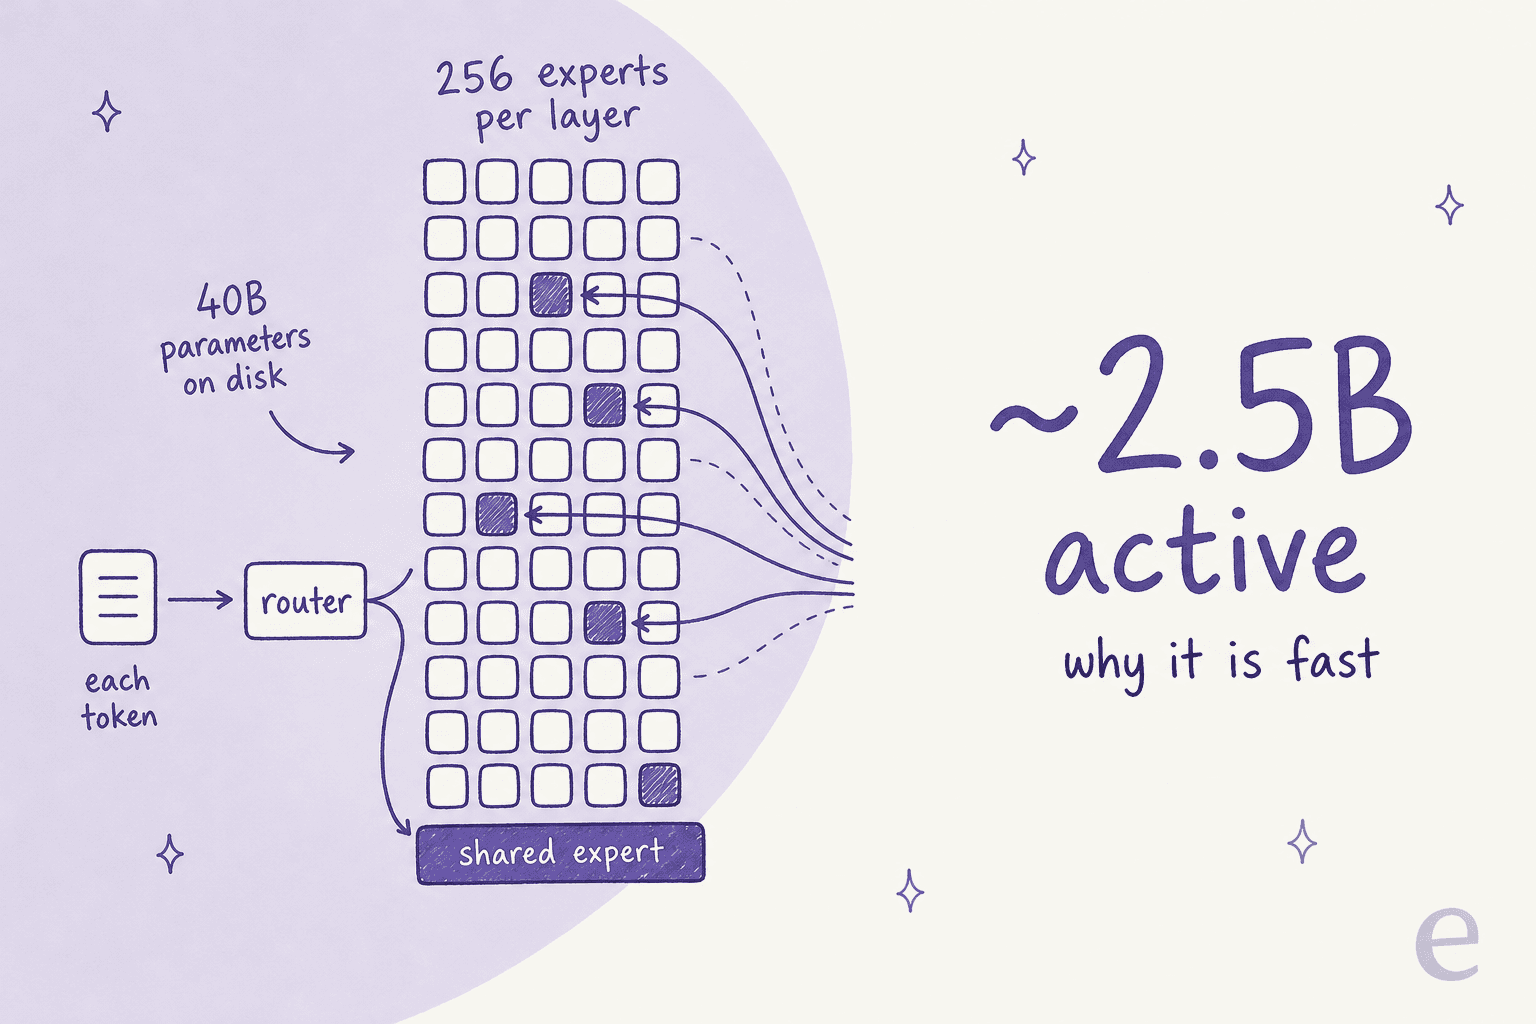
The interesting part is that Recursive didn't stop at the architecture. Per the launch post, the Eureka Machine also searched for quantization recipes and, against common practice, squeezed the output layer to 4 bits. With only 2.5B active parameters, that output layer is a large share of the weights read per token, so shrinking it buys real speed. The final NVFP4 model lands within 0.7 points of the 16-bit one across Recursive's benchmarks, and the LM Studio listing shows the gap per test: 53.7 vs 54.9 on Terminal-Bench, 74.1 vs 74.2 on SWE-bench Verified.
Then it wrote custom kernels, including a Metal "megakernel" that fuses the whole decode pass on M4 and M5 chips. That's why Recursive ships its own engine, rec, instead of just pointing you at llama.cpp. More on that below.
How fast is Recursive Flint in practice?
Very. On Recursive's own chart for an Apple M4 Pro with 48 GB, Flint runs at 131.22 tokens/sec through MLX at a 1K-token context, and 87.98 through llama.cpp. The closest sparse peers are Laguna XS 2.1 at 68.84 and Qwen 3.6 35B-A3B at 65.55. The dense models with comparable coding scores barely move: Muse Glimmer at 14.54, Qwen 3.8 27B at 13.01, Gemma 4 31B at 11.92.

The long-context numbers are what convince me this isn't a short-prompt party trick. Averaged across contexts up to 128K, Flint holds 68.89 tokens/sec on the M4 Pro, while Qwen 3.8 27B drops to 10.11. A coding agent spends most of its life deep in a long context (file contents, test output, its own earlier reasoning), so the average matters more than the headline. On NVIDIA's RTX Spark, the NVFP4 build reaches 155.82 tokens/sec at short context and 101.95 on average.
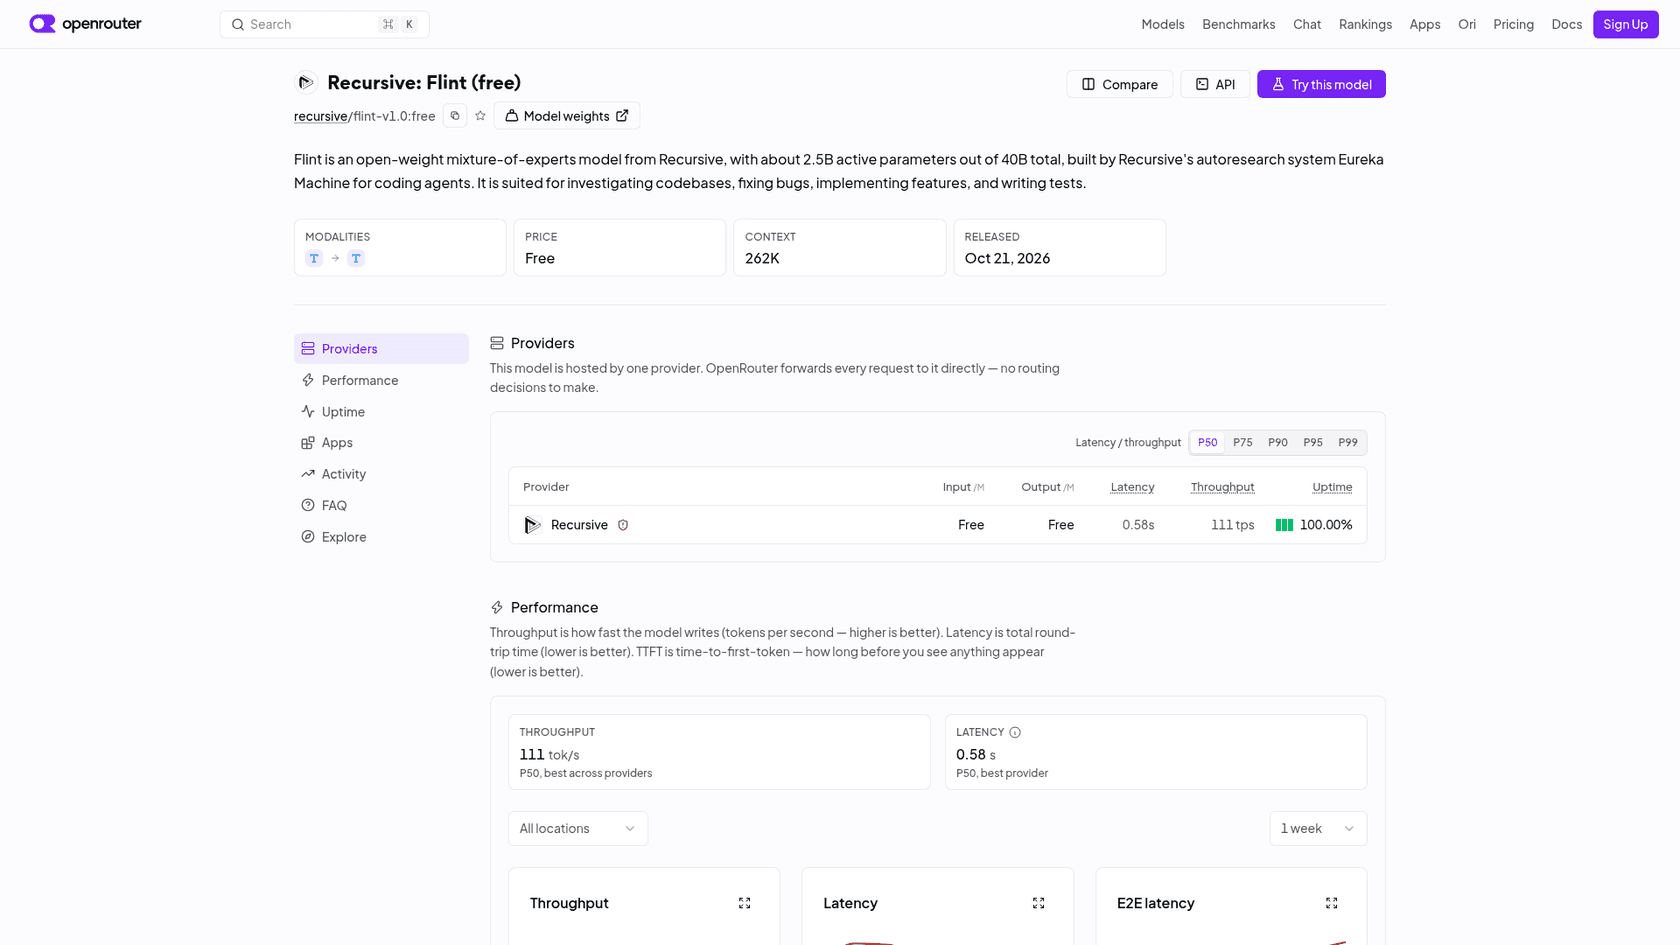
Hosted, it's quick too. OpenRouter's live stats show a P50 throughput of 111 tokens/sec and 0.58s latency from Recursive's single provider endpoint.
Two caveats. These are Recursive's measurements, with prefill excluded, so time-to-first-token on a fat prompt will feel slower than the bars suggest. And the speed only shows up if you use a runtime that supports Flint properly; the troubleshooting page spends a whole entry on CPU offload and memory swapping.
How does Flint score against Qwen 3.8, Gemma 4 and Muse Glimmer?
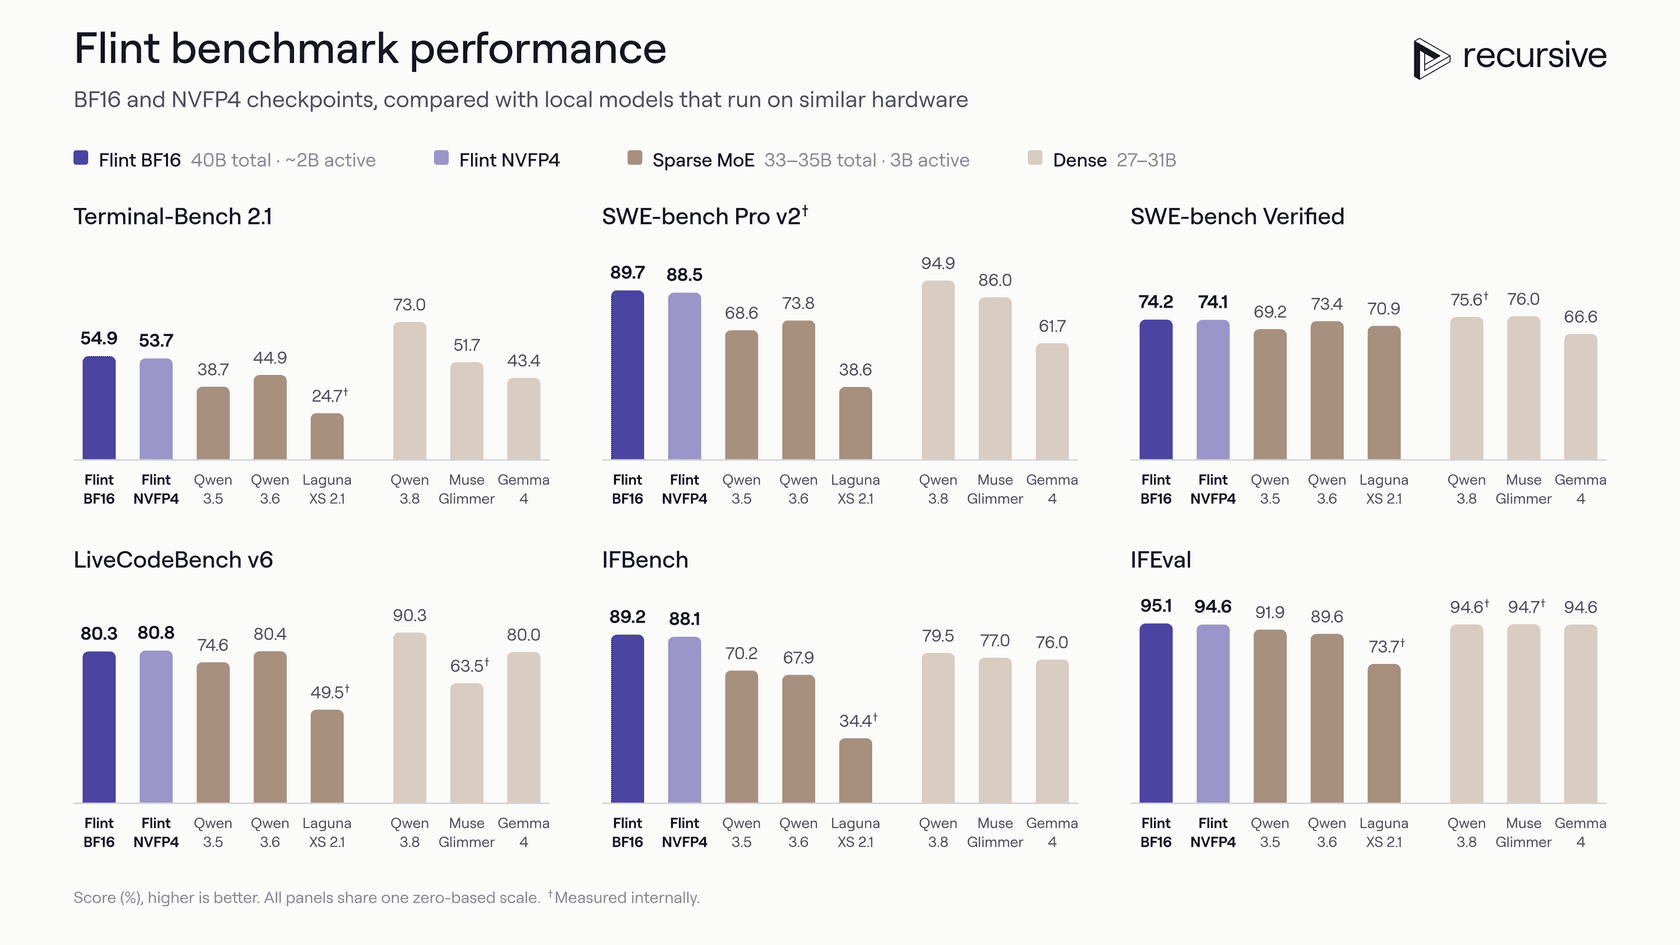
Here's where the launch copy and the chart part ways. Recursive says Flint "rivals the coding performance of dense models with 25 to 40 billion parameters." On its own chart, it trails the strongest of those, Qwen 3.8 27B, on most of the tests that matter for agentic coding.
| Benchmark | Flint BF16 | Qwen 3.8 27B (dense) | Muse Glimmer (dense) | Gemma 4 (dense) | Qwen 3.6 35B-A3B (MoE) |
|---|---|---|---|---|---|
| Terminal-Bench 2.1 | 54.9 | 73.0 | 51.7 | 43.4 | 44.9 |
| SWE-bench Pro v2 | 89.7 | 94.9 | 86.0 | 61.7 | 73.8 |
| SWE-bench Verified | 74.2 | 75.6 | 76.0 | 66.6 | 73.4 |
| LiveCodeBench v6 | 80.3 | 90.3 | 63.5 | 80.0 | 80.4 |
| IFBench | 89.2 | 79.5 | 77.0 | 76.0 | 67.9 |
| IFEval | 95.1 | 94.6 | 94.7 | 94.6 | 89.6 |
Read it honestly and three things stand out:
- Against other MoE models its size, Flint wins clearly. It beats Qwen 3.6 35B-A3B on five of six rows (LiveCodeBench is a 0.1-point tie), and by
10points on Terminal-Bench. That's the claim Recursive leads with, and it holds. - Against Qwen 3.8 27B, it loses four of six. The
18.1-point gap on Terminal-Bench 2.1 is the one I'd weigh most, since that test is closest to "drive a shell until the task is done." - Its standout is instruction following.
89.2on IFBench is nearly10points clear of every dense model on the chart, which fits the docs' advice to give it explicit, step-by-step instructions.
Recursive is upfront about the methodology, which I appreciate. Per its model card, the Terminal-Bench run counts solutions found through web retrieval as failures, and the card notes that developer-reported scores for other models may not apply the same adjustment. So some of that gap could be a stricter grader. Some of it, though, is just a 27B dense model doing more thinking per token.
That's the real trade. Flint is 10x faster for an answer that's somewhat worse. For an interactive coding loop, where you're reading every diff anyway, I'd often take that deal. For an unattended overnight agent, I wouldn't.
Where does Flint fall short?
The limits are mostly ones Recursive itself documents, which is a good sign about the lab, if not about the model.
It needs a tighter leash than frontier models. The launch post says it plainly: "it may need more guidance than the larger closed-source coding models you're used to," and recommends breaking work into smaller subtasks with explicit instructions. If you're used to handing Claude Code or Cursor a vague ticket and walking away, expect more back-and-forth.
Tool calls trip more than you'd want. OpenRouter reports a 17.74% tool call error rate for the free endpoint. In a 30-step agent loop, that's several broken calls per task for your harness to absorb. The docs point at mismatched chat templates and parsers as the usual cause, and the model card asks you to preserve reasoning_content in history, so some of this is fixable on your side. Still, it's the first number I'd watch.
Long reasoning eats the budget. Reasoning is always on. The model card recommends at least 32,768 output tokens for hard problems, and the OpenCode guide suggests 65,536. If your harness caps output lower, responses end with finish_reason: length mid-thought, the same budgeting problem I walk through in Claude Code's context window.
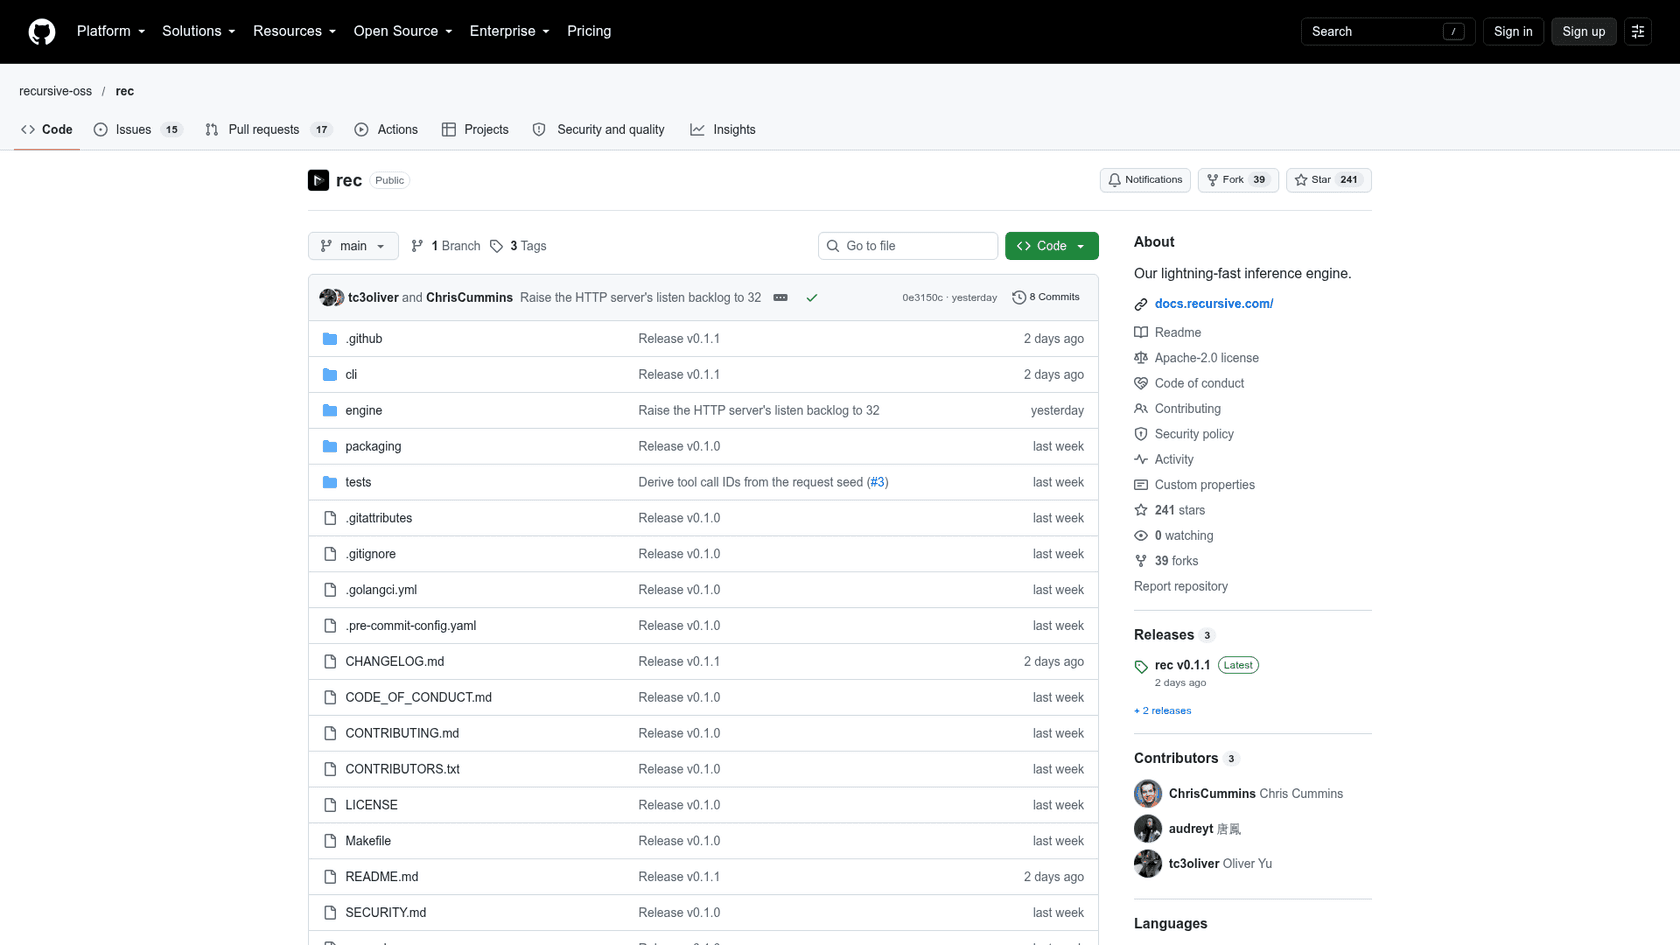
The fast path is Mac-only, and not every Mac. rec needs an M4 Pro, M4 Max, M5 Pro or M5 Max with at least 48 GB of unified memory, per its README. A 24 GB machine can load the smallest GGUF through LM Studio, but LM Studio's own listing warns the full 262K context isn't guaranteed to fit.
There's no paid API with an SLA yet. Direct Recursive API access is "limited to select partners," per the releases page. The free tiers on OpenRouter and OpenCode are subject to capacity and rate limits. That's fine for a trial, not for anything you bill a customer on.
The community reaction lines up with the chart. The Hacker News launch thread was impressed by the from-scratch speed, with a dose of "show me":
"Pretty amazing for being trained from scratch, to have ~Qwen 3.8 27b quality with such an increase in tok/s performance. Excited to try it out and see how snappy it is."

"not as good as qwen3.8 yet, even the chart says good numbers"
Both are fair. I'd put it between them: close enough to Qwen 3.8 that speed decides it for interactive work, not close enough that it decides it for everything.
How do you run Recursive Flint?
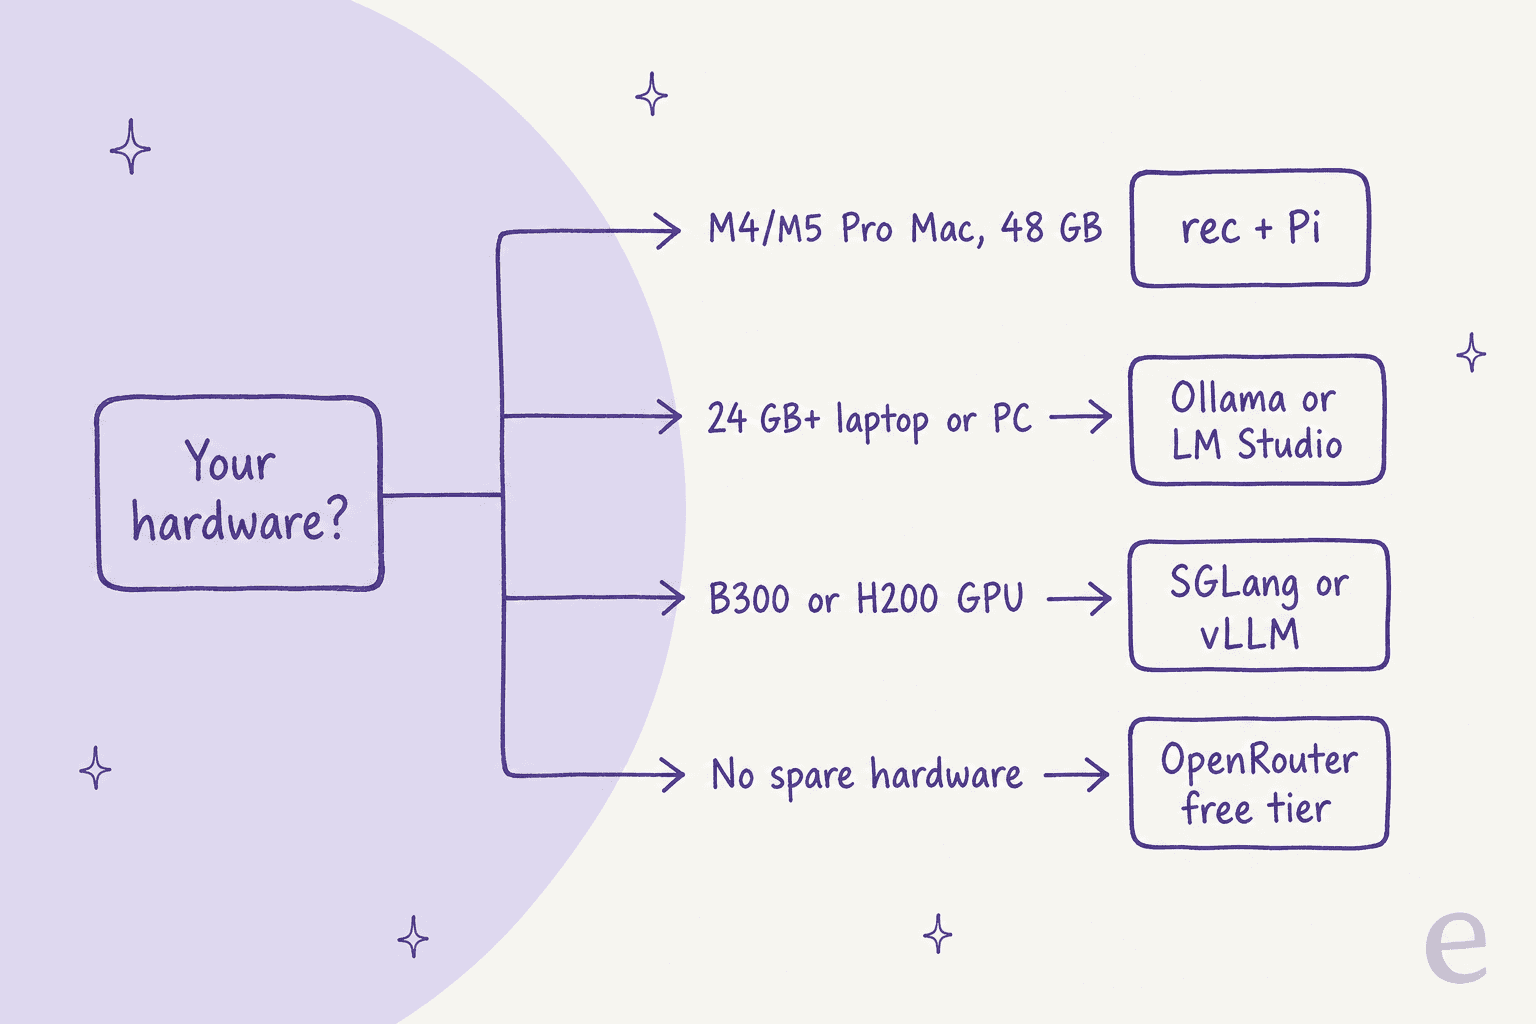
You have four routes, and your hardware picks one for you.
1. A supported Mac: use rec. This is Recursive's own engine, and its README claims 1.4 to 2.6x the throughput of llama.cpp on an M4 Pro. Install it with one curl command, then run rec launch pi from your project folder. It downloads the model (about 30 GB of disk) and the Pi harness, and starts a local server that speaks both OpenAI- and Anthropic-compatible APIs. Recursive says Flint performs best paired with Pi; rec launch opencode is the alternative. One catch: rec is built for a single session, so running several agents at once means a different runtime.
2. Any decent laptop or PC: Ollama or LM Studio. ollama run flint:40b-a2b-qat-int4 pulls Recursive's packaged 4-bit build, and ollama launch opencode, pi, codex or vscode wires it into a harness, per the Ollama guide. LM Studio has a 24.20 GB GGUF with a 24 GB RAM minimum. Expect speeds closer to the llama.cpp bars than the MLX ones.
3. A GPU server: SGLang or vLLM. The Hugging Face repo holds the roughly 80 GB BF16 checkpoint plus an SGLang serving kit that runs one replica on a single B300 or H200. The repo has already collected 93 community quantizations and 14 finetunes, so there's a lot to choose from if Recursive's own builds don't fit your stack.
4. No spare hardware: the free hosted tiers. OpenRouter lists recursive/flint-v1.0:free at zero cost, and OpenCode's model picker has Flint-40B on its free tier. The busiest apps on OpenRouter's page are coding agents: Kilo Code has pushed 32.9B tokens through it in a week, Cline 12.2B. If you just want to see whether Flint's style suits you, this is the five-minute test.
Whichever route you take, Recursive's suggested first task is a good one: open a small repo you know, ask Flint to explain one function, add a test, then fix whatever the test exposes. Check the diff after each step.
How much does Recursive Flint cost?
Nothing, in licence terms. The weights are Apache 2.0, free for commercial use, and both hosted routes are free today. The real cost is hardware and electricity, and that's where Flint quietly saves money: a model that needs one 48 GB Mac instead of a GPU rack, and runs at 10x the speed of its dense peers on that Mac, gets more work done per hour of a machine you already own.
| Route | Price | Limits |
|---|---|---|
| Weights on Hugging Face | Free (Apache 2.0) | ~80 GB BF16; quantized builds for Mac and NVIDIA |
| rec on a Mac | Free | M4/M5 Pro or Max, 48 GB+, single session |
| Ollama / LM Studio | Free | 24 GB RAM minimum for the smallest GGUF |
OpenRouter flint-v1.0:free | $0 input, $0 output | One provider, capacity and rate limits apply |
| OpenCode free tier | $0 | Capacity and rate limits apply |
| Direct Recursive API | Not public | Select partners only |
Compare that to hosted frontier models, where a long agentic coding session can run into dollars per task. My Kimi K3.1 Pro pricing breakdown puts its per-task cost at about $2.11. If you're running dozens of small, well-scoped tasks a day, a free local model that's good enough changes the maths fast.
Who should use Recursive Flint, and who should skip it?
Here's my verdict, and the deciding factor is how much of the thinking you're willing to do yourself.
Use Flint if:
- You want a coding agent that works offline and keeps your code on your machine, and you own a 48 GB M4 or M5 Pro/Max Mac.
- You work interactively, reading each diff, and value a model that answers in seconds over one that answers slightly better in a minute.
- You're building on open weights and need a commercially permissive licence for finetuning or redistribution, the same reason teams reach for open-source AI agents.
Skip it, for now, if:
- You want the strongest local model per answer. Qwen 3.8 at 27B dense still wins on most coding tests, at a tenth of the speed; my Qwen alternatives list covers the rest of that family's rivals.
- You run long, unattended agents where a broken tool call costs you a whole run.
- You need a supported, paid API with an SLA. That doesn't exist yet, so a hosted tool like GitHub Copilot or Windsurf is the safer buy.
If you're weighing Flint against hosted options, my Kimi K3.1 Pro review and DeepSeek V4 Flash review cover the nearby alternatives, and AI coding assistant tools covers the harnesses you'd run them in.
For other open models worth a look this month, see Nemotron 3.5 Bolt, LFM3 and Nanbeige 4.3.
The bigger story is the lab, not the model. A from-scratch 40B model in under four months, with an automated system doing much of the research, is the claim to watch. Recursive's bet is that each model makes the Eureka Machine a better researcher. If Flint 2 closes the Qwen gap at the same speed, this review gets a lot more positive.
What Flint means if you run a support team
Flint is infrastructure: a model that a coding agent runs on. Even picking a model for support is its own question, which I cover in my LLMs for customer support guide. If your problem is a support queue rather than a codebase, the model was never the hard part. The hard part is everything around it: connecting to Zendesk or Freshdesk, learning from your past tickets, knowing when to hand off, and proving it won't give a confidently wrong answer before a customer sees it. eesel has spent years putting AI agents on live support queues, and the lesson I see relearned most is that every rollout has to be simulated against historical tickets before it goes live.
That's what eesel's AI teammates are, and why I'd point a support lead at them before any AI agent toolkit: ready-to-work employees for a defined job, not a model you assemble a product around. The AI helpdesk teammate is the one for support.
SE Ranking, for example, runs three eesel agents on three Zendesk connections, one per product, and handled 4,650 conversations in a month, including about 2,100 live chats answered first by eesel. SamCart runs one agent on Freshdesk tickets and another on its website chat, answering from 280 help center articles.
And here's where the two worlds meet. eesel has a CLI, so the same coding agent you'd run on Flint, Claude Code or Codex can operate your support teammate from a terminal: eesel activity to read what the agent did on each ticket, eesel instructions to change its standing rules, eesel approvals to sign off on actions it's waiting on. Every command prints JSON, and --dry-run shows the exact call a write would make before it sends. The docs go as far as telling AI agents to use the CLI instead of clicking through the dashboard. If you're curious how this compares to rolling your own, I wrote up AI agent CLIs and the MCP server route separately.
Try eesel
Want an AI for your helpdesk without building one on a raw model? eesel's helpdesk teammate plugs into Zendesk, Freshdesk or Gorgias in minutes, learns from your past tickets and help center, and gets tested against them before it answers anyone. Every action shows up in an activity log you can read in the dashboard or pull from the CLI. It's free to start, no card needed.
