What Grok 4.5 actually is
Grok is xAI's assistant and API platform, and 4.5 is the newest flagship in the line. xAI's own docs describe it as "SpaceXAI's frontier model built for coding, agentic tasks, and knowledge work" (the company now renders its name as "SpaceXAI" across its properties, though the model is still just Grok). On the models overview they lead with three words that tell you who it is for: "agentic tool calling, minimal hallucinations, configurable reasoning."
A few things are new versus the Grok 4 line:
- A 500K-token context window, which the model page confirms, with a higher rate kicking in above the 200K threshold. That is roughly a small book of context in one request.
- Configurable reasoning through a
reasoning_effortsetting with low, medium, and high (high is the default), so you can trade latency for depth per call. - Minimal hallucinations as an explicit design claim, which xAI puts front and center rather than burying in a footnote.
- Multimodal input, taking text and images in and returning text, per the model detail page.
- Server-side tools built in, including function calling, web search, X search, and code execution straight through the API.
It is already available in a lot of places on day one: the xAI API, as the default model in xAI's Grok Build coding agent, inside Cursor, as the default in the Microsoft Office add-ins, and through gateways like OpenRouter and Vercel. EU API access was the one gap at launch, listed as "expected later this month."
If you have read our take on Anthropic's Claude updates for support, the shape here is familiar: a strong coding-and-agent model, priced to compete, arriving into a market where the leaderboard reshuffles every few weeks.
The benchmarks: hype versus where it actually lands
This is where a hype post usually waves its hands. Let me not. The numbers below are Artificial Analysis's independent measurements of Grok 4.5 (high), which is a cleaner citation than any launch-day chart from the vendor.

Here is the honest read of the Artificial Analysis scorecard:
- Intelligence Index: 54, ranked #4 of 168. It sits just behind Claude Fable 5 (60), Claude Opus 4.8 (56), and GPT-5.5 (55), and ties Claude Opus 4.7 (54). That is well above the ~29 class average, so #4 is a very good result, just not #1.
- Agentic tool use: 33%, the single best score of any model charted, ahead of GPT-5.5 and Claude Sonnet 4.6. This is Grok 4.5's real standout, and for support automation it is the most relevant number on the page.
- GPQA Diamond (scientific reasoning): 93%, in the top cluster.
- Terminal-Bench (agentic coding): 82%, fifth, behind the top Claude and GPT releases.
- Speed: 85.6 output tokens per second, faster than the ~73 average, and notably concise in how much it generates.
The gap between the hype and the scorecard is worth naming. During launch, Cursor's CEO called it an "Opus-class model" that is "fast and low cost," which is a fair line, though worth remembering Cursor co-launched the model. The independent numbers land it a hair below Opus 4.8 on raw intelligence and clearly on the cost-versus-performance frontier. So the sober version is: Opus-class intelligence per dollar, not Opus-beating intelligence. For most buyers, per-dollar is the number that actually matters.
How much Grok 4.5 costs
Grok 4.5 is priced to undercut, and it mostly does. Here is the full picture from xAI's pricing docs and the model page.
| Plan | What it is | Input | Output | Notes |
|---|---|---|---|---|
| Grok 4.5 API | Pay-as-you-go tokens | $2.00 / 1M | $6.00 / 1M | Cached input $0.50 / 1M (−75%); 500K context; higher rate above 200K |
| Grok (free) | Consumer app | - | - | Limited daily usage on grok.com, X, iOS, Android |
| SuperGrok | Consumer subscription | - | - | ~$30 / month for higher limits (dollar figure community-reported, not confirmed on a primary page) |
| SuperGrok Heavy | Top consumer tier | - | - | ~$300 / month (community-reported; grok.com renders no price text to confirm) |
The API number is the one to anchor on because it is confirmed on xAI's own docs. At $2 in and $6 out, Grok 4.5 is cheaper than most frontier peers while scoring in their neighborhood, which is the whole pitch. On Hacker News, one commenter summed the reaction up flatly:
"Pretty decent, comparable with some older opus models, and fairly cheap per token."

Cheap per token is real, but it is also where a lot of AI-support math goes wrong. Token price is not the same as cost per resolved ticket. A concise model that answers in one clean turn can be cheaper in practice than a "cheaper" model that loops, retries, and escalates. We pulled that thread apart in how much an AI support agent costs, and the short version is that the unit you should price on is a solved conversation, not a million tokens.
What people are actually saying
Because Grok 4.5 is hours old, the verifiable chatter is concentrated on Hacker News and X rather than the usual review sites. The sentiment splits into three clear camps.
The fans like the intelligence-per-dollar. Artificial Analysis noted it "scores 54 to place fourth" while sitting "clearly on the Pareto frontier" for cost.
The skeptics are blunt, and their gripe is less about capability than about trust in a business setting:
"I just don't think that I can ever trust an xAI model knowing that they are actively trying to shape its replies to fit a political narrative. How can you trust their models to be reliable in a business setting with the foreknowledge that their models are being nudged around in the backend?"
There is a fair counter to that in the same thread, from someone who had tested it:
"Grok has in most of my testing been MORE politically correct than GPT and Gemini... on grok.com or in the app Grok is very tame. Boringly so, I would add."
And then there is the reality-check camp, testing the coding pitch by hand rather than on a leaderboard:
"So strange to write a whole post with Claude giving the best results and Grok consistently the worst, but awarding Grok the winner because at least it did the worst fastest?"
Put together, the community read is "cheap, fast, credible, unproven, and, for some, hard to trust." That last point is the one a support leader should sit with, because trust is the whole job when a model is talking to your customers.
What a new model changes for customer support (and what it doesn't)
Here is the part I care about most, because I spend my time thinking about how search intent turns into real buying questions, and "should I switch my support AI to the new model?" is one people are typing today. The honest answer: the model tier is rarely what decides whether AI support works.
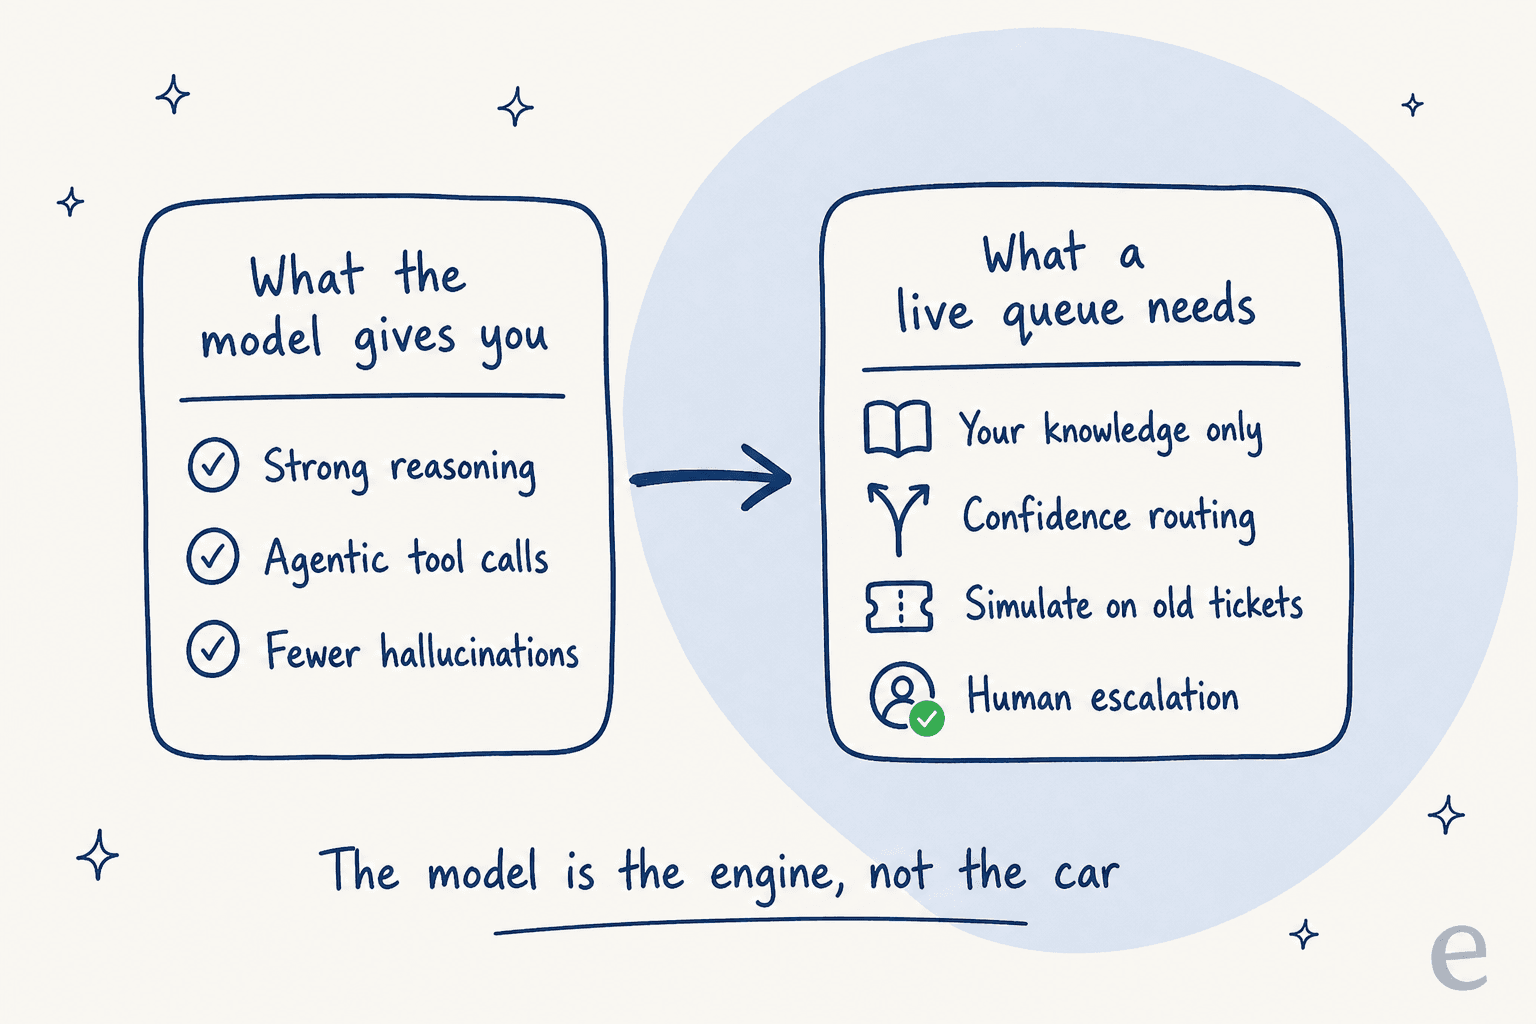
A frontier model gives you three things: strong reasoning, agentic tool calls, and fewer hallucinations. A live support queue needs four more that no model ships with: answers scoped to your knowledge only, confidence-based routing so it stays quiet when unsure, a way to simulate against your real ticket history before go-live, and clean escalation to a human. We have spent the last three-plus years putting AI agents on live support queues, and the pattern never changes: the wins and the disasters both come from that second list, not the first.
Take "minimal hallucinations." Fewer is better, and Grok 4.5 earning that claim is good news. But fewer is not none, and the failure mode on a support queue is specific.
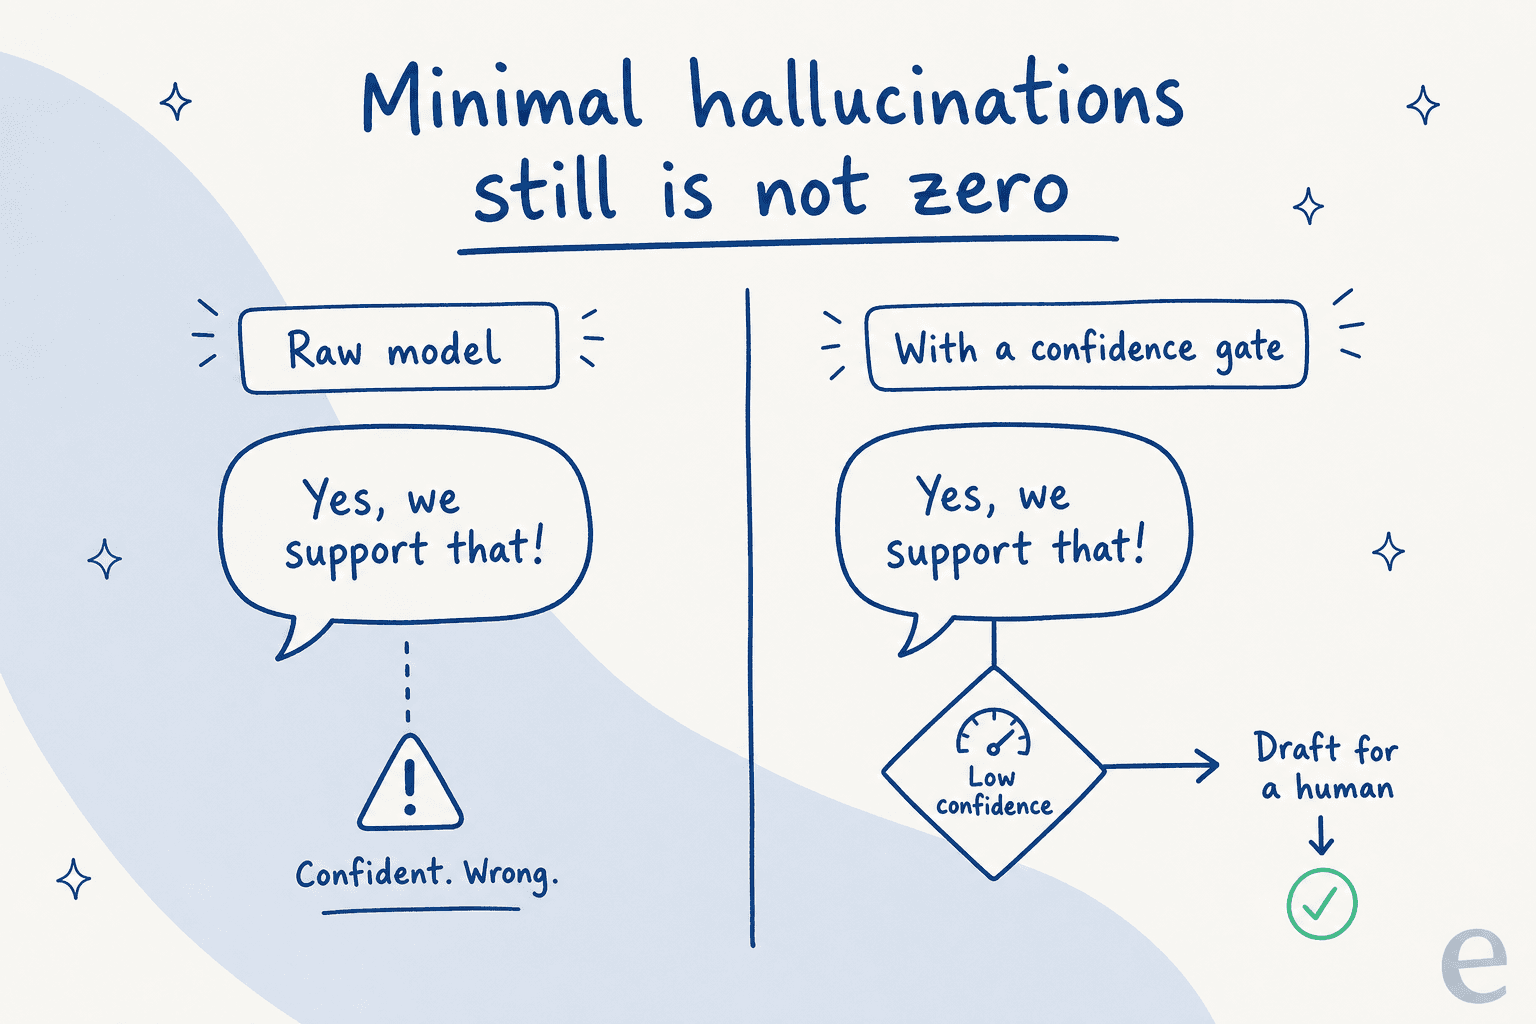
One team we worked with, a B2B vehicle-telematics support group on Zendesk doing around 200 tickets a month and scaling toward 2,000, watched their bot cheerfully confirm it supported car brands that were not in their database, because a help-center line said "we support all models." No frontier model fixes that on its own. It is a knowledge-scoping and confidence problem, and it is solved by gating low-confidence answers into a draft for a human instead of auto-sending them. A CX lead at a DTC supplements brand put the principle better than I can:
"The AI will never be able to answer 100% of the questions. I need an AI who is only handling the tickets that it's confident to handle, and all the other ones, leave them alone."
That is the whole game, and it is a workflow problem, not a model problem. This is why confidence-based routing and hallucination guardrails matter more to your resolution rate than which model sits underneath. It is also why the trust worry from Hacker News is a real buying signal: if you cannot control what the model does, you cannot put it in front of customers, no matter how it benchmarks. When you own the knowledge, the routing, and the simulation step, the underlying model becomes a swappable part.
Try eesel
If Grok 4.5 has you wondering whether to rebuild your support stack, the better move is to make the model a detail you can change later, not a decision you have to bet on now. eesel is the layer that does that: it learns from your past tickets and help docs on day one, scopes answers to your knowledge only, routes on confidence so it stays quiet when unsure, and lets you simulate against thousands of your real historical tickets before it replies to a single customer.
That is how teams get real numbers rather than leaderboard numbers. Gridwise saw eesel resolve 73% of tier-1 requests in the first month, with signal showing up during a 7-day trial. You can point it at Zendesk, Freshdesk, Gorgias, or Front, start it in draft mode, and grant it autonomy only on the tickets it earns. The new model is exciting. The plumbing is what pays off. You can try eesel free, with $50 of usage and no credit card.
Frequently Asked Questions
What is Grok 4.5 and when did it launch?
How much does Grok 4.5 cost?
Is Grok 4.5 better than Claude or GPT?
Can I use Grok 4.5 for customer support?
Does Grok 4.5 hallucinate less than older models?


Article by
Kurnia Kharisma Agung Samiadjie
Kurnia is a software engineer and writer at eesel AI with two years of SEO experience, writing about AI tools, helpdesk software, and customer support. He pairs a developer's understanding of how these products are built with search-driven research into what actually ranks and resonates with the people searching for them.