What StepFun Step 5 Preview actually is
I have spent the last few years putting AI on live support queues, so I read every model launch the same way: not "is the benchmark pretty," but "could I hand this a real job tomorrow." Step 5 is a genuinely interesting model, and it is also a good example of why that second question matters.
StepFun (阶跃星辰) is a Shanghai lab that has been shipping the "Step" family across text, vision, and audio for a couple of years, with a healthy open-weights footprint on Hugging Face. Step 5 Preview is its new flagship, described on the product page as a frontier model "for complex work and agentic tasks," with a particular lean toward software engineering and finance.
The framing StepFun keeps coming back to is "advancing the Pareto frontier," the line of best possible intelligence-for-your-money trade-offs. Their own launch chart says it plainly: match the cheaper open tier on intelligence, undercut it on cost.
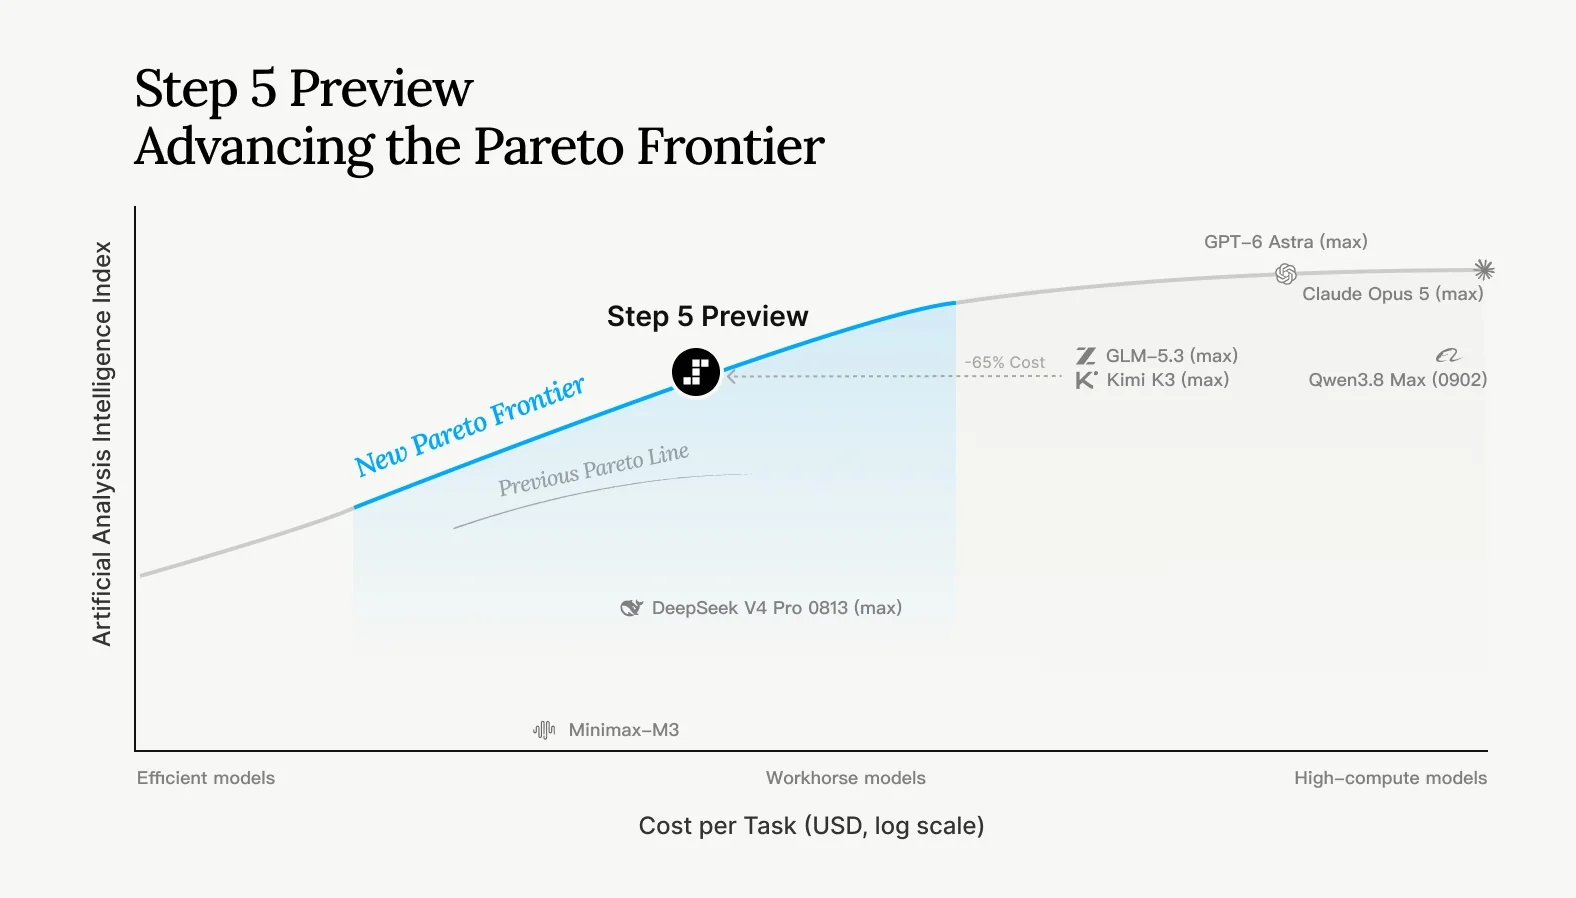
Note the claim baked into that chart: a 65% lower cost than GLM-5.3 and Kimi K3 at a comparable intelligence level. It is a vendor chart, so read it as the pitch rather than the verdict, but the pitch is at least a coherent one.
How the sparse MoE works: 600B total, 27B active
The headline spec that everyone latched onto is the shape of the model: 600B total parameters, 27B active per token. That is a sparse mixture-of-experts design, and it is the whole cost story in one number.
In a dense model, every parameter runs for every token. In a mixture-of-experts model, a small router picks a handful of "expert" sub-networks for each token, so only a slice of the model actually fires. Step 5 holds a frontier-sized 600B in memory but only lights up 27B of it at a time, which is why StepFun can price it like a mid-tier model.
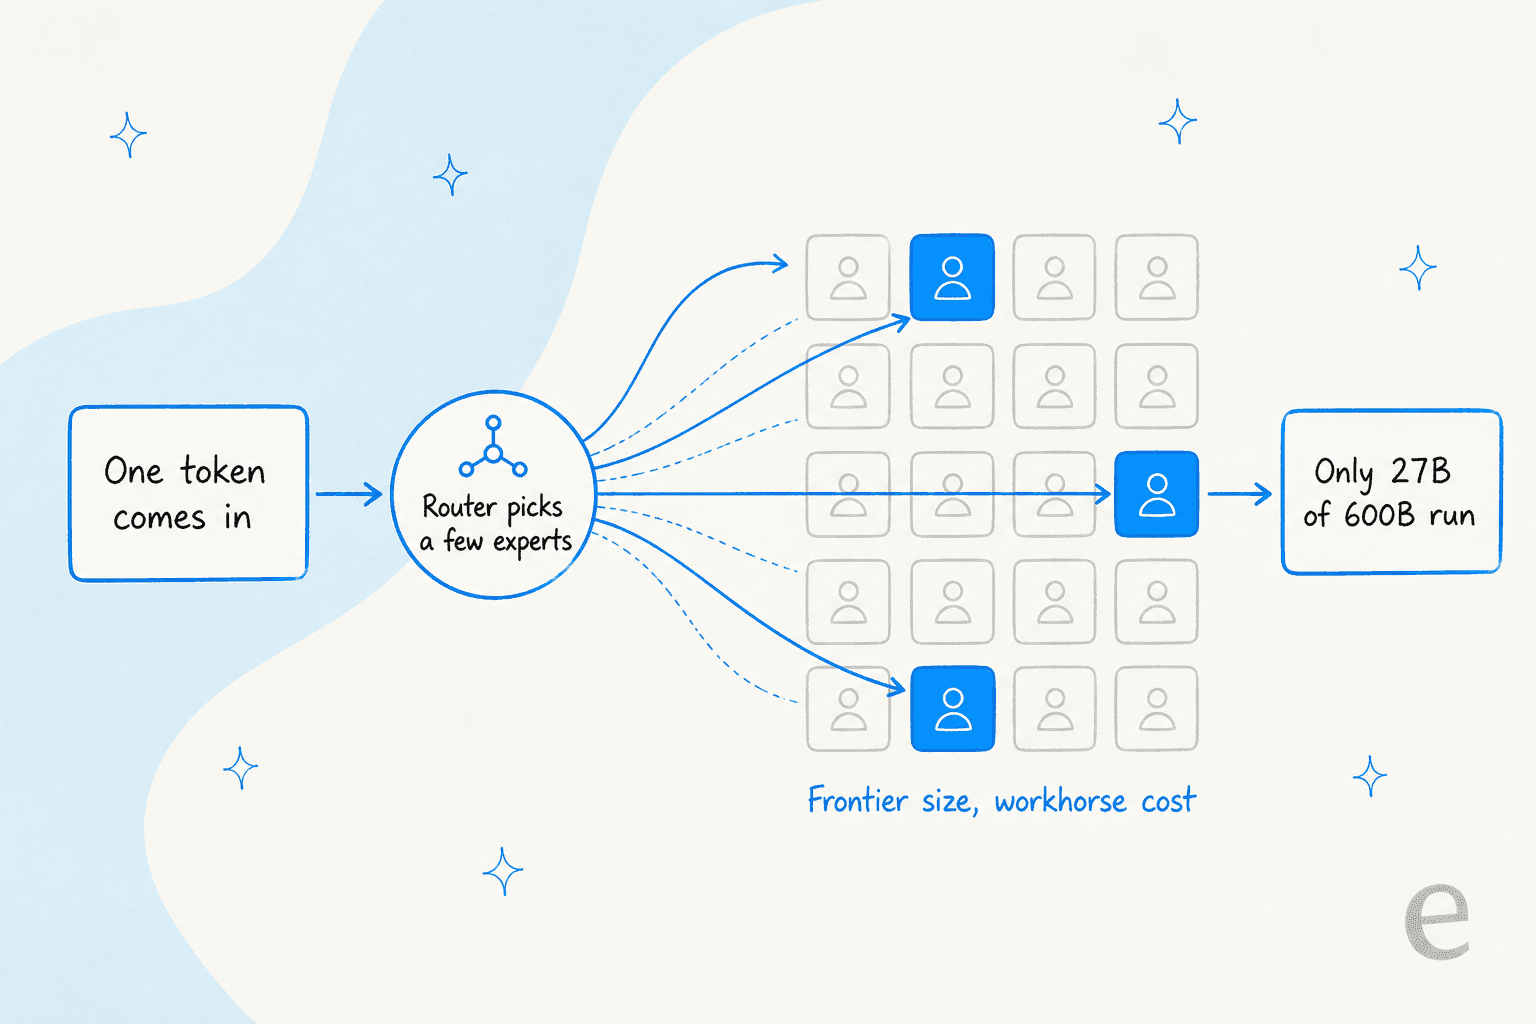
Not everyone buys that the math nets out in Step 5's favor. The active-parameter count came up fast on Hacker News:
"600b-a27b doesn't sound enticing. Also with the higher number of active parameters compared to GLM 5.3 flash and DeepSeek V4/4.1 flash, I don't see how they want to be more efficient at inference."

That is a fair challenge. 27B active is heavier than some rival "flash" tiers, so the efficiency win is really about the intelligence you get per active parameter, not the active count on its own. It is exactly the kind of thing independent inference benchmarks will settle, and StepFun's own charts will not.
It is a reasoning model too, with a reasoning_effort control set to low, medium, or high. Higher effort means a longer internal thinking trace, and because output tokens are billed inclusive of that trace, effort is a direct cost dial.
What it can do: context, modalities, and capabilities
Here is the spec sheet from StepFun's own platform docs, which is the part most relevant if you are actually thinking about building on it.
| Spec | Step 5 Preview |
|---|---|
| Model ID | step-5-preview |
| Architecture | Sparse MoE, 600B total / 27B active |
| Context window | 1M tokens |
| Max output | 64k tokens |
| Input types | Text, images, video |
| Output type | Text |
| Reasoning | reasoning_effort: low / medium / high |
The 1M-token context is the spec I would lean on hardest. It is enough to drop an entire codebase, a quarter of support transcripts, or a stack of PDFs into a single call and ask for cross-document reasoning. On the multimodal side you can pass up to 60 images per request, plus short video clips, though output is text only.
StepFun leans hard into the coding story. It claims Step 5 can go "from software engineering and visual applications to programmable hardware," and that in expert evaluations about 70% of participants judged it capable of autonomously solving coding tasks of moderately high complexity. There is also a Claude Code integration through "Step Plan" that exposes the full 1M context, which is a smart place to meet developers.
The benchmarks, and the honest caveat
StepFun published a full comparison table against both open peers (Kimi K3, GLM-5.3) and the closed frontier (GPT-6 Astra, Claude Opus 5). Here is the shape of it, all numbers from StepFun's own product page.
| Benchmark | Step 5 Preview | Kimi K3 | GLM-5.3 | GPT-6 Astra | Claude Opus 5 |
|---|---|---|---|---|---|
| DeepSWE v1.1 | 67.7 | 67.5 | 66.9 | 74.1 | 74.0 |
| StepCodeBench | 49.0 | 43.9 | 40.2 | 61.0 | 63.9 |
| ProgramBench | 80.5 | 77.8 | 72.0 | 85.4 | 82.3 |
| Terminal-Bench v4 | 33.3 | 12.6 | 41.9 | 57.9 | 52.3 |
| FrontierFinance | 66.4 | 62.6 | 64.1 | 55.0 | 69.7 |
The read is consistent: Step 5 Preview sits at parity with the other leading open models and behind the top closed models on raw coding quality, while winning on cost. Finance is its standout, where it edges the other open models and beats GPT-6 Astra. Its own StepCodeBench radar tells the same story against the open tier.
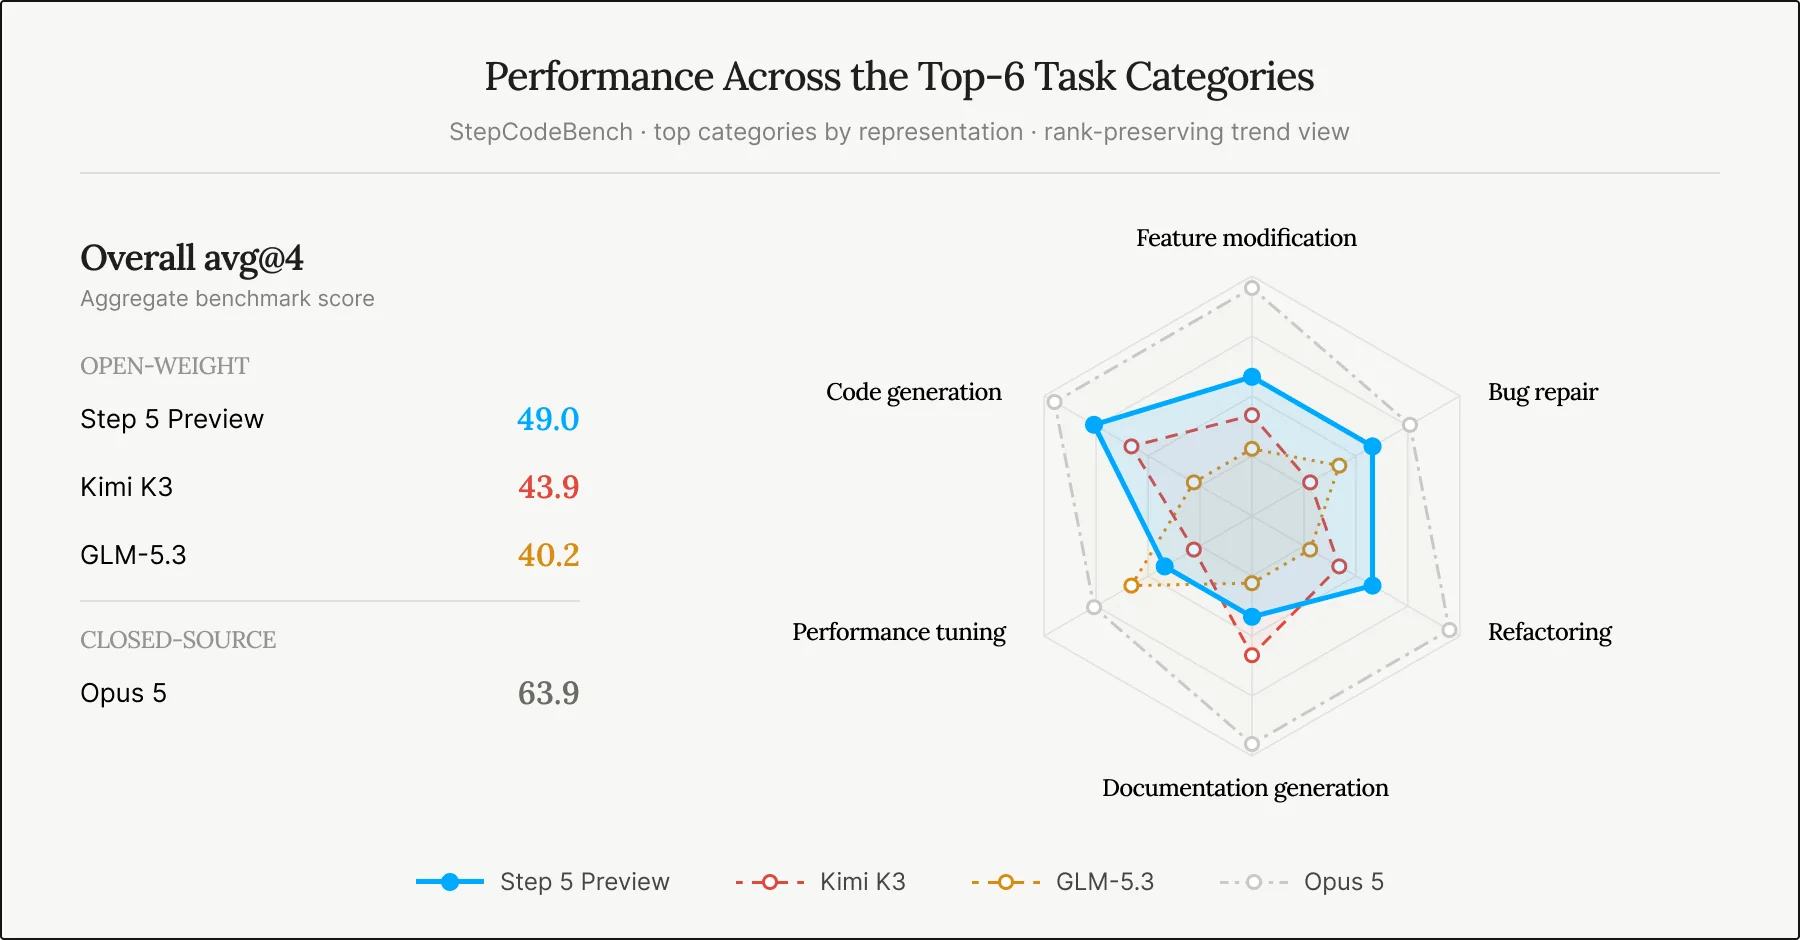
Now the caveat, because it is a big one. Every number above is self-reported, there is no technical report or paper yet, and StepCodeBench is StepFun's own benchmark (553 repositories, 33 languages). A model tends to look good on the test its own team designed. The community was quick to flag the softer spots too, especially around verbosity:
"Based on the examples, it's like the thing took a writing class from Claude, but isn't quite as smart, kind of worst of both worlds. The 'Interactive Reporting' one is particularly terrible. A huge amount of waffly padding around a thesis that may or may not exist."
And one commenter caught the launch demo giving itself away, which is the kind of thing that makes me want to run my own evals before trusting anything:
"In their first demo video, to make a 3D render of the photo, the thinking trace gives away the game [...] I'm always astounded how little effort is put into checking the AI answers displayed in these announcements."
None of that makes Step 5 a bad model. It makes it an unproven one, which is a different thing, and the correct response is to simulate it against your own workload rather than take the launch chart at face value.
What it costs and how to get it
Pricing is the part of this launch that is genuinely easy to like. From the StepFun pricing page, per 1M tokens:
| Billing unit | Input (cache miss) | Input (cache hit) | Output |
|---|---|---|---|
step-5-preview | $1.00 | $0.05 | $2.70 |
step-3.7-flash (for context) | $0.20 | $0.04 | $1.15 |
The 95% cache-hit discount on input is the standout, and it is a big deal for agentic workloads that re-send a large, mostly-static system prompt on every step. Output at $2.70 covers both the reasoning trace and the final answer, so a chatty high-effort run costs real money. There is a free V0 tier for kicking the tires (5 concurrency, 10 requests per minute), with rate limits scaling by how much you have topped up.
Access is where the "Preview" label earns its keep. The model is API-only today, and StepFun is running a public countdown to open weights.
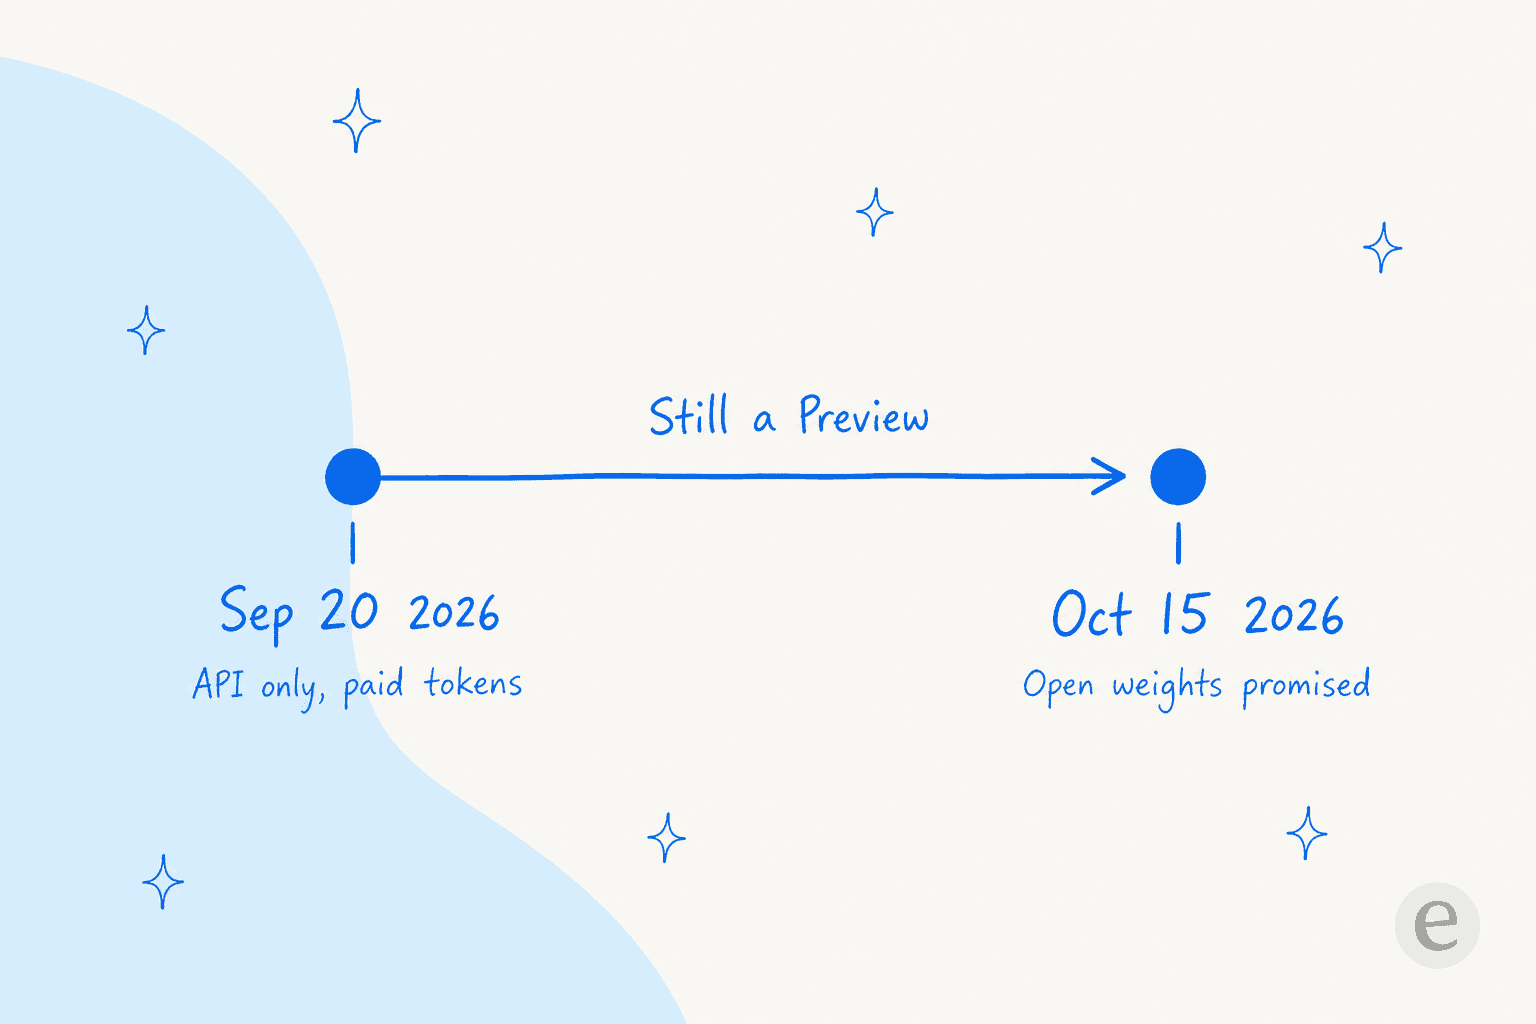
The Hugging Face repo already exists but is an empty placeholder with no model card, weights, or license as of writing. StepFun's Flash line shipped under Apache 2.0, so a permissive open release is likely, but I would not build an on-prem plan around weights that have not landed yet.
Who Step 5 is for, and who should wait
Here is where I would land. If you are a developer or a lab that wants a capable, cheap, long-context model to build on, especially for coding, finance, or research over big document sets, Step 5 Preview is worth a real test. The price-per-intelligence story is legitimately good, and the open-weights promise makes it more interesting still.
If you are waiting for a settled, proven model, wait. It is a preview, the benchmarks are self-graded, and the community's early read is "promising but verbose and unproven." Even a friendly commenter put the pattern gently:
"The previous Step models were pretty decent, but unfortunately for them, their model reasons too much and too long [...] Hopefully this doesn't reason too long to get to the answer. I welcome any open model, the more the merrier."
I will give StepFun credit for the one thing that most launches get wrong, which is knowing what they are. As one commenter put it, the positioning is honest about being the best of the cheaper tier rather than pretending to top the charts:
"Their posisitoning is nice. Instead of saying they are cheaper and a bit less performant (in terms of intelligence), they say they are best among the cheaper and a bit less performant ones."
Where a raw model stops and a teammate starts
There is one framing I would push back on, and it is not StepFun's fault, it applies to every model launch. A model is not a solution. Step 5 Preview is an engine. It gives you an API, a token bill, and raw capability. Turning that into something that answers your customers means you build the app, connect your data, write the guardrails, and own the maintenance.
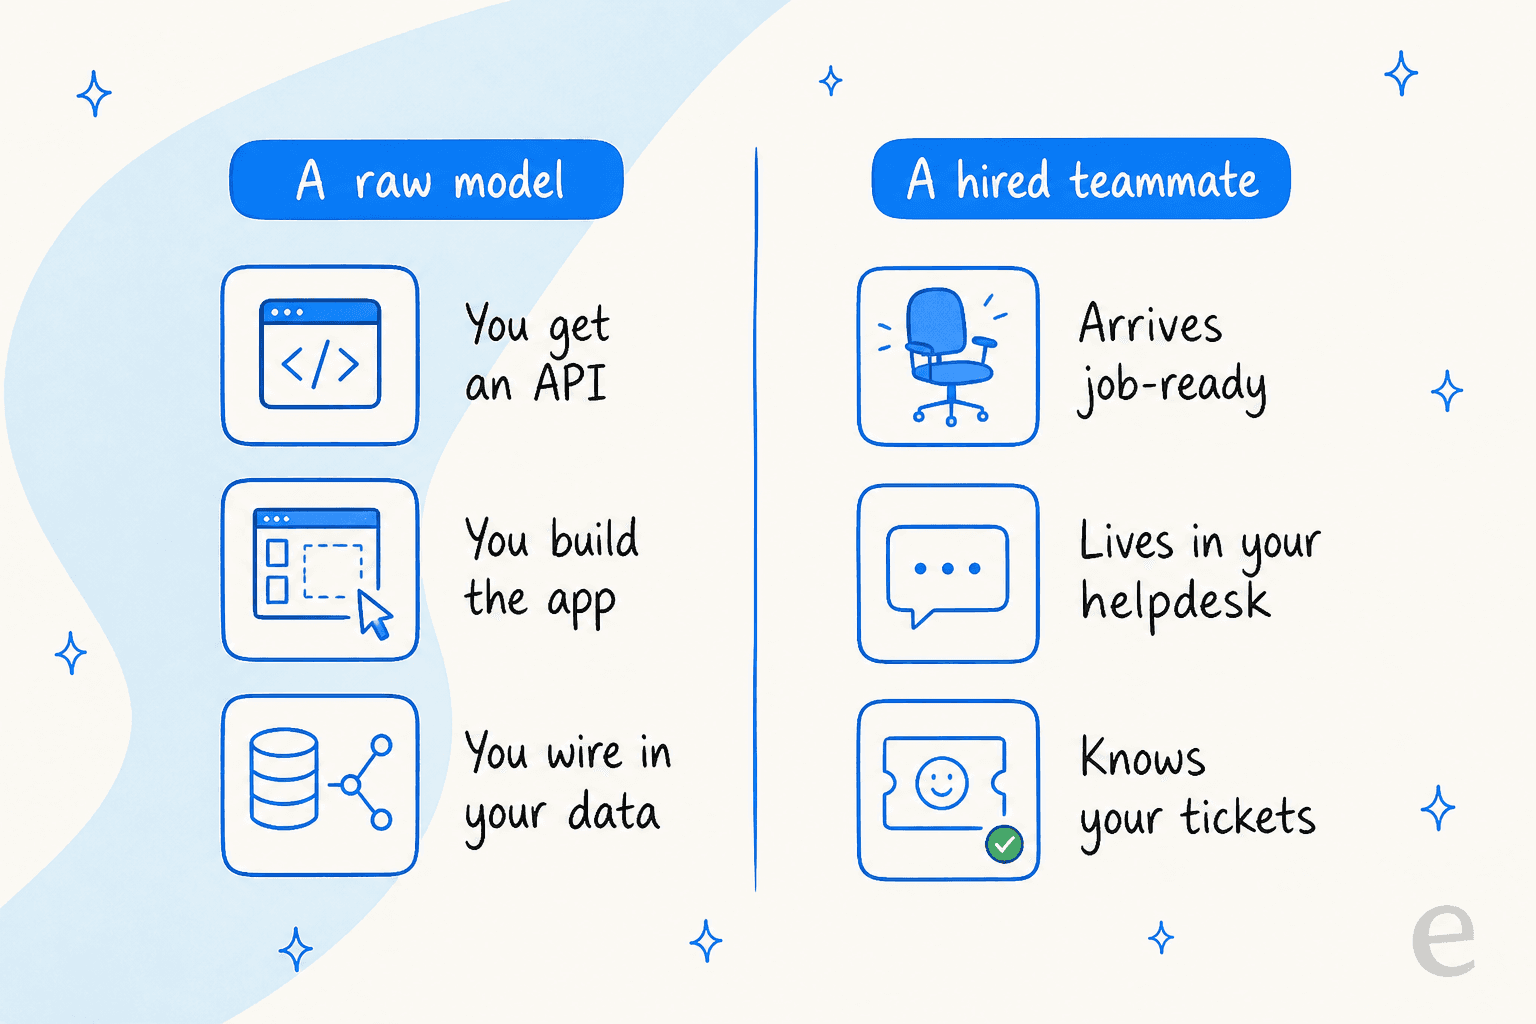
That gap is the whole reason eesel exists. Instead of a raw model, you hire a ready-to-work teammate for a specific job. The AI helpdesk teammate joins your existing queue, trains on your past tickets and help center, and drafts or sends replies inside the helpdesk you already run, whether that is Zendesk, Freshdesk, or Gorgias. Pricing is a flat rate per resolution with no per-seat fee, so the cost maps to work done rather than tokens burned.

The part I care most about, given the "self-reported benchmarks" problem above, is that you can simulate the teammate on thousands of your own past tickets before it ever touches a live customer, so you see its real resolution rate on your workload instead of a vendor's chart. And if you would rather drive it from a terminal or a script than a dashboard, eesel ships a real CLI and MCP server so coding agents like Claude Code can operate the same teammate directly. New models like Step 5 are exciting infrastructure. A teammate is what actually shows up for the shift. You can try eesel free.
Frequently Asked Questions
What is StepFun Step 5 Preview?
How much does StepFun Step 5 cost?
Is StepFun Step 5 open source?
How does StepFun Step 5 compare to GPT-6 Astra and Claude Opus 5?
Can I use StepFun Step 5 for customer support?


Article by
Alicia Kirana Utomo
Kira is a writer at eesel AI with a Computer Science background and over a year of hands-on experience evaluating AI-powered customer service tools. She focuses on breaking down how helpdesk platforms and AI agents actually work so that support teams can make better buying decisions.